Online Video Agent Harness for Long Video Understanding
Sen Yang and colleagues at Baidu build VideoXAgent, an online agent harness for long videos that plans from the query, calls expert tools on demand and aggregates evidence, instead of packing dense frames into one context.
Ask this paper
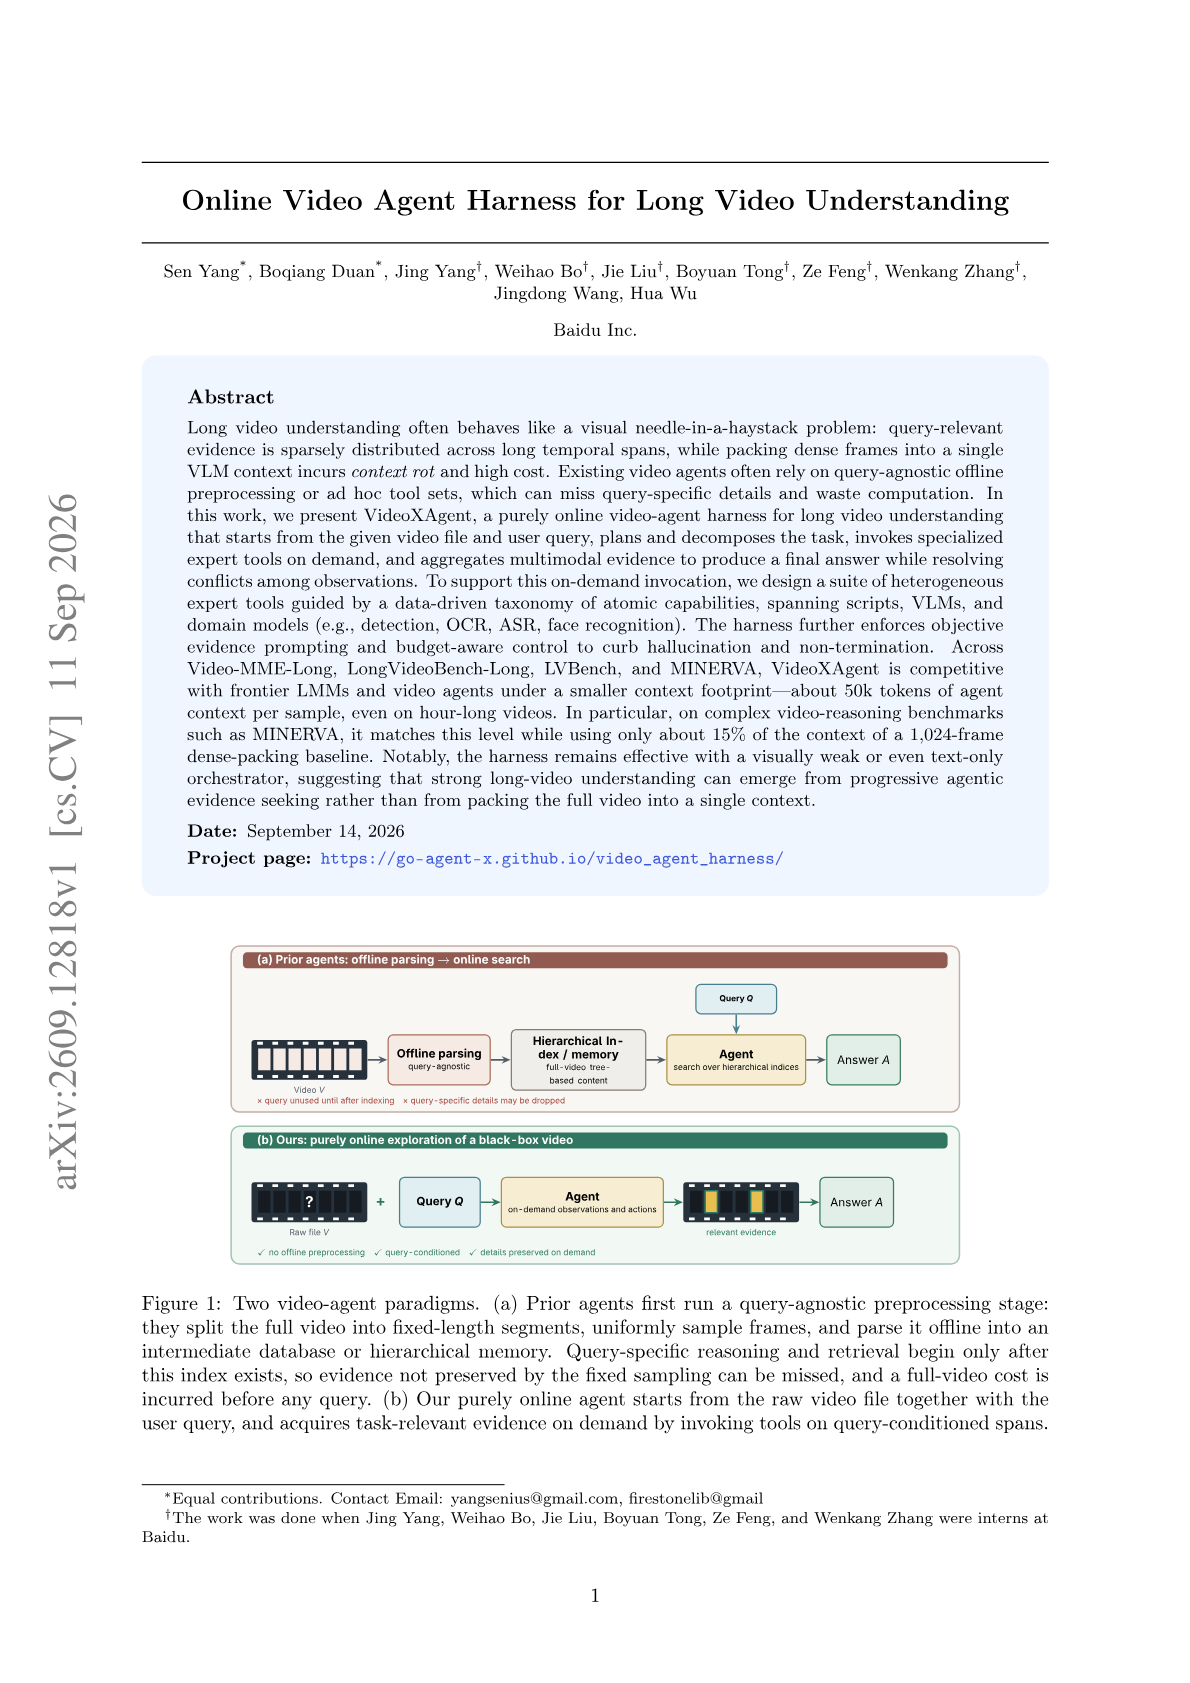
Online only: The agent starts from the raw video file and the query, with no query-agnostic preprocessing of the video.
Tool taxonomy: Expert tools, including scripts, VLMs, detection, OCR, ASR and face recognition, are chosen from a taxonomy of atomic capabilities mined from MINERVA reasoning traces.
Context footprint: The agent uses about 50k tokens of context per sample even on hour-long videos, and on MINERVA it uses about 15% of the context of a 1,024-frame dense-packing baseline.
Result: It is competitive with Seed-2.0-pro and Gemini-3.1-Pro on Video-MME-Long, LongVideoBench-Long, LVBench and MINERVA, and still performs well with a text-only orchestrator.
Abstract
Long video understanding often behaves like a visual needle-in-a-haystack problem: query-relevant evidence is sparsely distributed across long temporal spans, while packing dense frames into a single VLM context incurs \textit{context rot} and high cost. Existing video agents often rely on query-agnostic offline preprocessing or ad hoc tool sets, which can miss query-specific details and waste computation. In this work, we present VideoXAgent, a purely online video-agent harness for long video understanding that starts from the given video file and user query, plans and decomposes the task, invokes specialized expert tools on demand, and aggregates multimodal evidence to produce a final answer while resolving conflicts among observations. To support this on-demand invocation, we design a suite of heterogeneous expert tools guided by a data-driven taxonomy of atomic capabilities, spanning scripts, VLMs, and domain models (e.g., detection, OCR, ASR, face recognition). The harness further enforces objective evidence prompting and budget-aware control to curb hallucination and non-termination. Across Video-MME-Long, LongVideoBench-Long, LVBench, and MINERVA, VideoXAgent is competitive with frontier LMMs and video agents under a smaller context footprint---about 50k tokens of agent context per sample, even on hour-long videos. In particular, on complex video-reasoning benchmarks such as MINERVA, it matches this level while using only about 15\% of the context of a 1,024-frame dense-packing baseline. Notably, the harness remains effective with a visually weak or even text-only orchestrator, suggesting that strong long-video understanding can emerge from progressive agentic evidence seeking rather than from packing the full video into a single context. Project page: https://go-agent-x.github.io/video_agent_harness/