Open-Source LLMs vs. ChatGPT
First page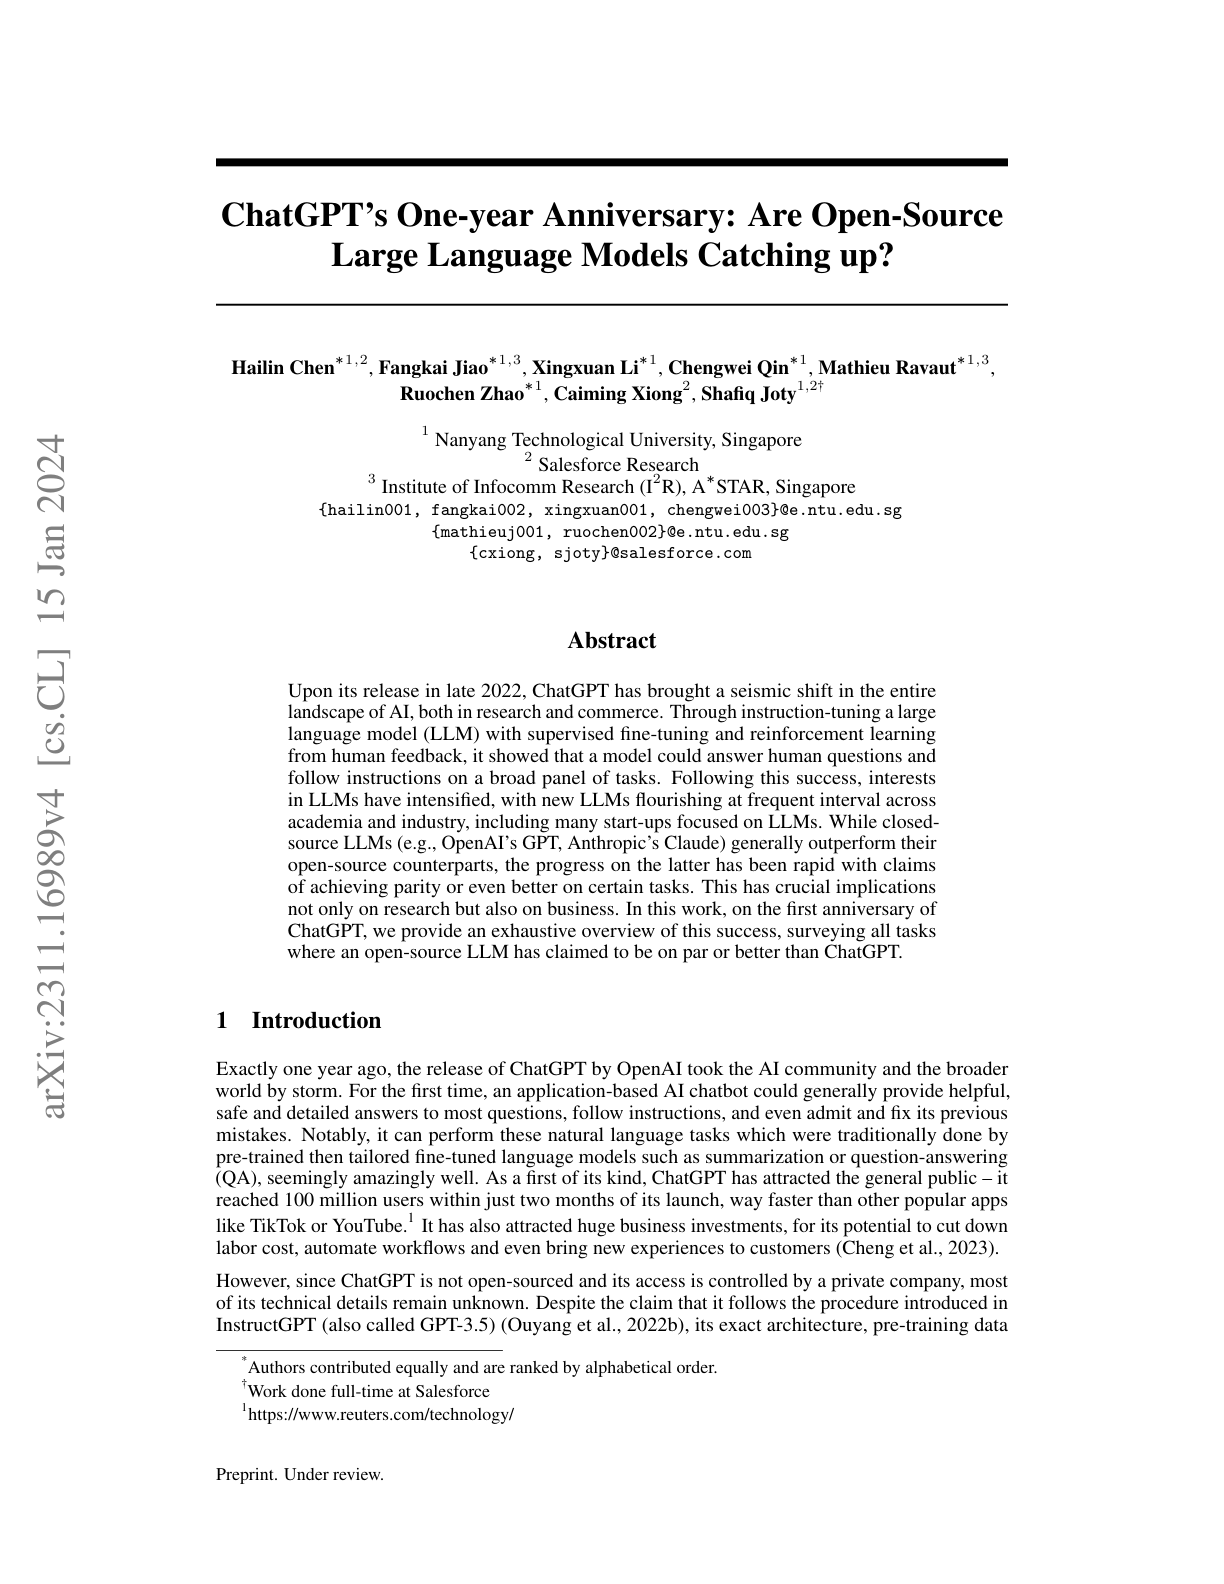
Paper summary
A survey cataloguing tasks where open-source LLMs claim to be on par with or better than ChatGPT.
Ask this paper
01
Task-by-task audit: Organizes claims by task category (code, math, reasoning, summarization, etc.) with the specific open models and benchmarks backing each claim.
02
Gap measurement: Clarifies where open-source genuinely closes the gap vs. where "comparable" actually hides meaningful performance differences.
03
Critical lens: Calls out evaluation-methodology issues in specific open-source claims, including benchmark contamination, cherry-picked subsets, and inconsistent judge setups.
04
2023 snapshot: Captures where open-source LLMs stood at the end of 2023 - a useful reference point for tracking how the gap evolved through 2024.