OpenELM
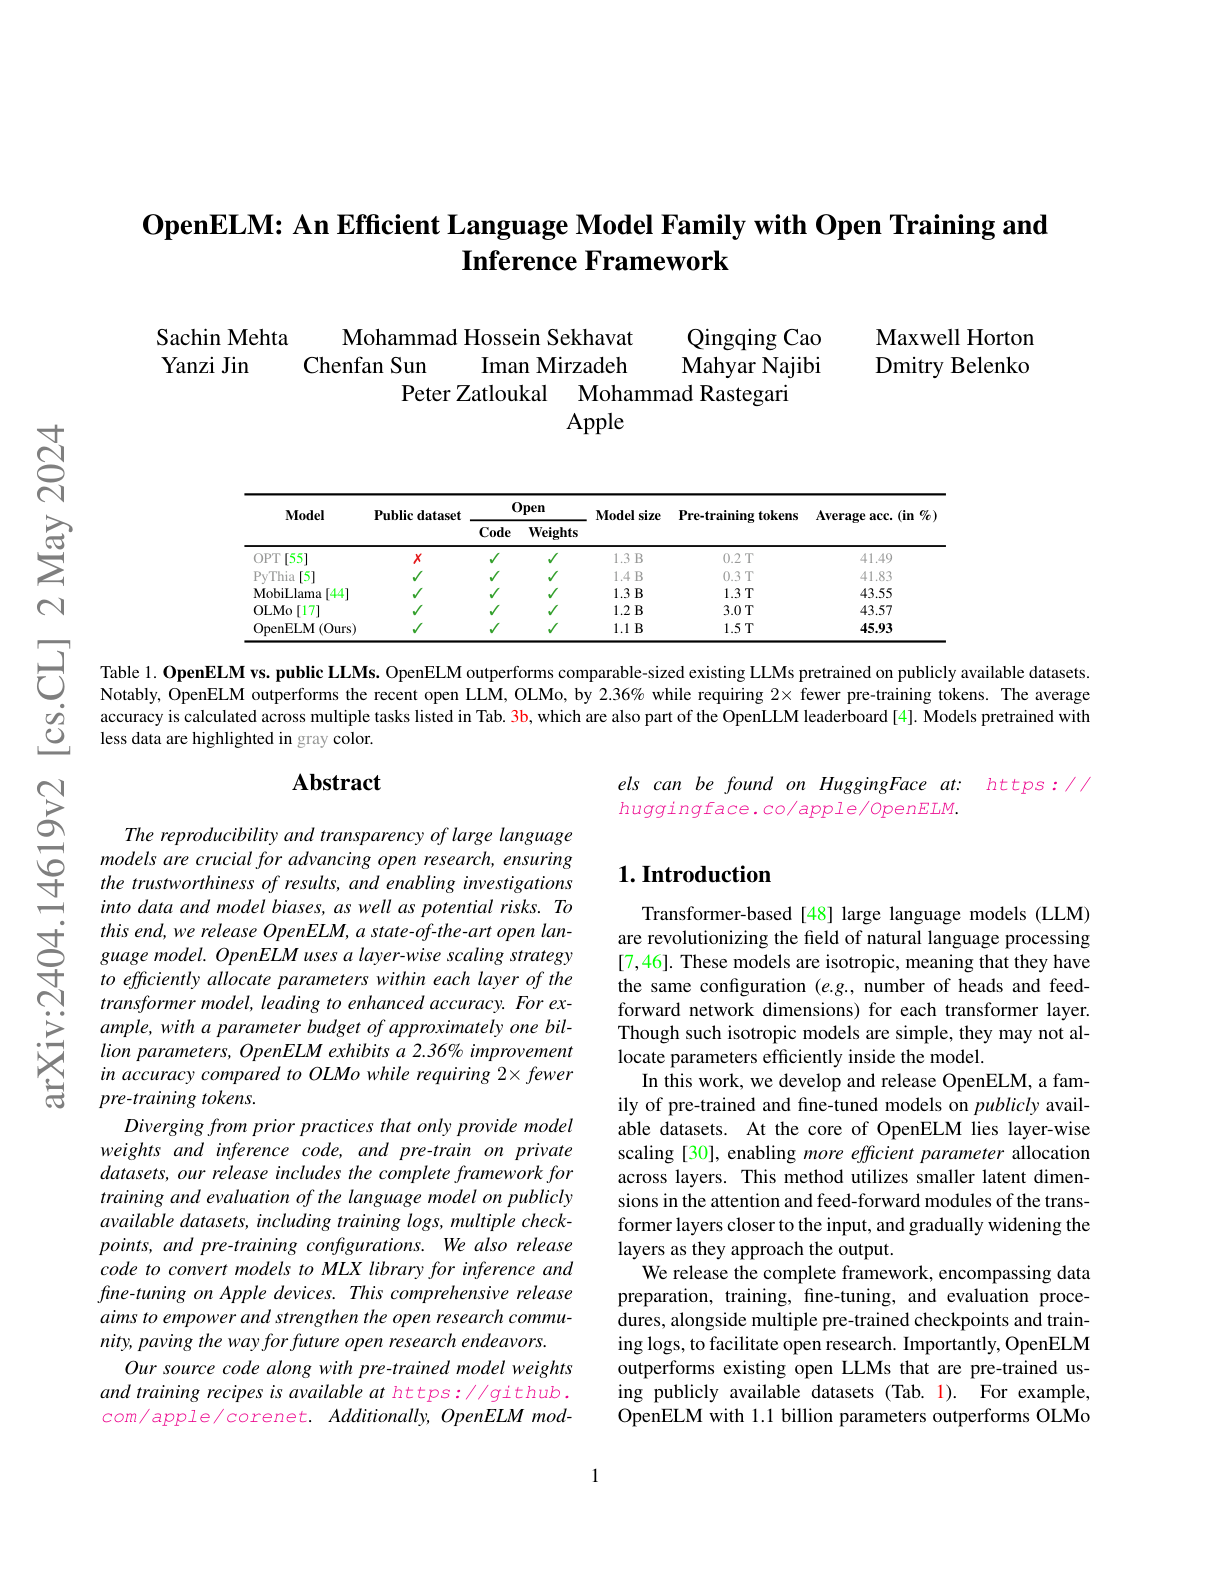
Apple's OpenELM is a fully-open small language model family (270M, 450M, 1.1B, 3B) that uses layer-wise parameter scaling instead of uniform layer widths. At ~1B parameters it improves on OLMo by 2.36% accuracy while using half the pre-training tokens.
Ask this paper
Layer-wise scaling: Rather than allocating parameters uniformly across transformer layers, OpenELM adjusts the width of each layer to place capacity where it matters most for downstream performance.
Efficient training: The ~1B variant achieves 2.36% higher accuracy than OLMo while requiring 2x fewer pre-training tokens, showing that architectural choices can match or beat raw data scale for small models.
Complete open release: Apple ships not just weights but training logs, intermediate checkpoints, pre-training configs, and MLX inference code - a far more complete release than most commercial labs offer.
Reproducibility focus: The release explicitly targets open research, giving the community the artifacts needed to re-trace and audit every step of the training pipeline.