Qwen-VL
First page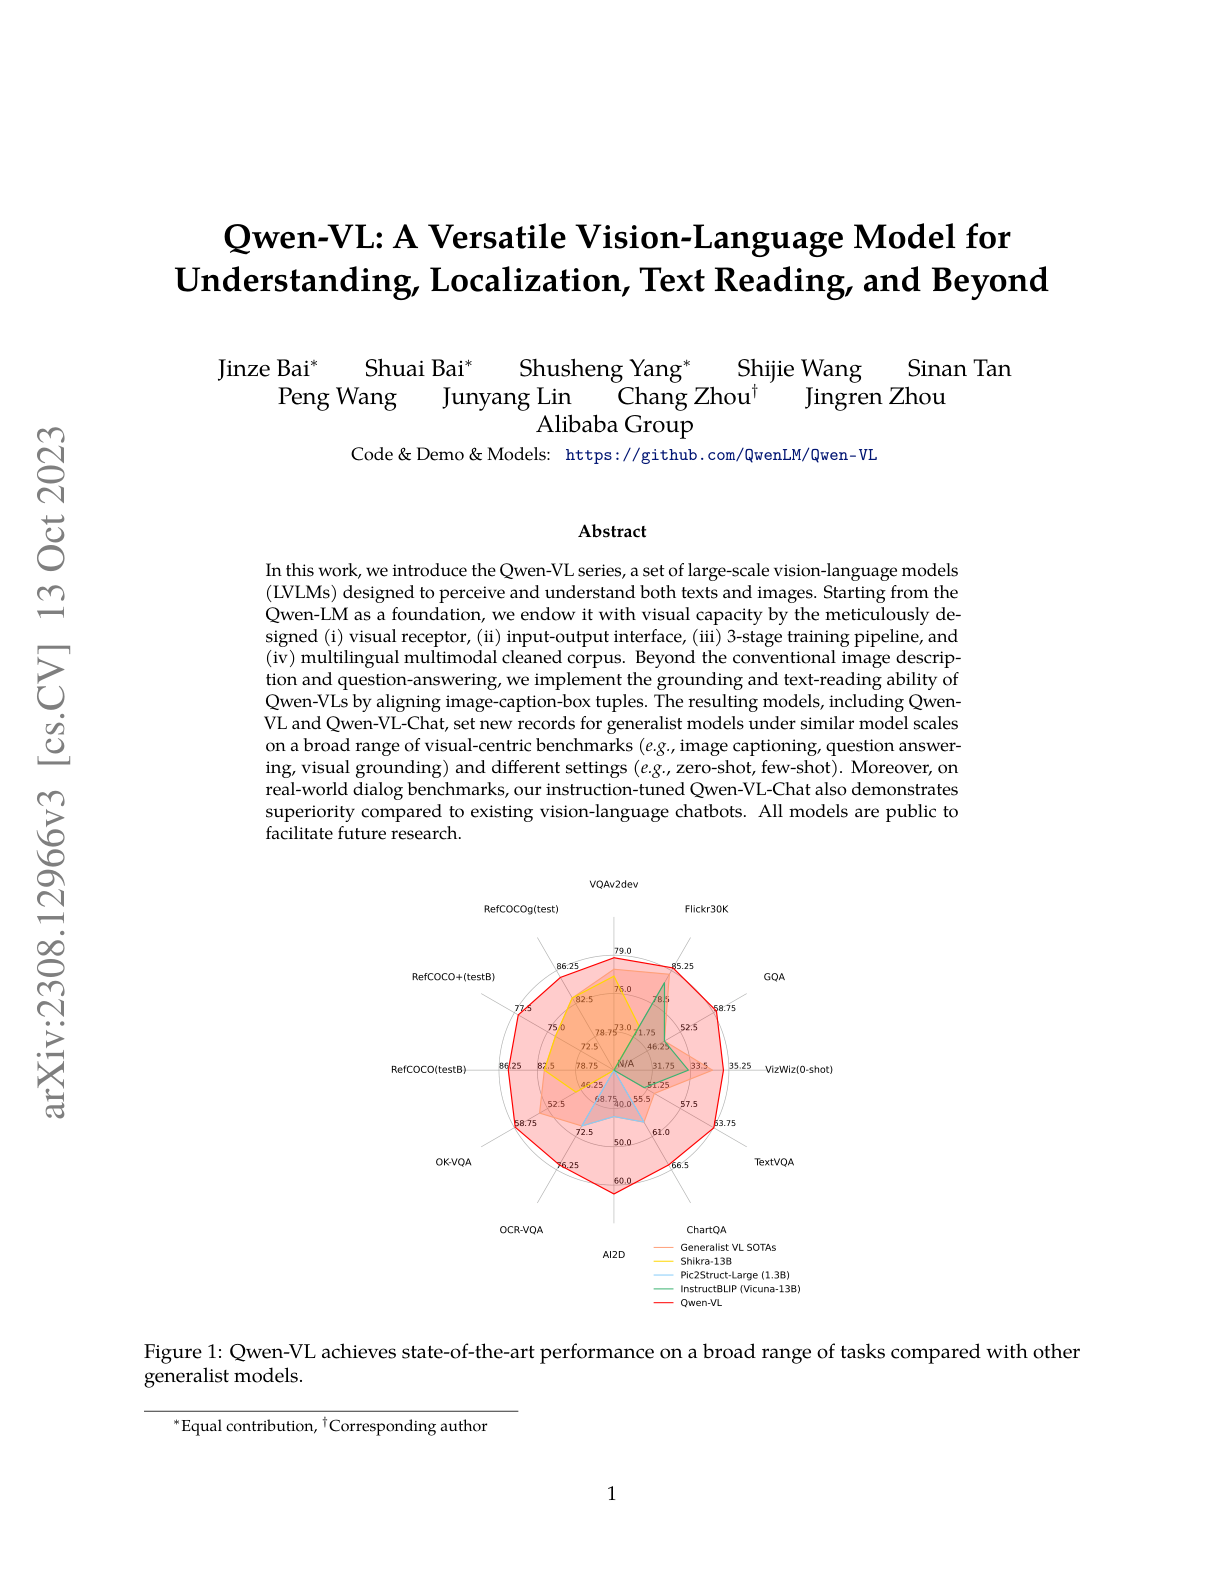
Paper summary
Alibaba's Qwen-VL is a large-scale vision-language model family with strong performance across captioning, VQA, and visual localization.
Ask this paper
01
Broad capability: Handles image captioning, visual QA, visual localization (grounding), and flexible multi-turn visual interaction.
02
Multilingual VL: Strong in both Chinese and English for visual tasks, filling a multilingual gap in VLMs predominantly English at the time.
03
Visual grounding: Supports bounding-box output for visual grounding, a capability not universally present in early VLMs.
04
Open release: Released as open weights, providing a strong open VLM baseline and kicking off the Qwen-VL family that has continued through 2024.