Retentive Network (RetNet)
First page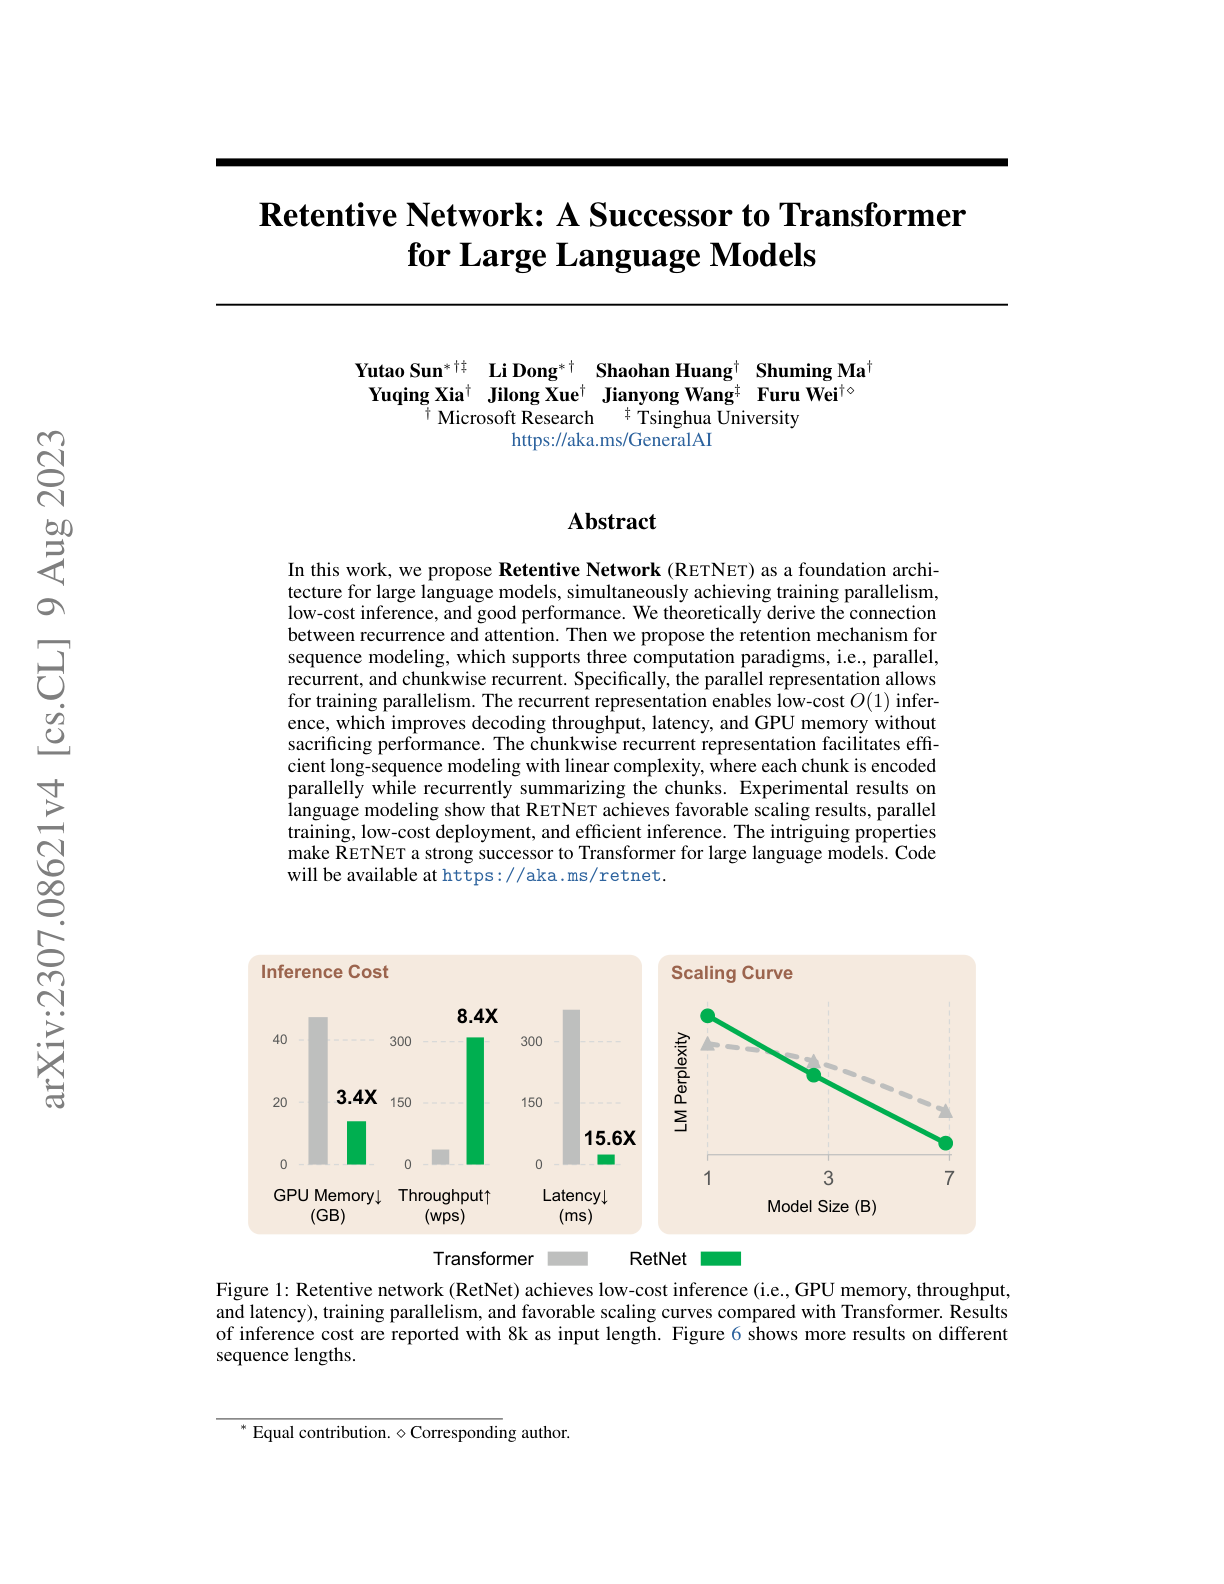
Paper summary
Microsoft's proposed foundation architecture aiming to replace Transformer attention for LLMs.
Ask this paper
01
Three-mode formulation: Supports parallel training, recurrent inference, and chunkwise recurrent representation - combining Transformer-style training with RNN-style inference.
02
O(1) inference cost: Achieves constant-memory inference per step via the recurrent form, dramatically cheaper than attention's O(n) per-token cost.
03
Retention mechanism: Replaces softmax attention with an exponentially-decaying retention kernel that supports both parallel and recurrent computation.
04
Post-Transformer contender: Positioned alongside Mamba, RWKV, and Hyena as one of the credible attempts to dethrone attention - though attention remained dominant through 2024.