rStar
First page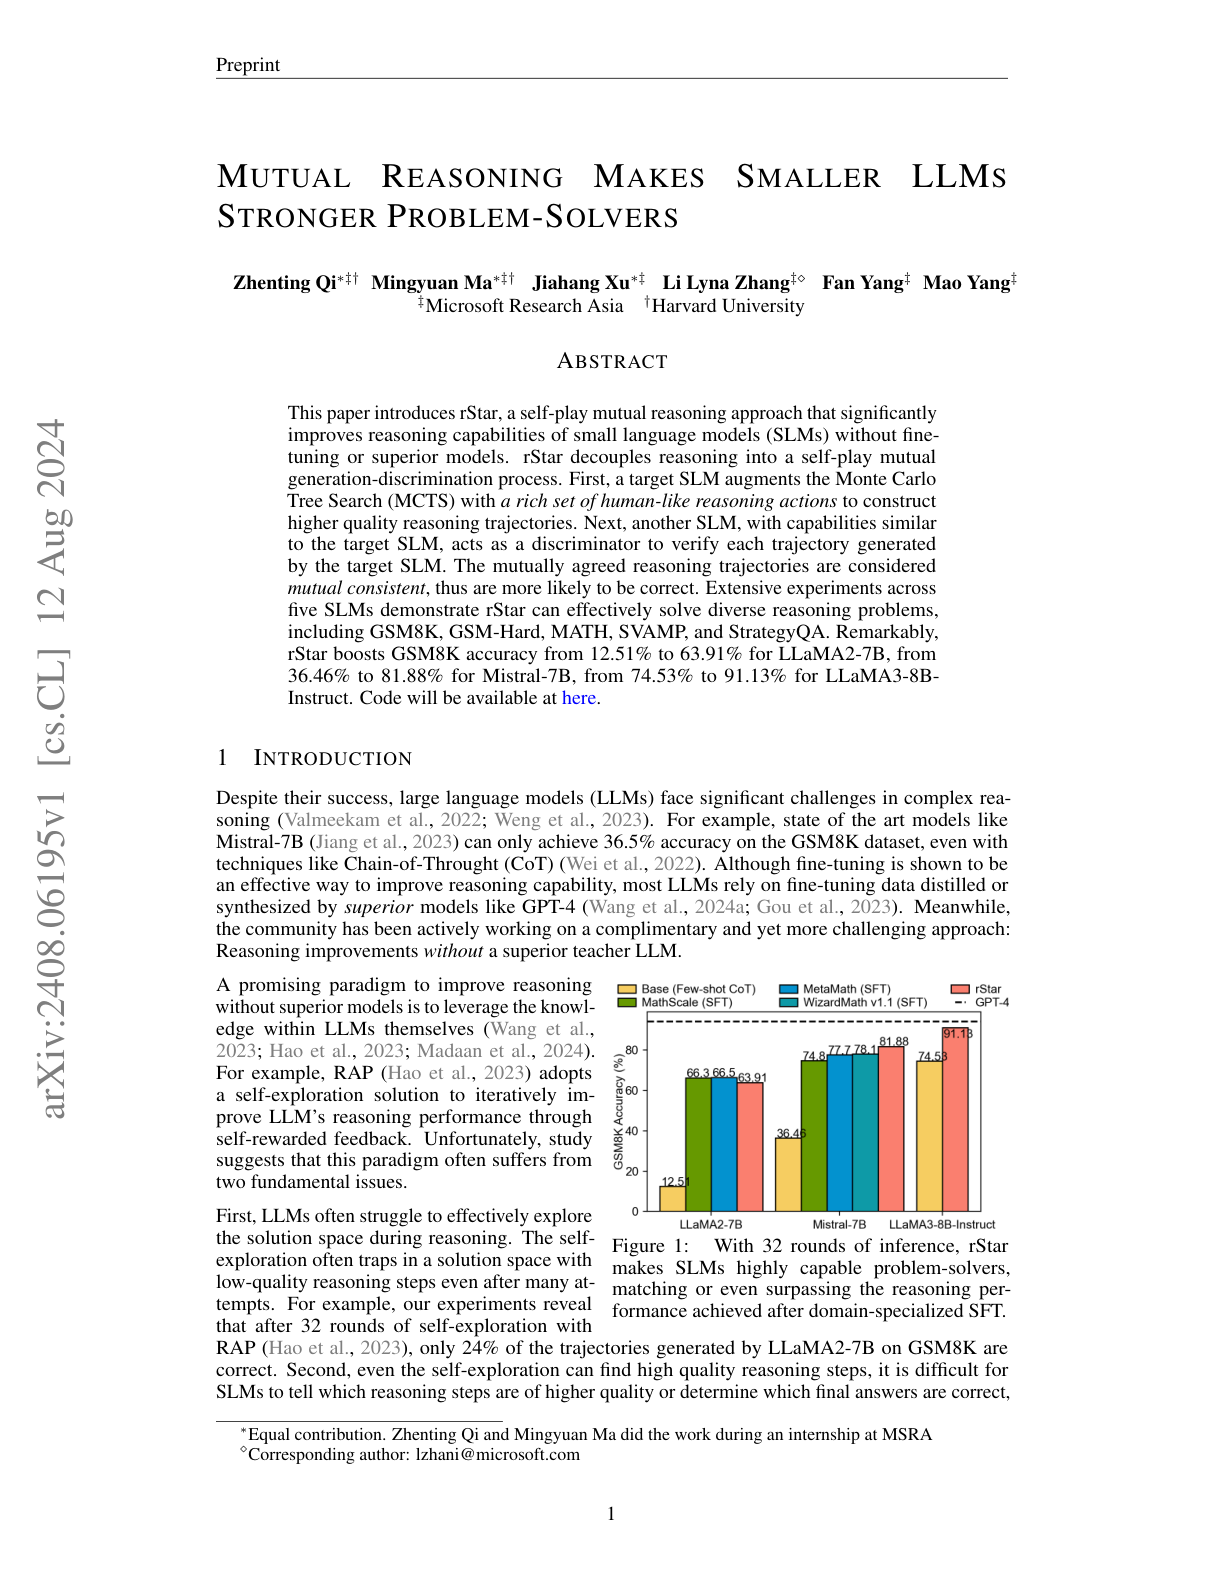
Paper summary
introduces self-play mutual reasoning to improve the reasoning capabilities of small language models without fine-tuning or superior models; MCTS is augmented with human-like reasoning actions, obtained from SLMs, to build richer reasoning trajectories; a separate SLM provides unsupervised feedback on the trajectories and the target SLM selects the final reasoning trajectory as the answer; rStar boosts GSM8K accuracy from 12.51% to 63.91% for LLaMA2-7B and consistently improves the accuracy of other SLMs.