rStar-Math
First page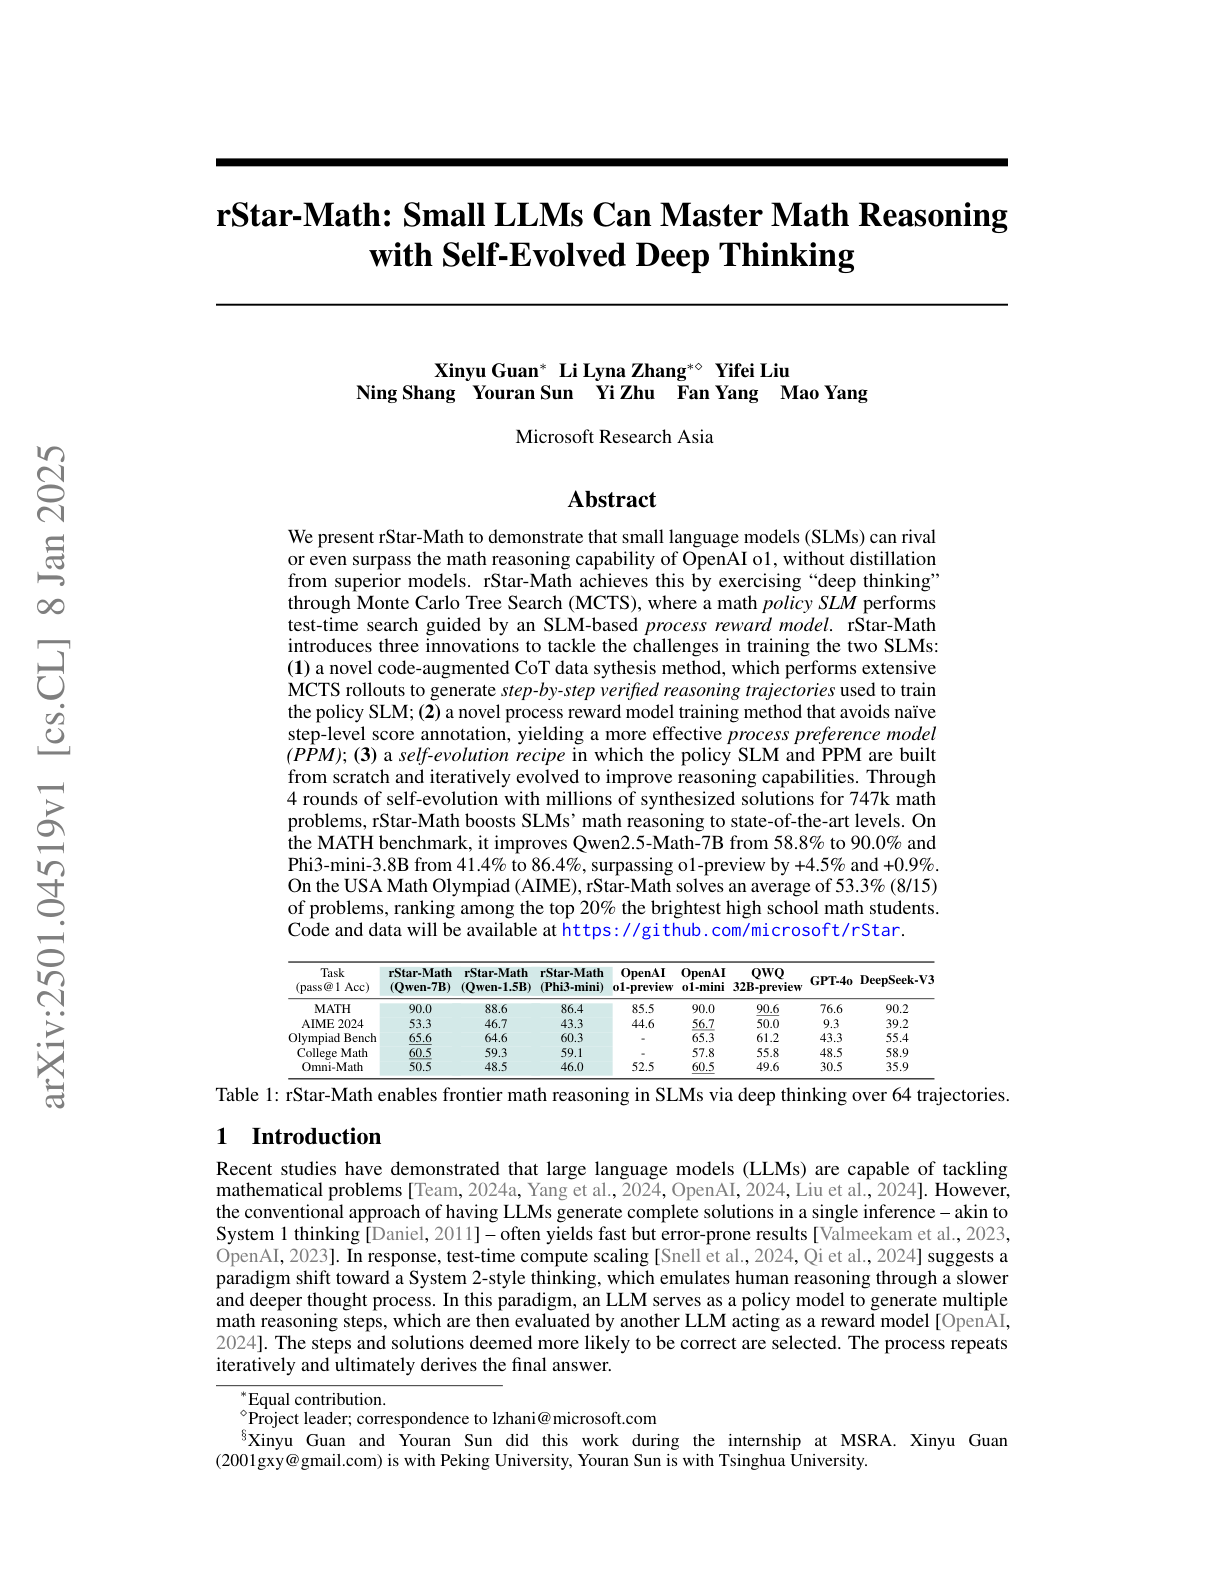
Paper summary
a new approach proposes three core components to enhance math reasoning: 1) a code-augmented CoT data synthesis method involving MCTS to generate step-by-step verified reasoning trajectories which are used to train the policy SLM, 2) an SLM-based process reward model that reliably predicts a reward label for each math reasoning step, and 3) a self-evolution recipe where the policy SLM and PPM are iteratively evolved to improve math reasoning; on the MATH benchmark, rStar-Math improves Qwen2.5-Math-7B from 58.8% to 90.0% and Phi3-mini-3.8B from 41.4% to 86.4%, surpassing o1-preview by +4.5% and +0.9%.