rStar2-Agent
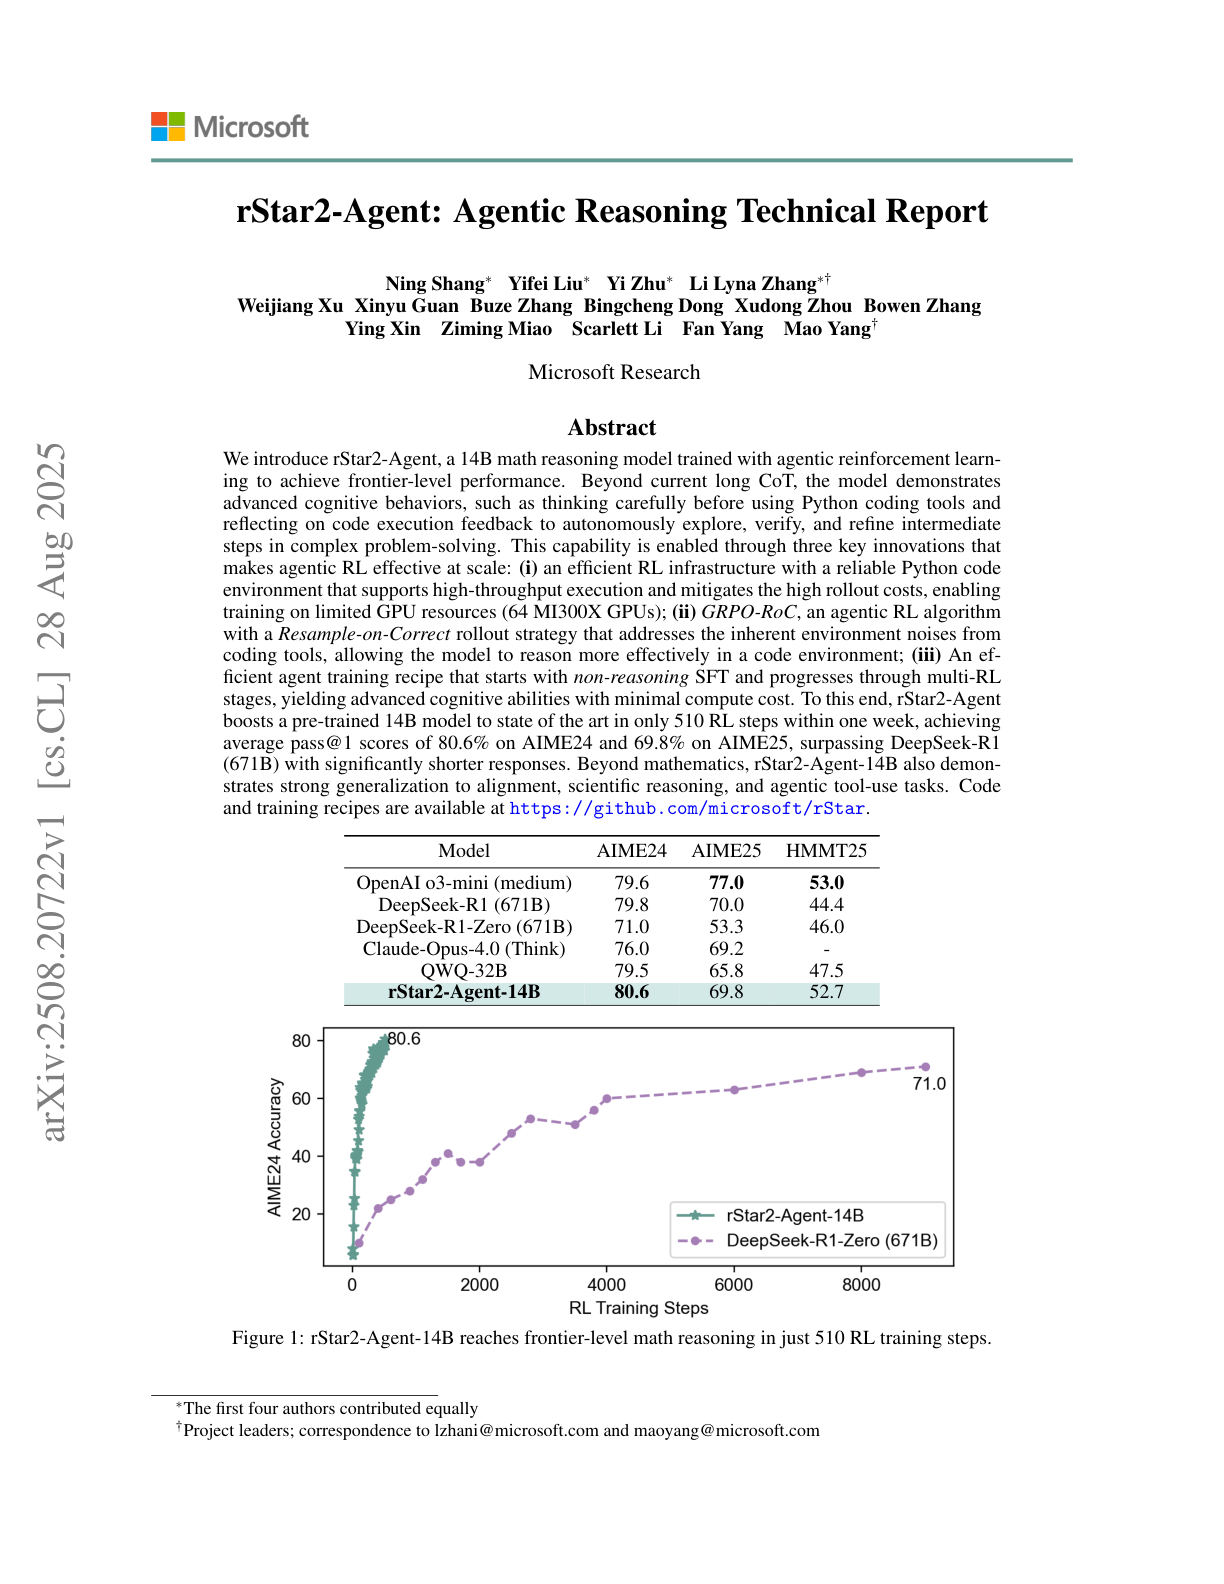
rStar2-Agent is a 14B math-reasoning model trained with agentic RL that learns to think smarter by using a Python tool environment, not just longer CoT. It introduces GRPO-RoC, a rollout strategy that filters noisy successful traces, plus infrastructure for massive, low-latency tool execution. In one week and 510 RL steps on 64 MI300X GPUs, the model reaches frontier-level AIME while producing shorter solutions and showing transfer beyond math.
Ask this paper
Method in one line: GRPO-RoC oversamples rollouts then keeps only the cleanest correct ones while preserving diverse failures, reducing tool-call errors and formatting issues during training.
Infrastructure: A dedicated, isolated code service reliably handles up to ~45K concurrent tool calls per training step with ~0.3 s end-to-end latency, and a load-balanced scheduler allocates rollouts by available KV cache to cut GPU idle time.
Training recipe: Start with non-reasoning SFT to teach tool use and formatting, then three RL stages that scale max output length 8K → 12K → 12K, and finally focus on harder problems; RL data curated to 42K math items with integer answers.
Results: Pass@1 AIME24 80.6, AIME25 69.8, HMMT25 52.7, exceeding or matching o3-mini (medium) and DeepSeek-R1 despite far smaller size; responses are shorter on AIME24/25 than Qwen3-14B and QWQ-32B.
Generalization and behaviors: Improves GPQA-Diamond to 60.9 and performs well on tool-use and alignment benchmarks; entropy analysis shows preserved forking tokens and new reflection tokens triggered by tool feedback, enabling verification and correction.