s$^3$: Simple Scaling of Swarms via Cooperative Multi-agent RL
Kunal Jha, Gonçalo Faria, Shuyue Stella Li and Scott Geng (University of Washington, Allen Institute for AI), with Faeze Brahman, Noah A. Smith, Yulia Tsvetkov, Max Kleiman-Weiner and Natasha Jaques, introduce s3, a multi-agent RL method in which LLM agents learn when to work alone, when to share findings and when to read teammates' messages.
Ask this paper
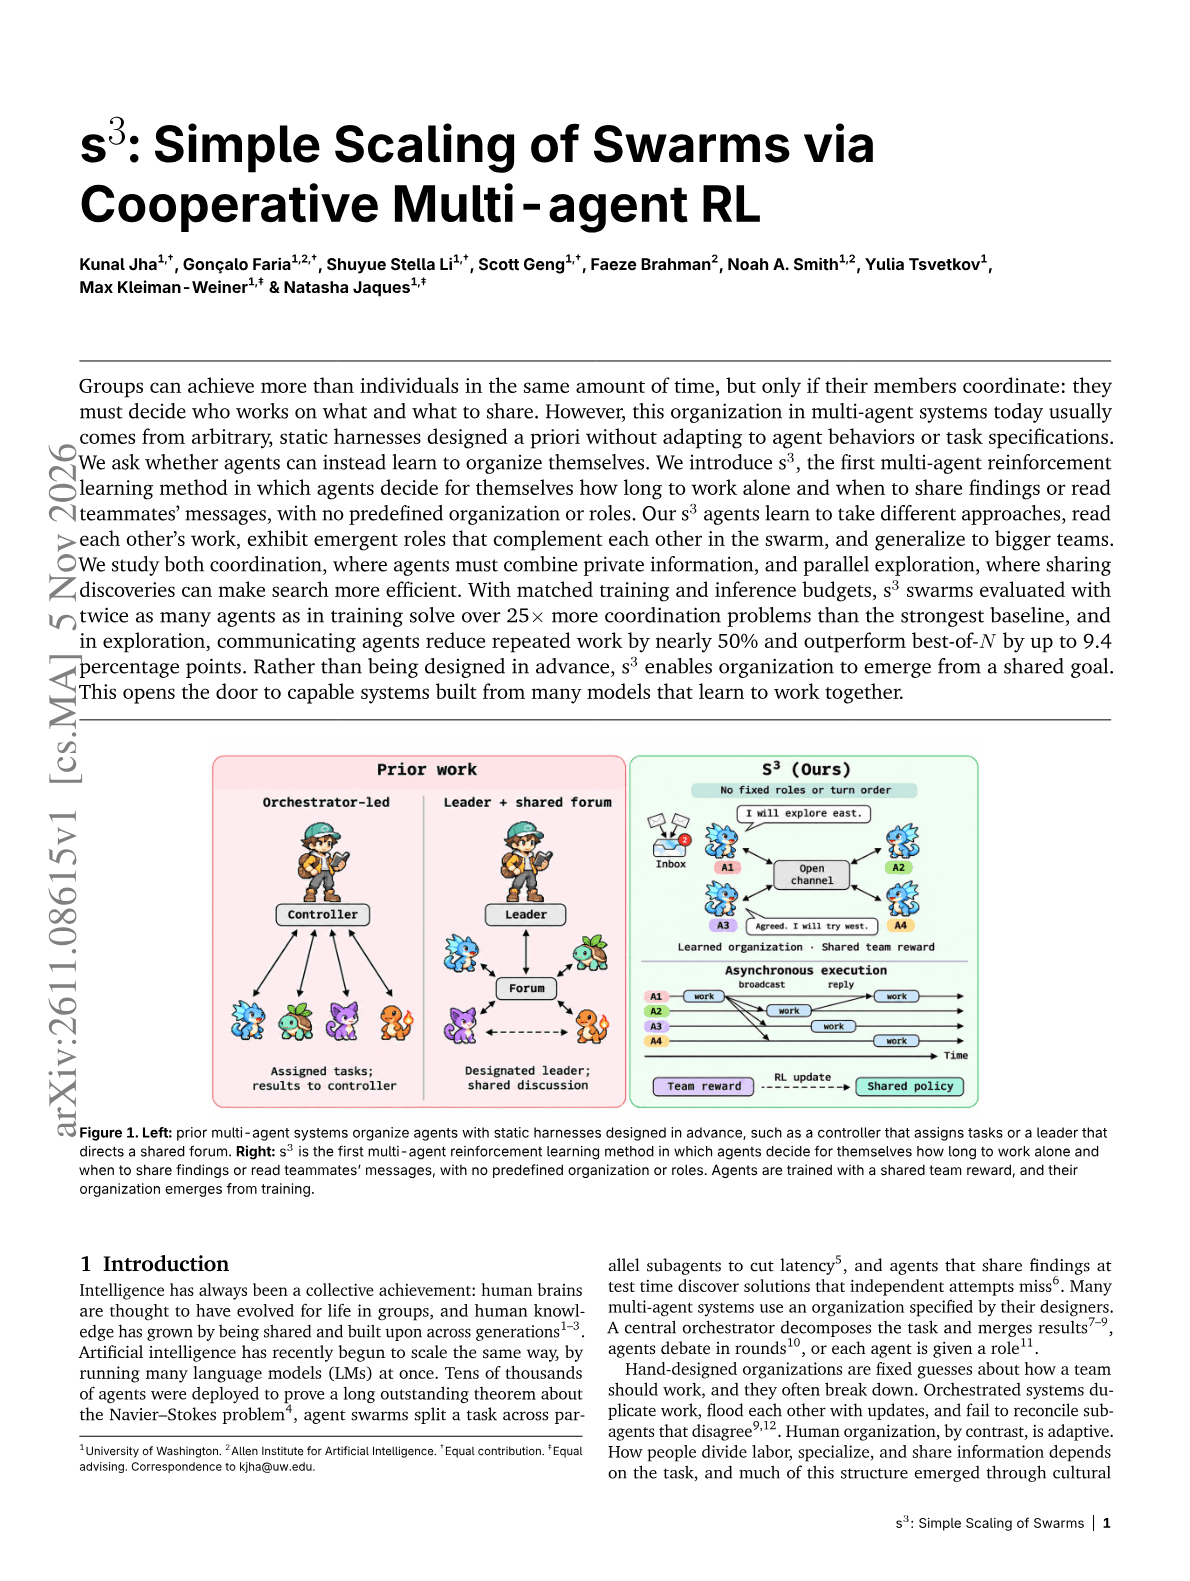
Problem. Organization in multi-agent systems usually comes from fixed harnesses designed in advance that do not adapt to the agents or the task.
Method. s3 trains agents with cooperative RL and no predefined roles or communication schedule. Each agent decides how long to work alone and when to share or read.
Coordination results. With matched training and inference budgets, swarms evaluated with twice as many agents as in training solve over 25x more coordination problems than the strongest baseline.
Exploration results. Communicating agents reduce repeated work by nearly 50% and outperform best-of-N by up to 9.4 percentage points.
Emergent roles. Agents take different approaches, read each other's work, develop complementary roles and generalize to larger teams.
Abstract
Groups can achieve more than individuals in the same amount of time, but only if their members coordinate: they must decide who works on what and what to share. However, this organization in multi-agent systems today usually comes from arbitrary, static harnesses designed a priori without adapting to agent behaviors or task specifications. We ask whether agents can instead learn to organize themselves. We introduce s$^3$, the first multi-agent reinforcement learning method in which agents decide for themselves how long to work alone and when to share findings or read teammates' messages, with no predefined organization or roles. Our s$^3$ agents learn to take different approaches, read each other's work, exhibit emergent roles that complement each other in the swarm, and generalize to bigger teams. We study both coordination, where agents must combine private information, and parallel exploration, where sharing discoveries can make search more efficient. With matched training and inference budgets, s$^3$, swarms evaluated with twice as many agents as in training solve over 25$\times$ more coordination problems than the strongest baseline, and in exploration, communicating agents reduce repeated work by nearly 50% and outperform best-of-N by up to 9.4 percentage points. Rather than being designed in advance, s$^3$ enables organization to emerge from a shared goal. This opens the door to capable systems built from many models that learn to work together.