Scaling MLPs: A Tale of Inductive Bias
First page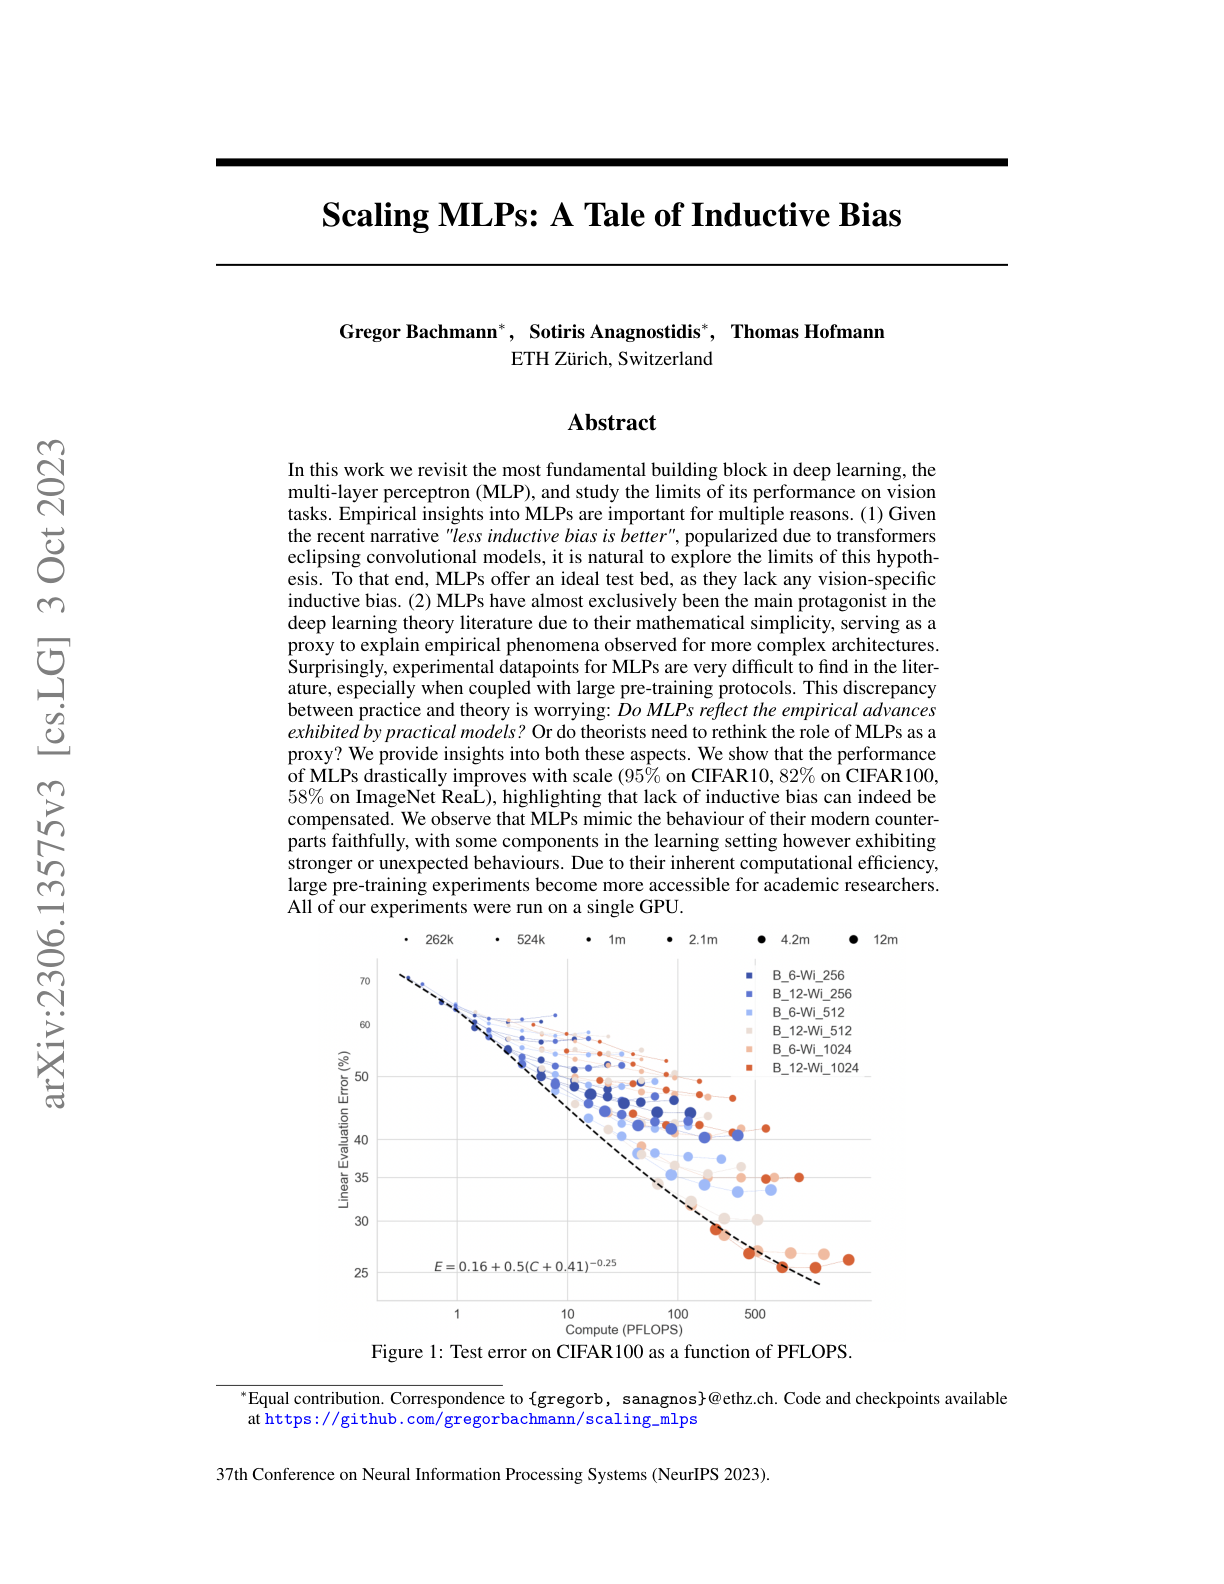
Paper summary
Shows MLPs scale with compute despite their lack of inductive bias.
Ask this paper
01
Pure-MLP scaling: Demonstrates that large pure-MLP models trained on enough data can reach surprisingly strong performance on image classification.
02
Inductive bias is compensable: Challenges the dogma that CNN/Transformer inductive biases are necessary - scale and data can substitute.
03
Bitter lesson evidence: Adds to the "bitter lesson" empirical evidence that general methods leveraging computation outperform those leveraging human-designed priors.
04
Architecture agnosticism: Part of the 2023 trend showing that many architectures (MLPs, State Space Models, RNNs, Transformers) converge at scale.