Scaling Multi-Agent Intelligence with Substrate-Centric Coordination
Zhenting Qi, Wen-tau Yih, Ansong Ni, Bhargavi Paranjape, Yilun Du and colleagues (FAIR at Meta, Harvard) present ScaleMAS, in which asynchronous agents coordinate only through a shared datastore of linked messages, and show it keeps improving up to 128 agents.
Ask this paper
Three scaling problems. In existing multi-agent systems, the reading load grows with group size, useful work is diluted by work of unknown quality, and the system breaks when agents fail.
Substrate. Agents publish messages that can cite earlier ones, search messages by content, and visit messages by address. The datastore is append-only.
Bounded reading. A search returns at most k messages, so each agent's reading stays bounded at any group size. Results are ranked by relevance and by citation count, which the authors find works as a quality signal.
Fault tolerance. Messages persist after their authors leave. A group of N agents with one failed agent performs comparably to N-1 healthy agents.
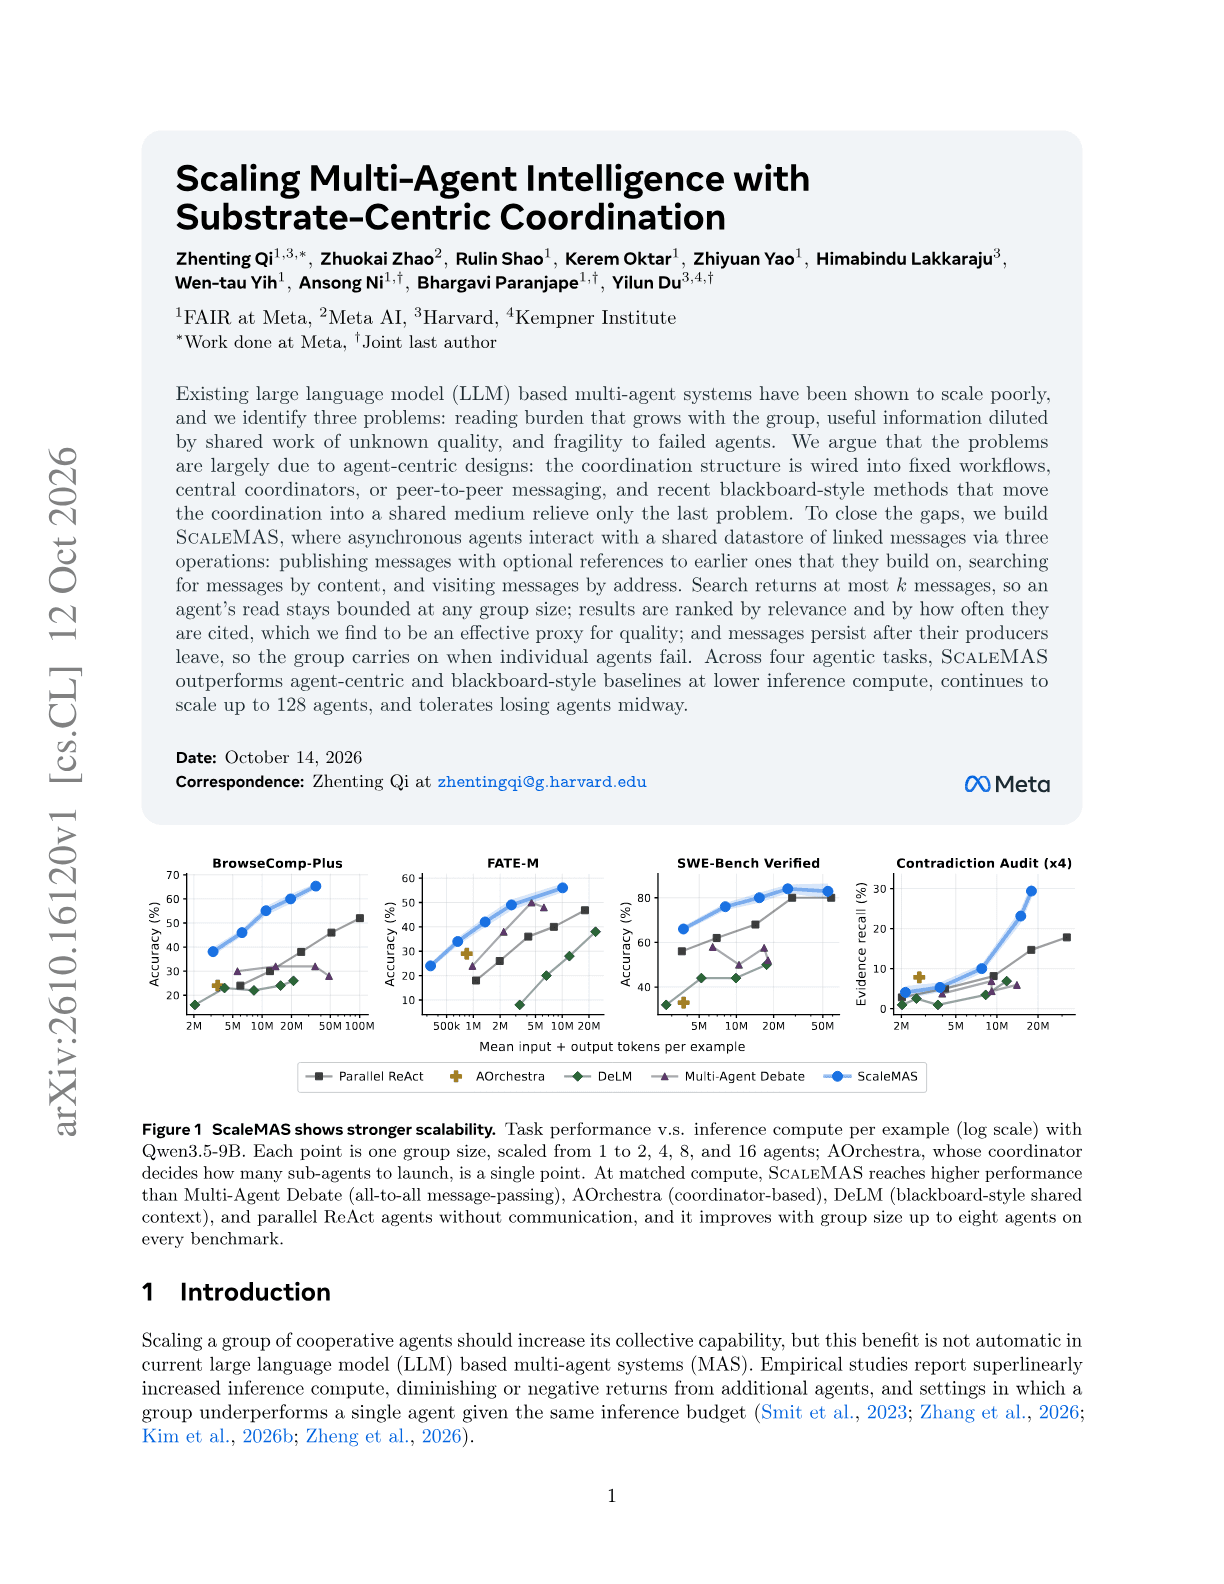
Results. Across four agentic tasks ScaleMAS beats agent-centric and blackboard-style baselines at lower inference compute and continues to scale to 128 agents.
Abstract
Existing large language model (LLM) based multi-agent systems have been shown to scale poorly, and we identify three problems: reading burden that grows with the group, useful information diluted by shared work of unknown quality, and fragility to failed agents. We argue that the problems are largely due to agent-centric designs: the coordination structure is wired into fixed workflows, central coordinators, or peer-to-peer messaging, and recent blackboard-style methods that move the coordination into a shared medium relieve only the last problem. To close the gaps, we build ScaleMAS, where asynchronous agents interact with a shared datastore of linked messages via three operations: publishing messages with optional references to earlier ones that they build on, searching for messages by content, and visiting messages by address. Search returns at most $k$ messages, so an agent's read stays bounded at any group size; results are ranked by relevance and by how often they are cited, which we find to be an effective proxy for quality; and messages persist after their producers leave, so the group carries on when individual agents fail. Across four agentic tasks, ScaleMAS outperforms agent-centric and blackboard-style baselines at lower inference compute, continues to scale up to 128 agents, and tolerates losing agents midway.