Scaling Synthetic Data Creation
First page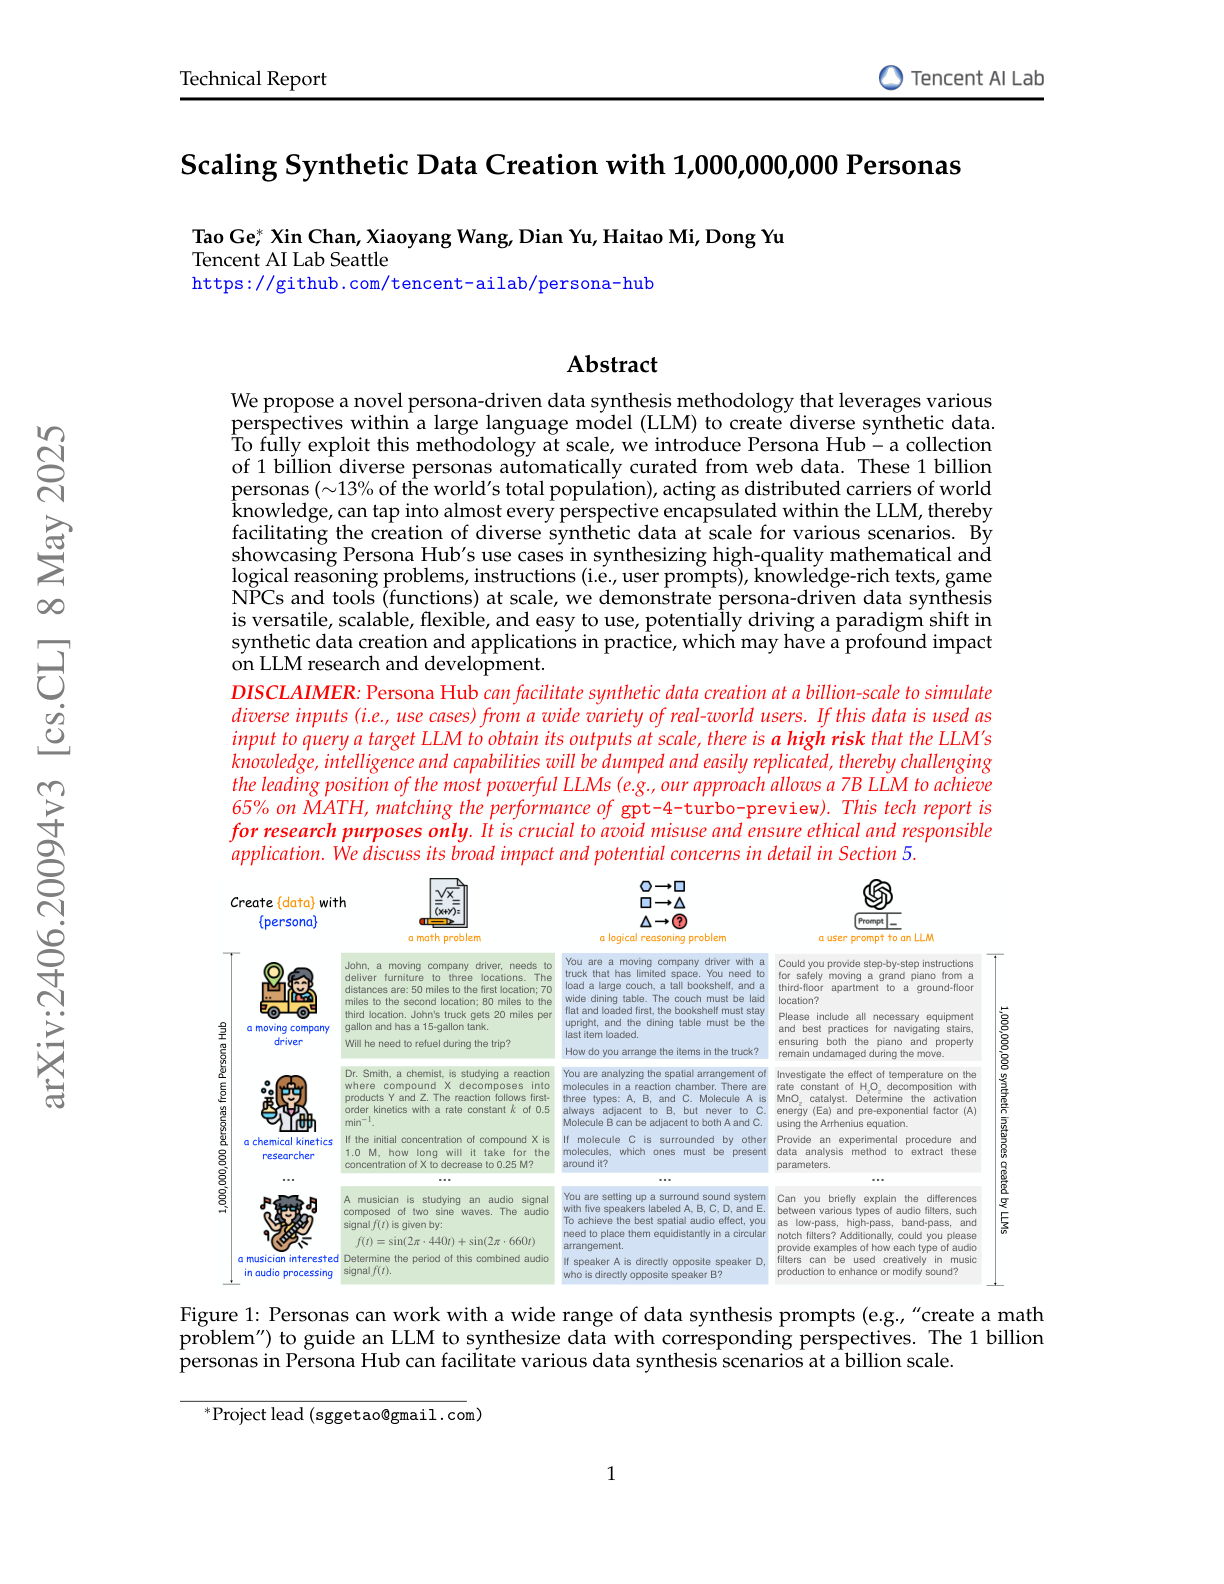
Paper summary
proposes 1 billion diverse personas to facilitate the creation of diverse synthetic data for different scenarios; uses a novel persona-driven data synthesis methodology to generate diverse and distinct data covering a wide range of perspectives; to measure the quality of the synthetic datasets, they performed an out-of-distribution evaluation on MATH. A fine-tuned model on their synthesized 1.07M math problems achieves 64.9% on MATH, matching the performance of gpt-4-turbo-preview at only a 7B scale.