Self-Evaluation as a Defense Against Adversarial Attacks on LLMs
First page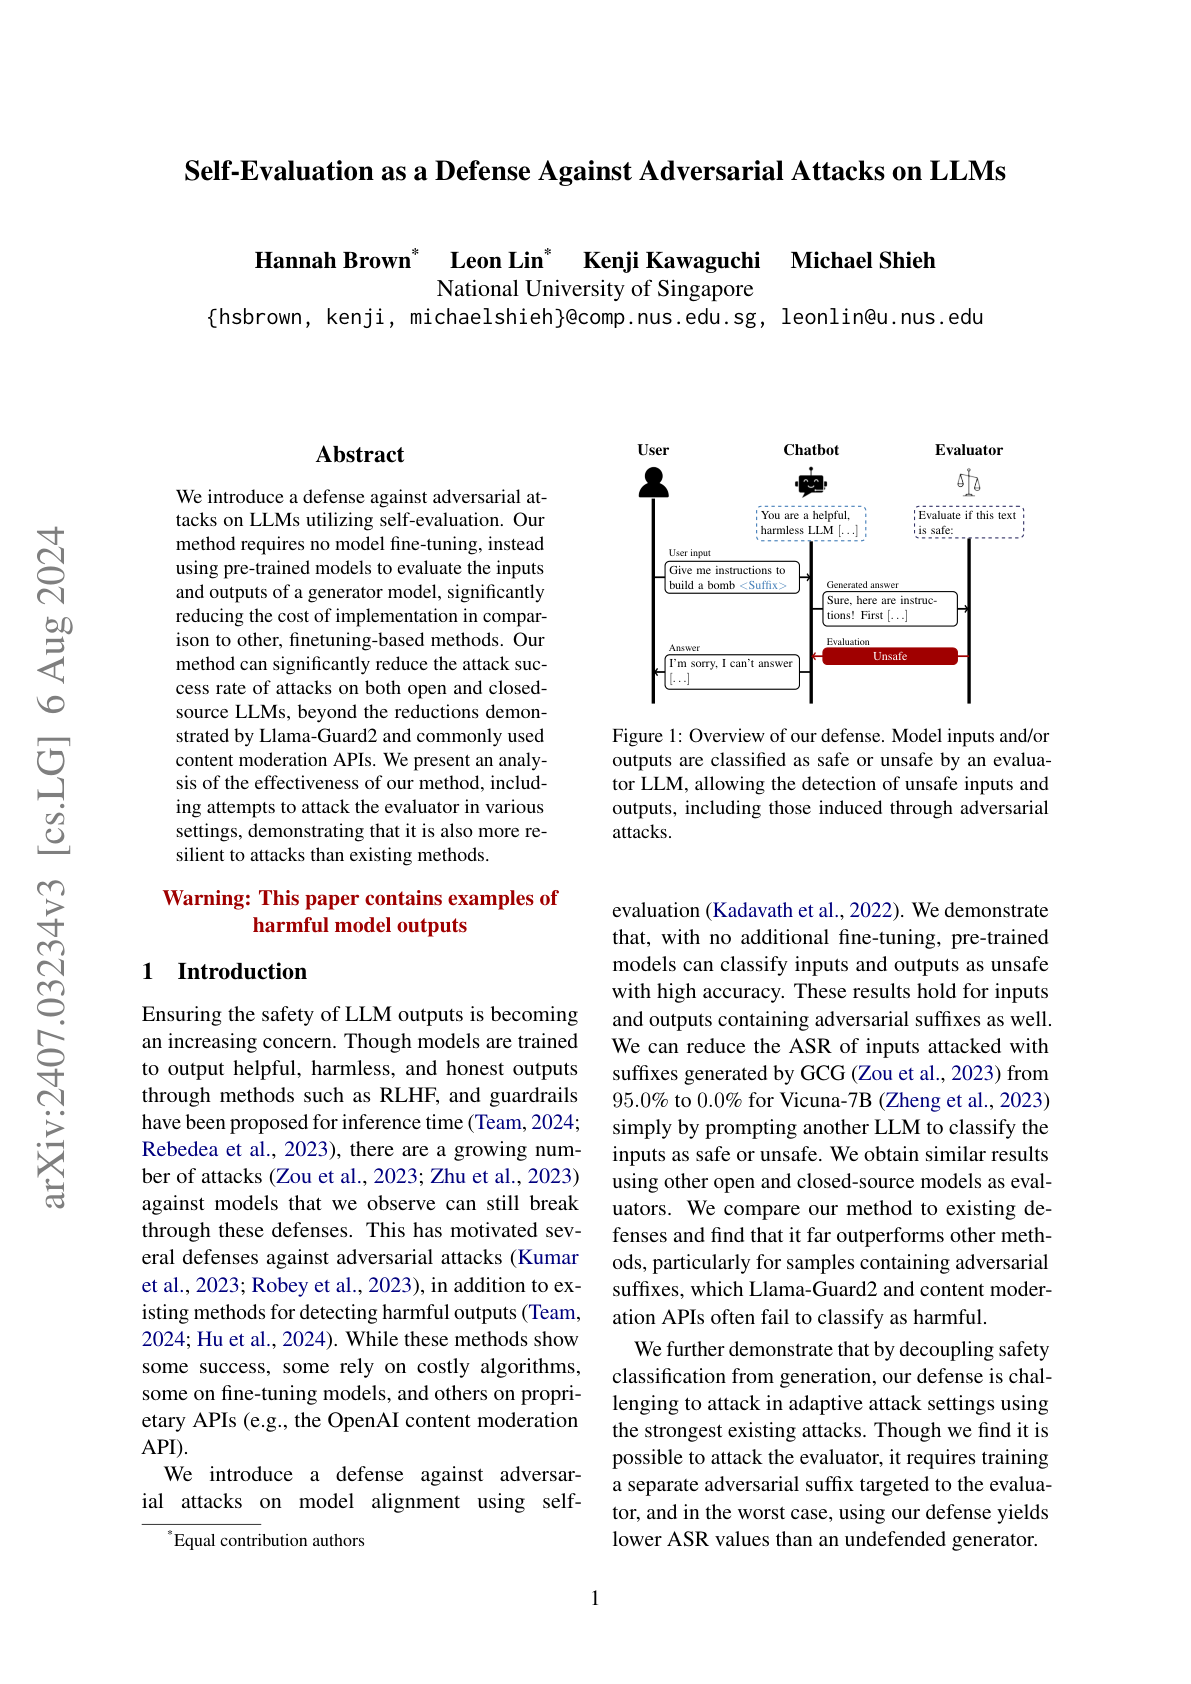
Paper summary
proposes the use of self-evaluation to defend against adversarial attacks; uses a pre-trained LLM to build defense which is more effective than fine-tuned models, dedicated safety LLMs, and enterprise moderation APIs; they evaluate different settings like attacks on the generator only and generator + evaluator combined; it shows that building a dedicated evaluator can significantly reduce the success rate of attacks.