WebRL
First page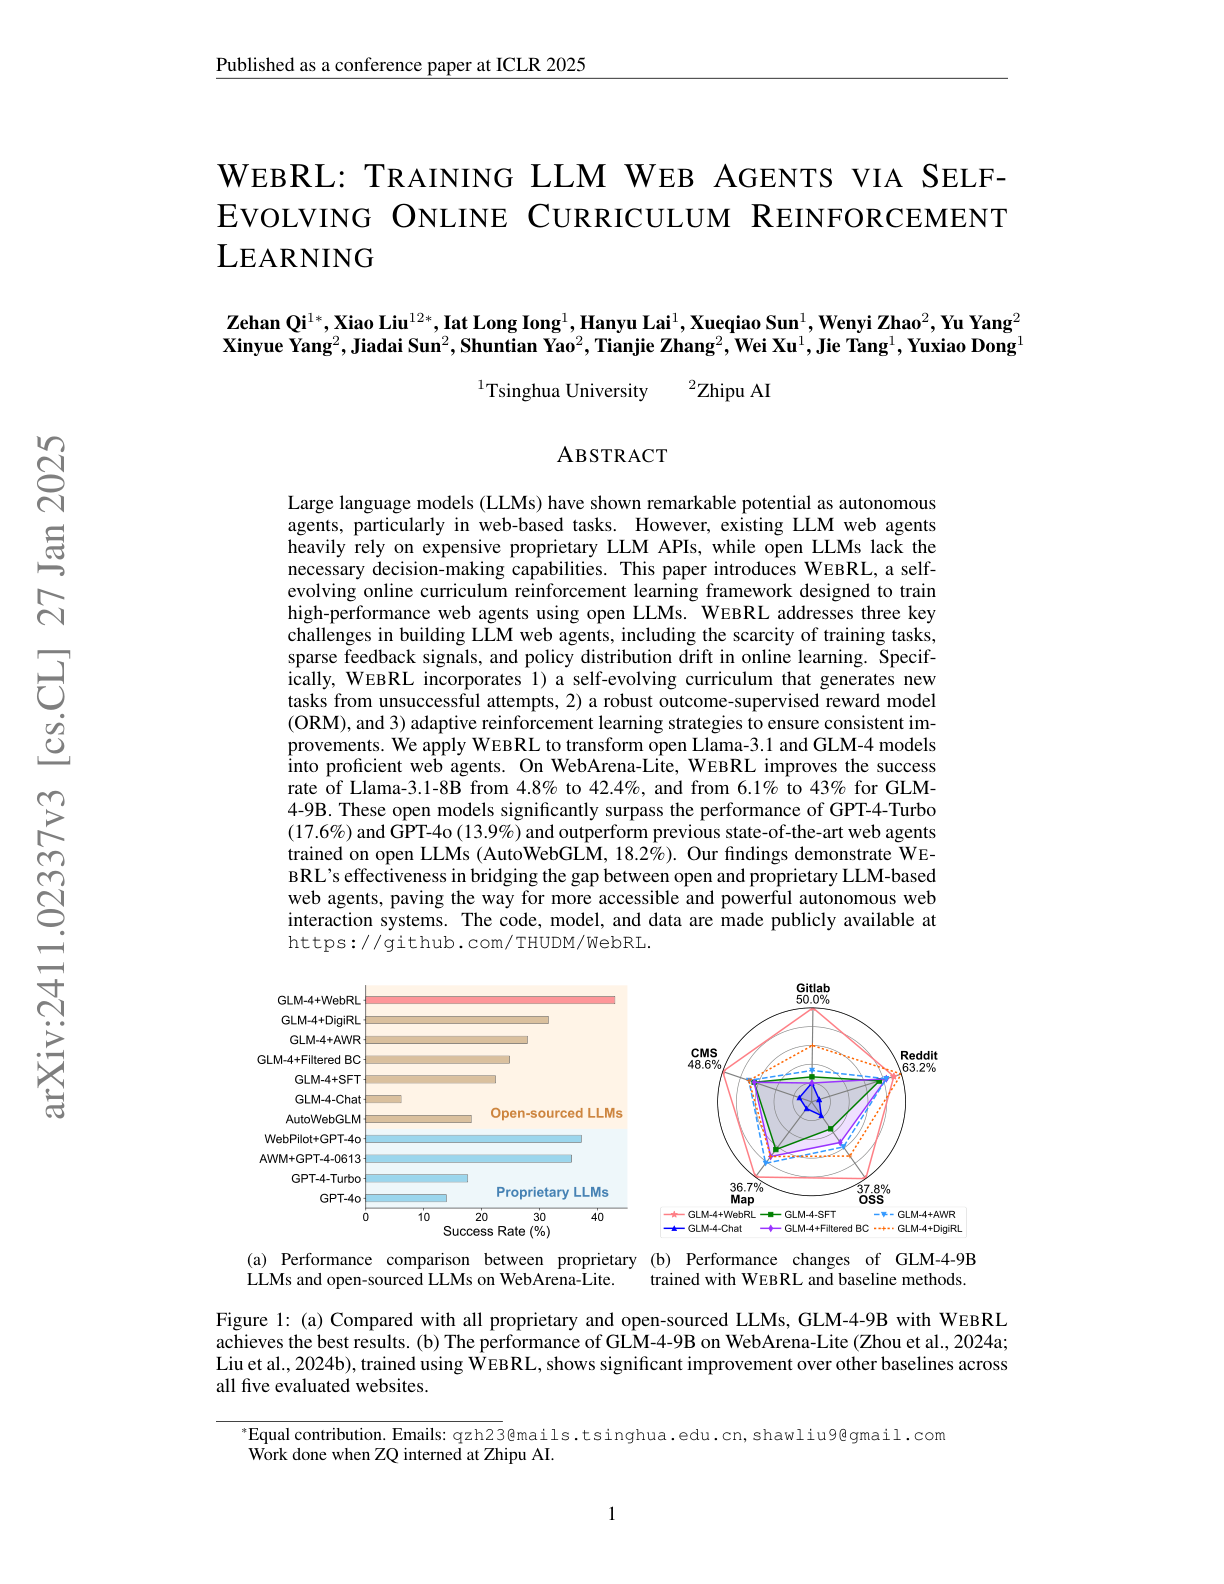
Paper summary
proposes a self-evolving online curriculum RL framework to bridge the gap between open and proprietary LLM-based web agents; it improves the success rate of Llama-3.1-8B from 4.8% to 42.4%, and from 6.1% to 43% for GLM4-9B; the open models significantly surpass the performance of GPT-4-Turbo (17.6%) and GPT-4o (13.9%); the self-evolving curriculum addresses the scarcity of web agent training tasks; this is underpinned by a robust outcome-supervised reward model to evaluate task success; an adaptive RL strategy helps to deal with distribution drift in online learning and ensures consistent improvements.