You Only Cache Once
First page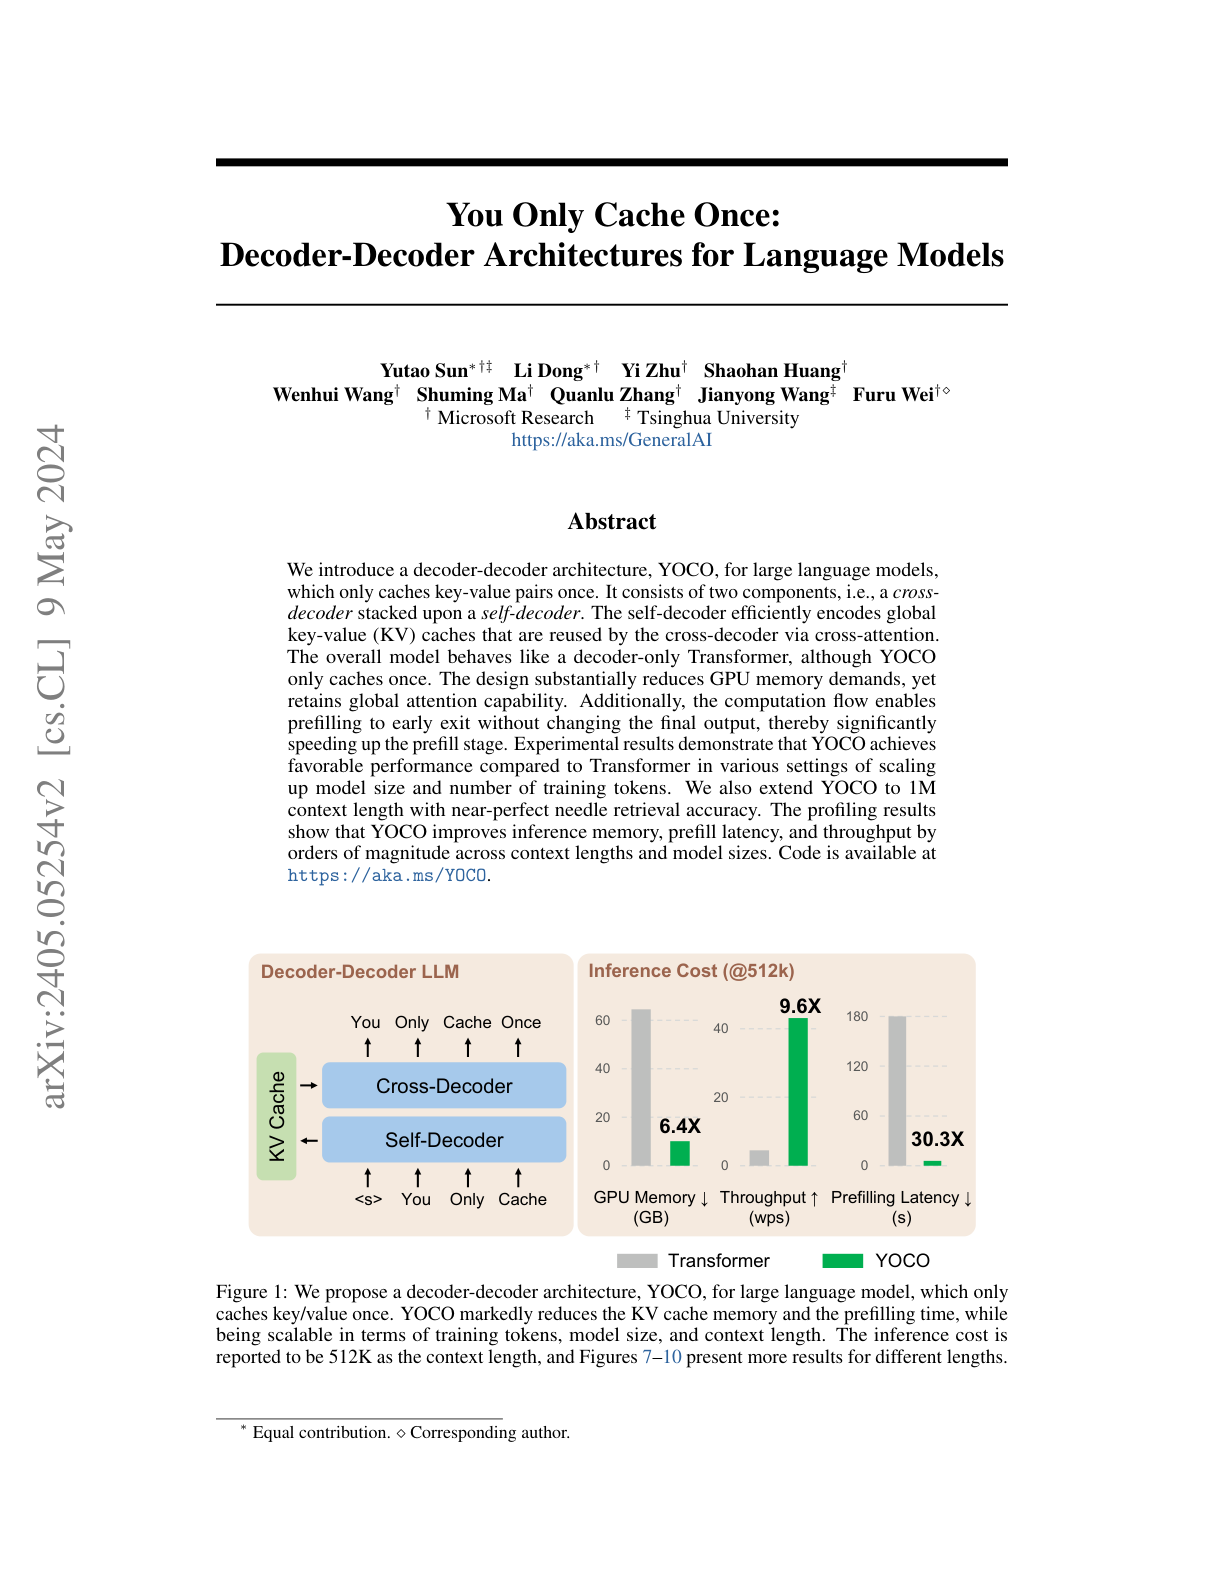
Paper summary
a decoder-decoder LLM architecture that only caches key-value pairs once; it involves a cross-decoder stacked upon a self-decoder which efficiently encodes global key-value caches and the cross-encoder reuses the cache via cross-attention; this leads to a significant reduction in GPU memory use without sacrificing capabilities; achieves comparable performance to Transformer in various settings of scaling up model size and number of training token.