Advances in Multimodal LLMs
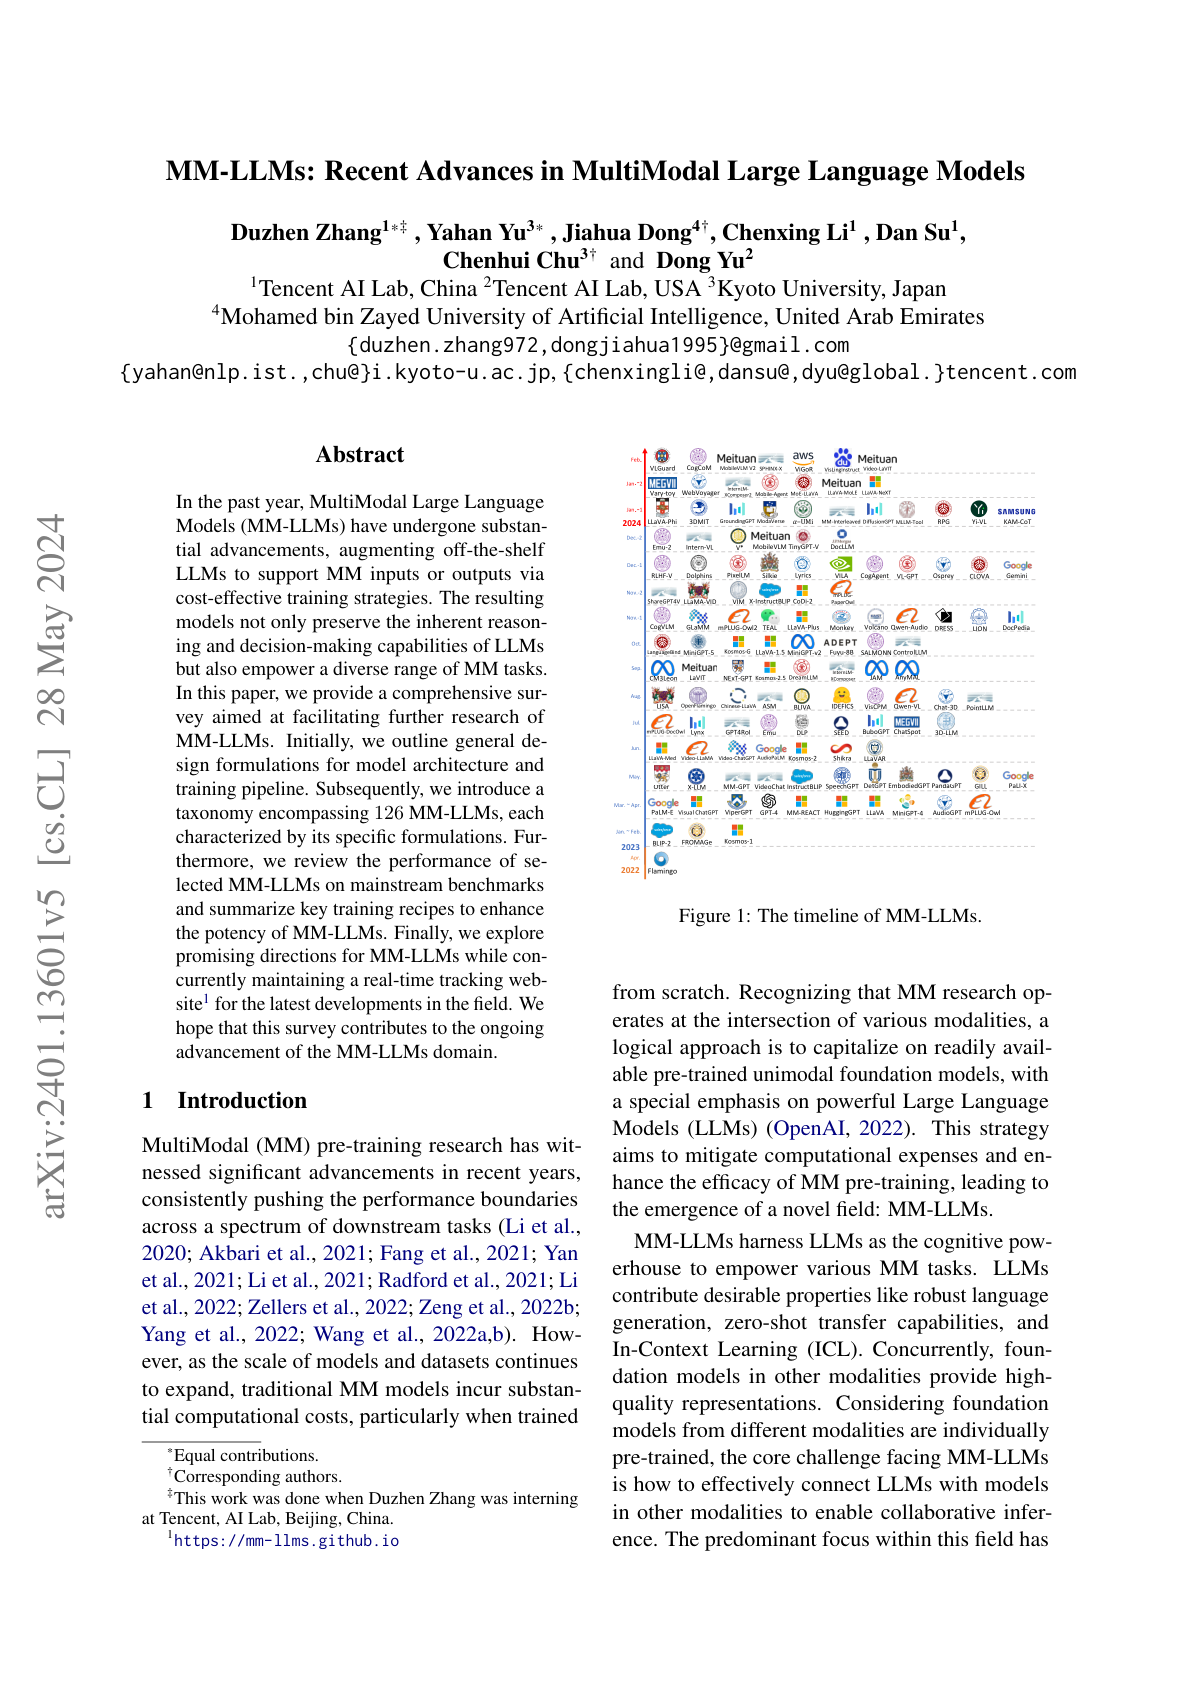
A comprehensive survey mapping design choices for architecture and training pipeline around multimodal large language models (MLLMs).
Ask this paper
Architecture taxonomy: Organizes MLLMs by modality encoders, LLM backbones, and cross-modal connectors (Q-Former, linear, cross-attention, etc.), clarifying which design axes matter most.
Training pipeline: Walks through modality alignment pretraining, visual instruction tuning, and RLHF-style preference optimization as the dominant recipe across recent MLLMs.
Applications and evaluation: Catalogs tasks (VQA, captioning, grounding, video, document understanding) alongside the benchmarks commonly used to evaluate them.
Open challenges: Identifies hallucination, long-video understanding, efficient training, and tool-augmented multimodality as the most pressing research directions.