MoE-LLaVA
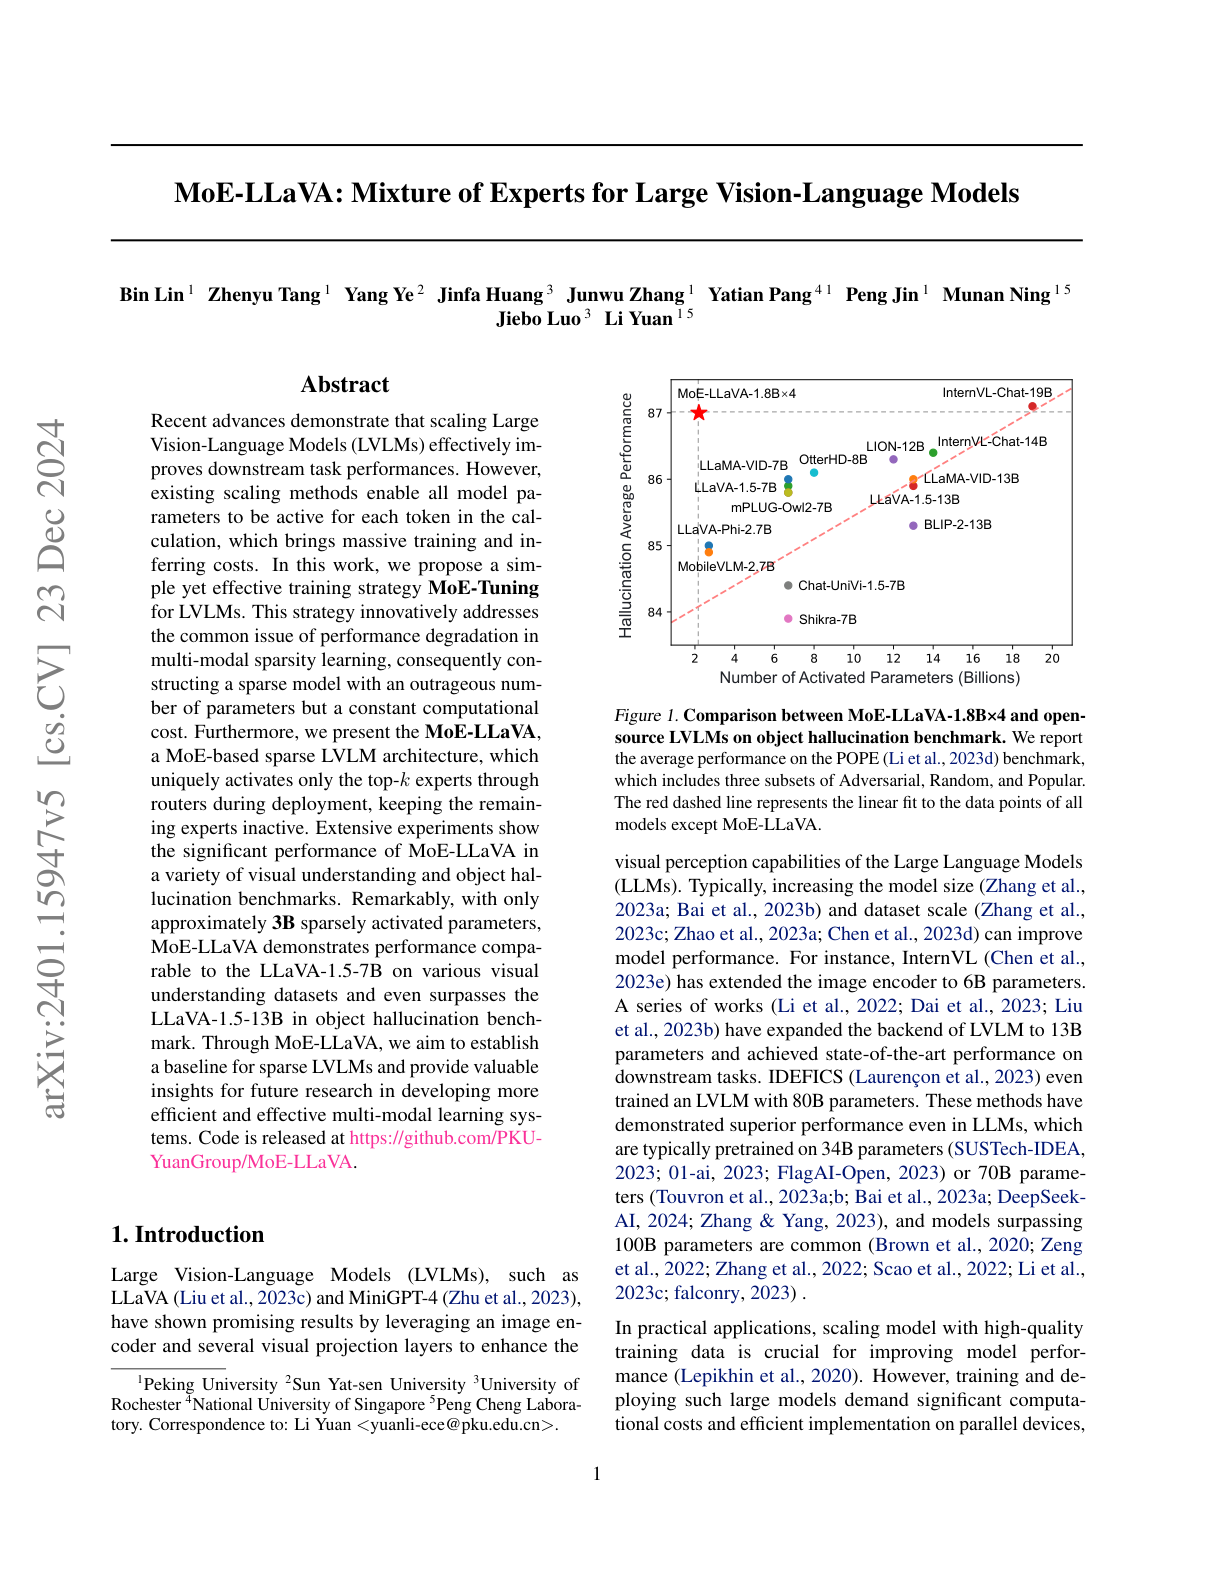
MoE-LLaVA applies Mixture-of-Experts tuning to the LLaVA vision-language architecture, getting a sparse model with dramatically fewer active parameters at the same compute cost.
Ask this paper
MoE for VLMs: Replaces the dense feed-forward layers in LLaVA's decoder with sparse MoE layers and introduces a three-stage training recipe that stabilizes the typically fragile MoE + multimodal combo.
Efficient inference: Only a fraction of experts are active per token, giving the model effective sparsity while keeping FLOPs per forward pass similar to a smaller dense baseline.
Matches larger dense VLMs: A MoE-LLaVA with 3B activated parameters matches or beats 7B dense VLMs on standard multimodal benchmarks, closing the parameter/performance gap.
Mitigates sparsity degradation: The auxiliary balancing losses and staged training schedule address the usual MoE pitfalls of routing collapse and modality interference.