Better and Faster LLMs via Multi-token Prediction
First page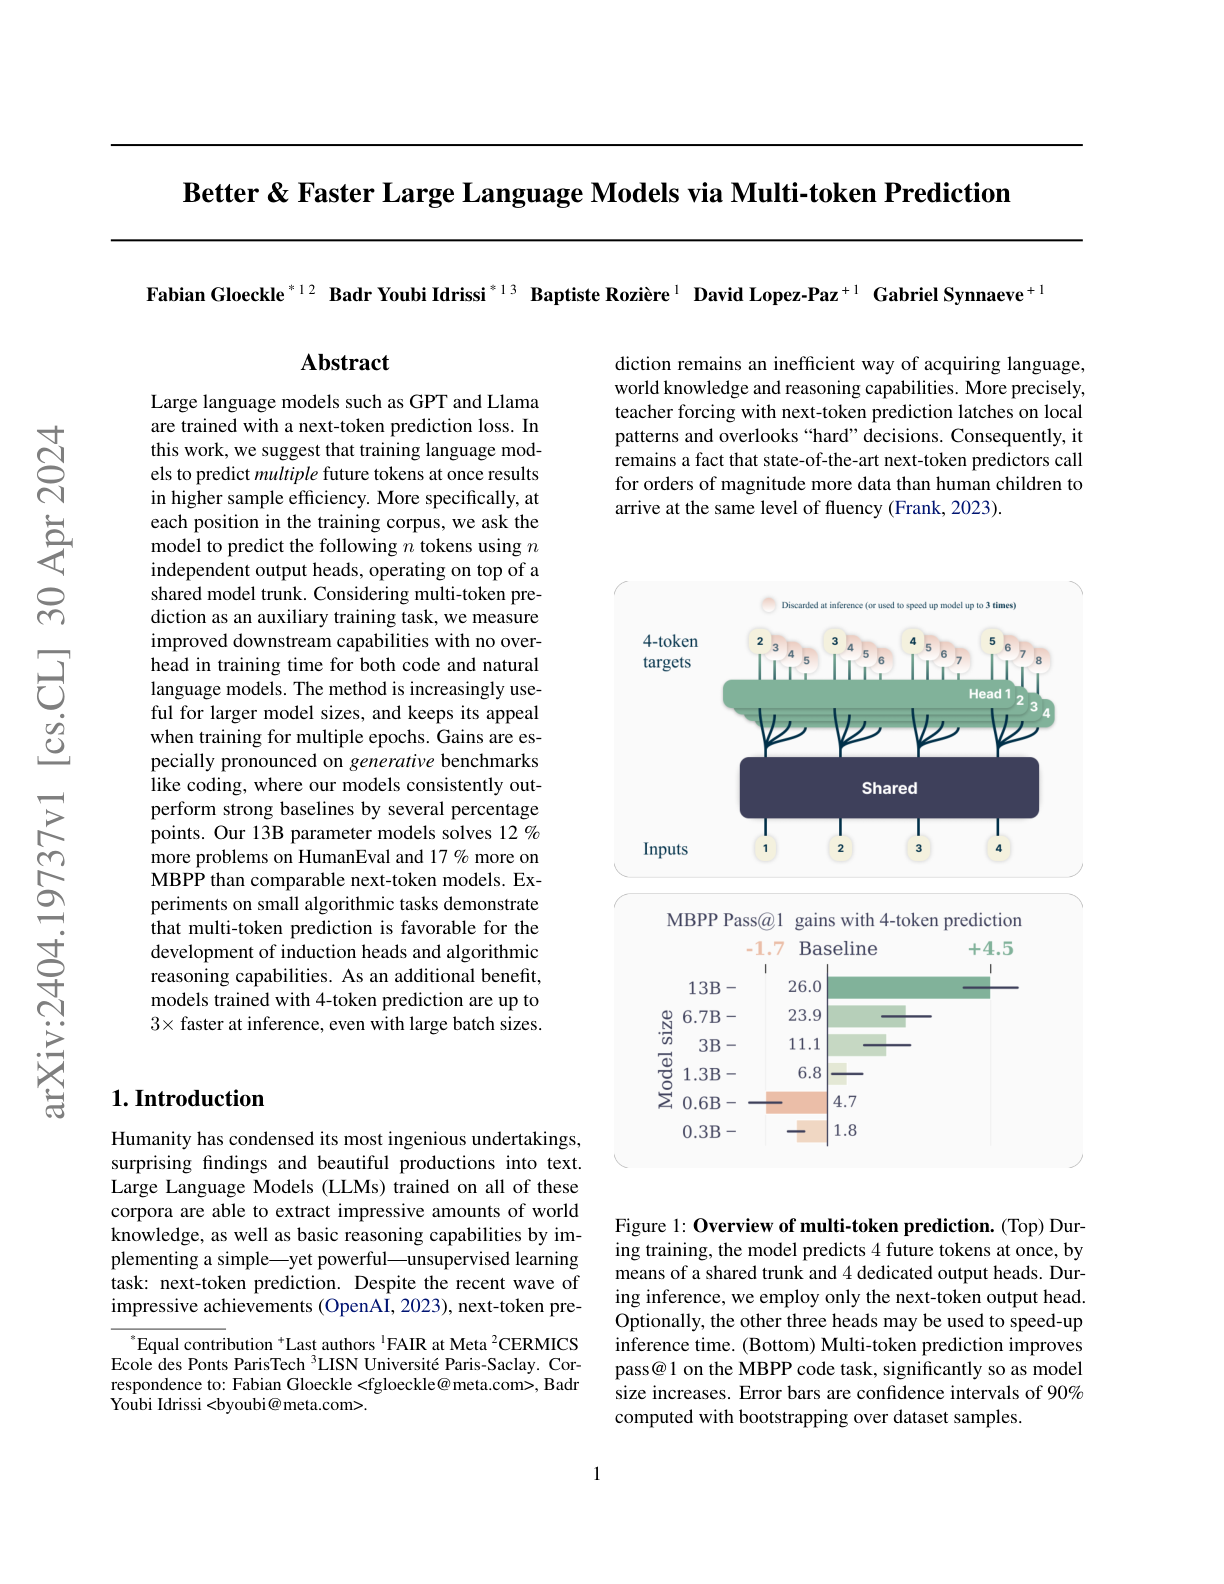
Paper summary
proposes a multi-token prediction approach that performs language modeling by training the predict the following n tokens using n independent output heads; the output heads operate on top of a shared transformer trunk; multi-token prediction is shown to be useful when using larger model sizes and can speed up inference up to 3x; the proposed 13B parameter models solves 12 % more problems on HumanEval and 17 % more on MBPP than comparable next-token models.