Does Prompt Formatting Impact LLM Performance
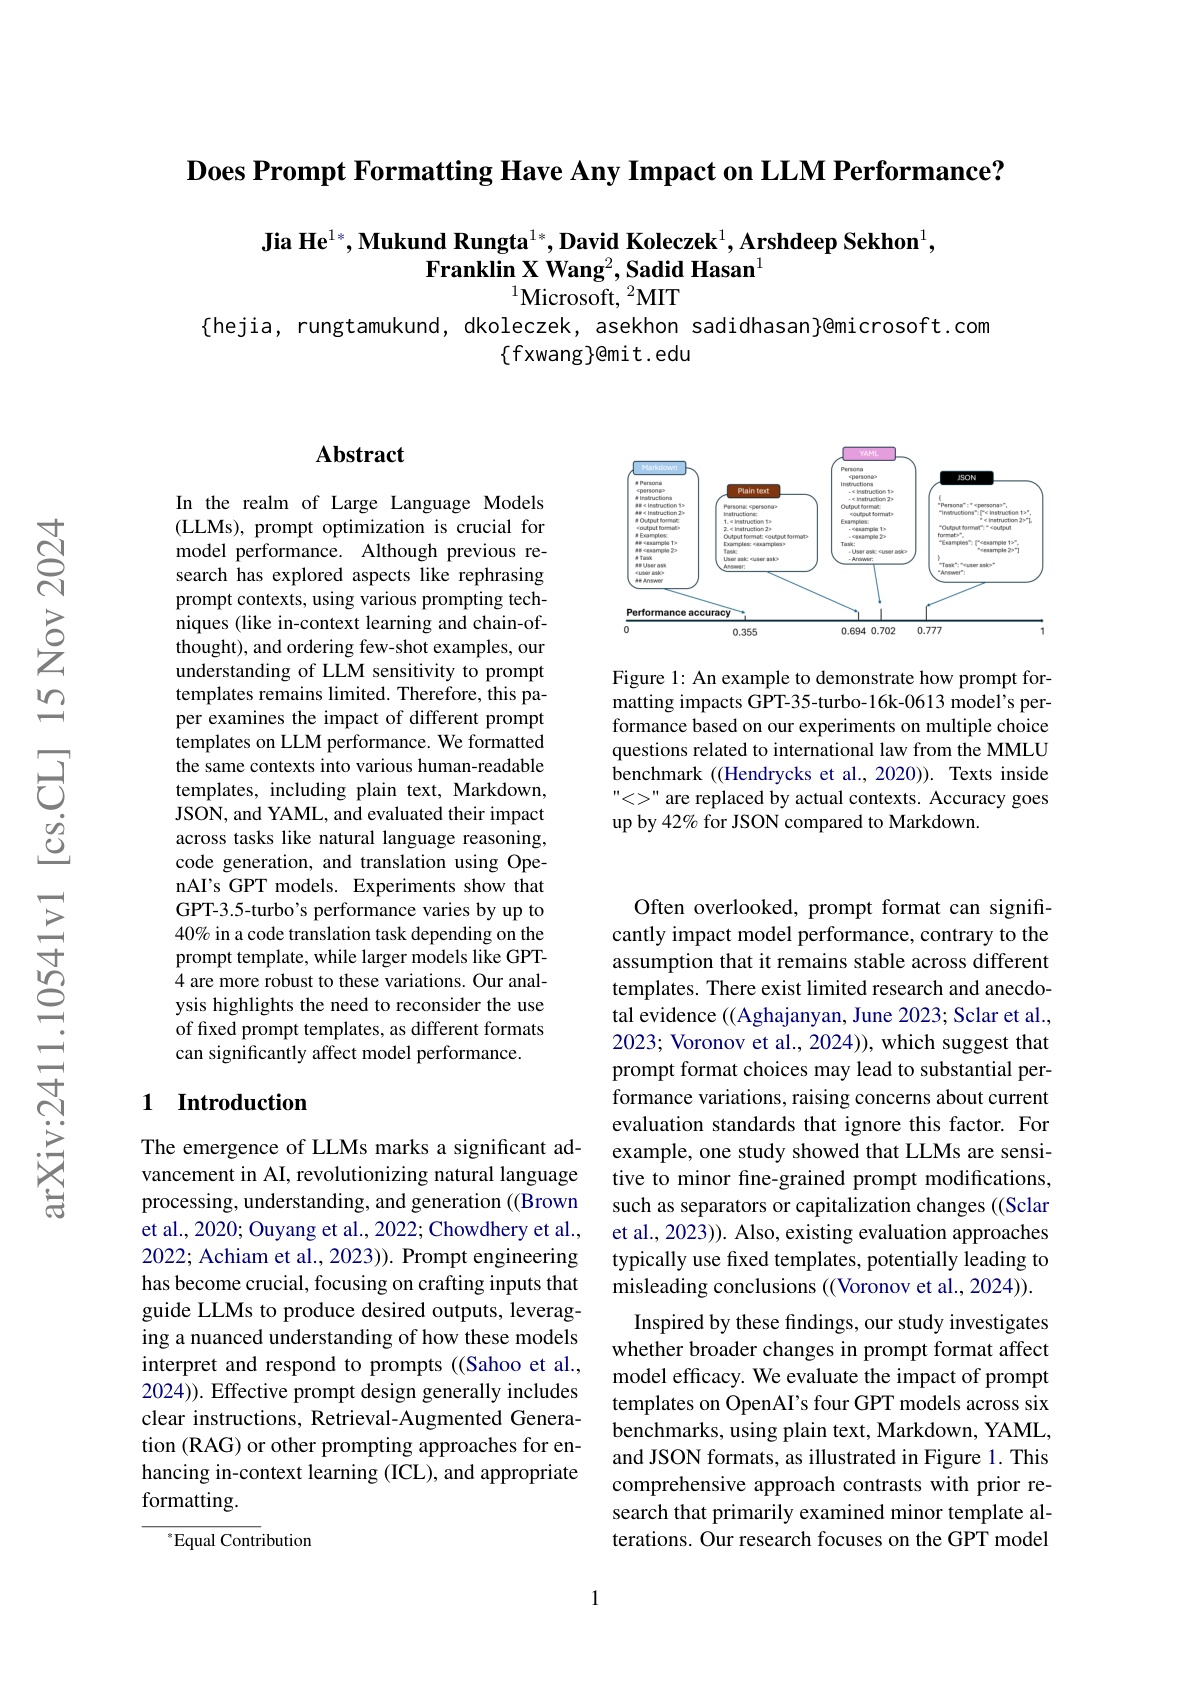
examines how different prompt formats (plain text, Markdown, JSON, and YAML) affect GPT model performance across various tasks; finds that GPT-3.5-turbo's performance can vary by up to 40% depending on the prompt format, while larger models like GPT-4 show more robustness to format changes; argues that there is no universally optimal format across models or tasks - for instance, GPT-3.5-turbo generally performed better with JSON formats while GPT-4 preferred Markdown; models from the same family showed similar format preferences, but these preferences didn't transfer well between different model families; suggests that prompt formatting significantly impacts model performance and should be carefully considered when performing prompt engineering and model evaluation, and how to apply it to applications.