Effective Long-Context Scaling (Meta)
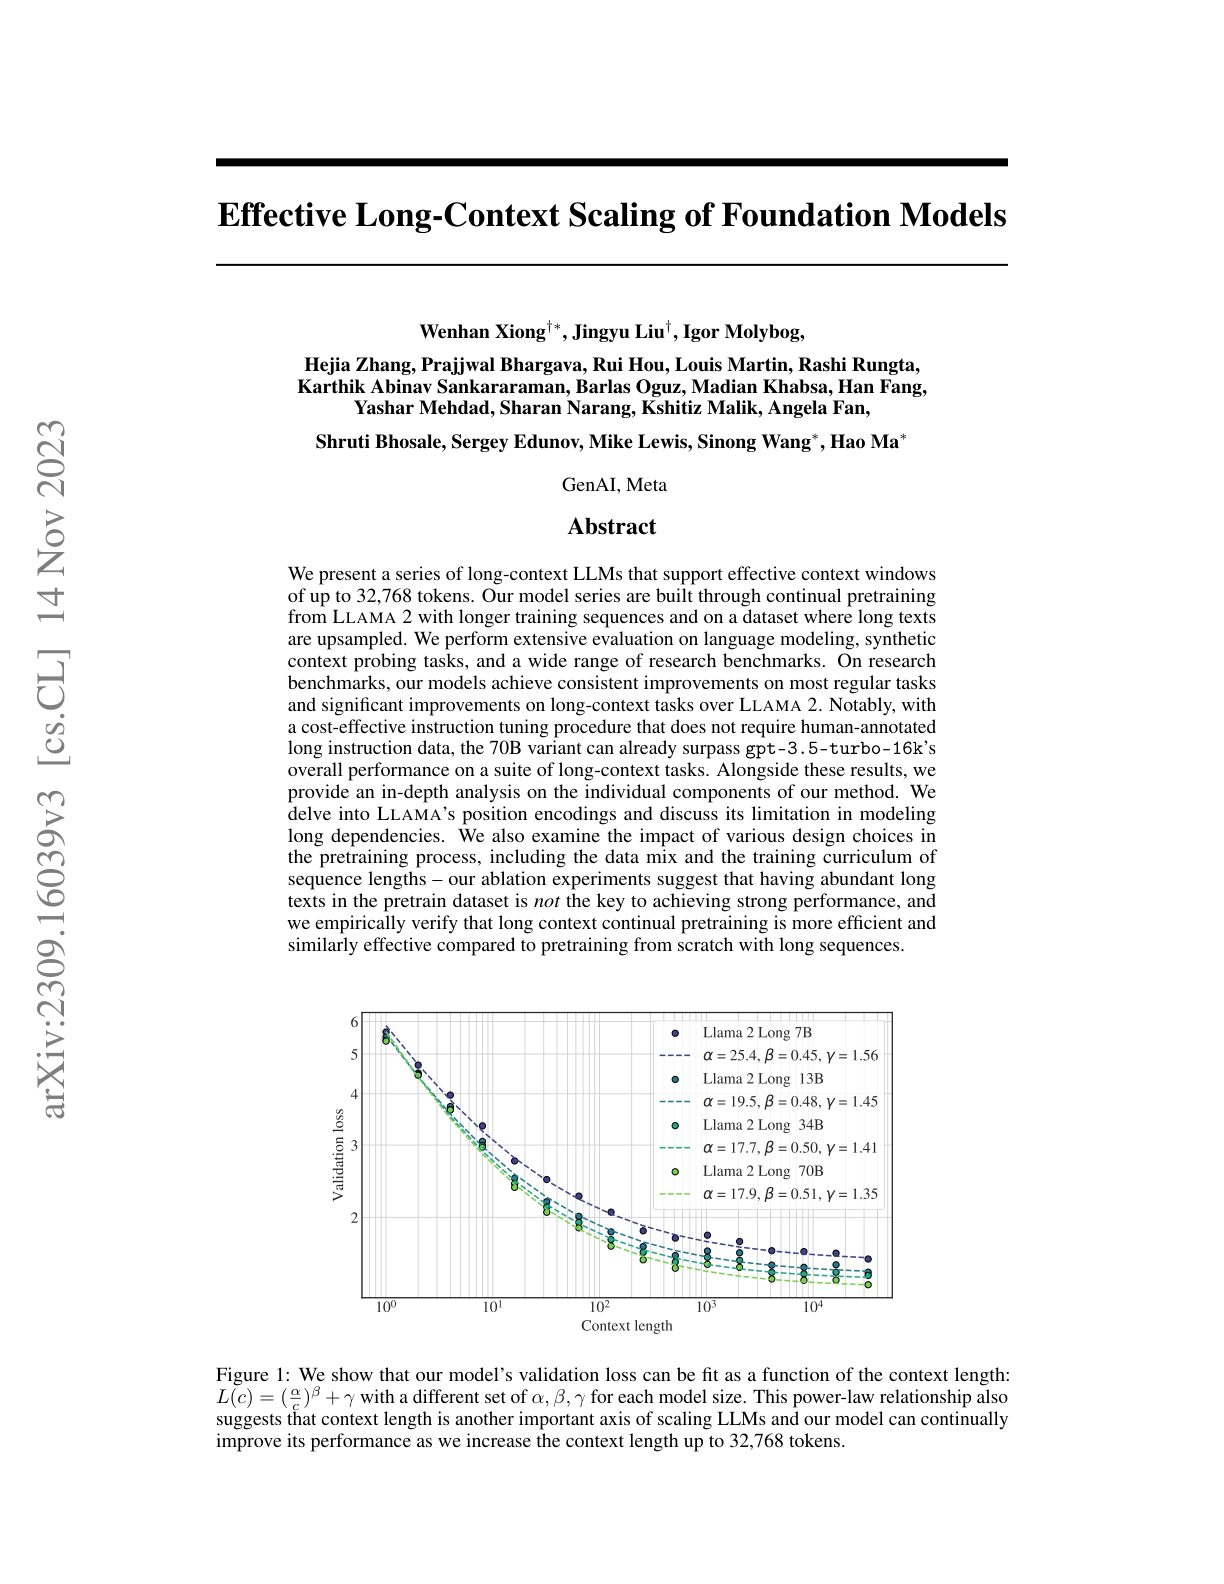
Meta proposes a 70B long-context LLM that surpasses GPT-3.5-turbo-16k on long-context benchmarks.
Ask this paper
Continual pretraining recipe: Uses continual pretraining on long documents to extend Llama 2's context window efficiently, without training a new model from scratch.
Beats GPT-3.5-turbo-16k: The 70B variant outperforms GPT-3.5-turbo-16k on a suite of long-context tasks including document QA, summarization, and multi-hop reasoning.
Cost-effective instruction tuning: Introduces an instruction-tuning procedure that doesn't require human-annotated long-instruction data - a common bottleneck for long-context fine-tuning.
Open release: Produces an open long-context Llama 2 variant, making strong long-context capability accessible to the research community.