Vision Transformers Need Registers
First page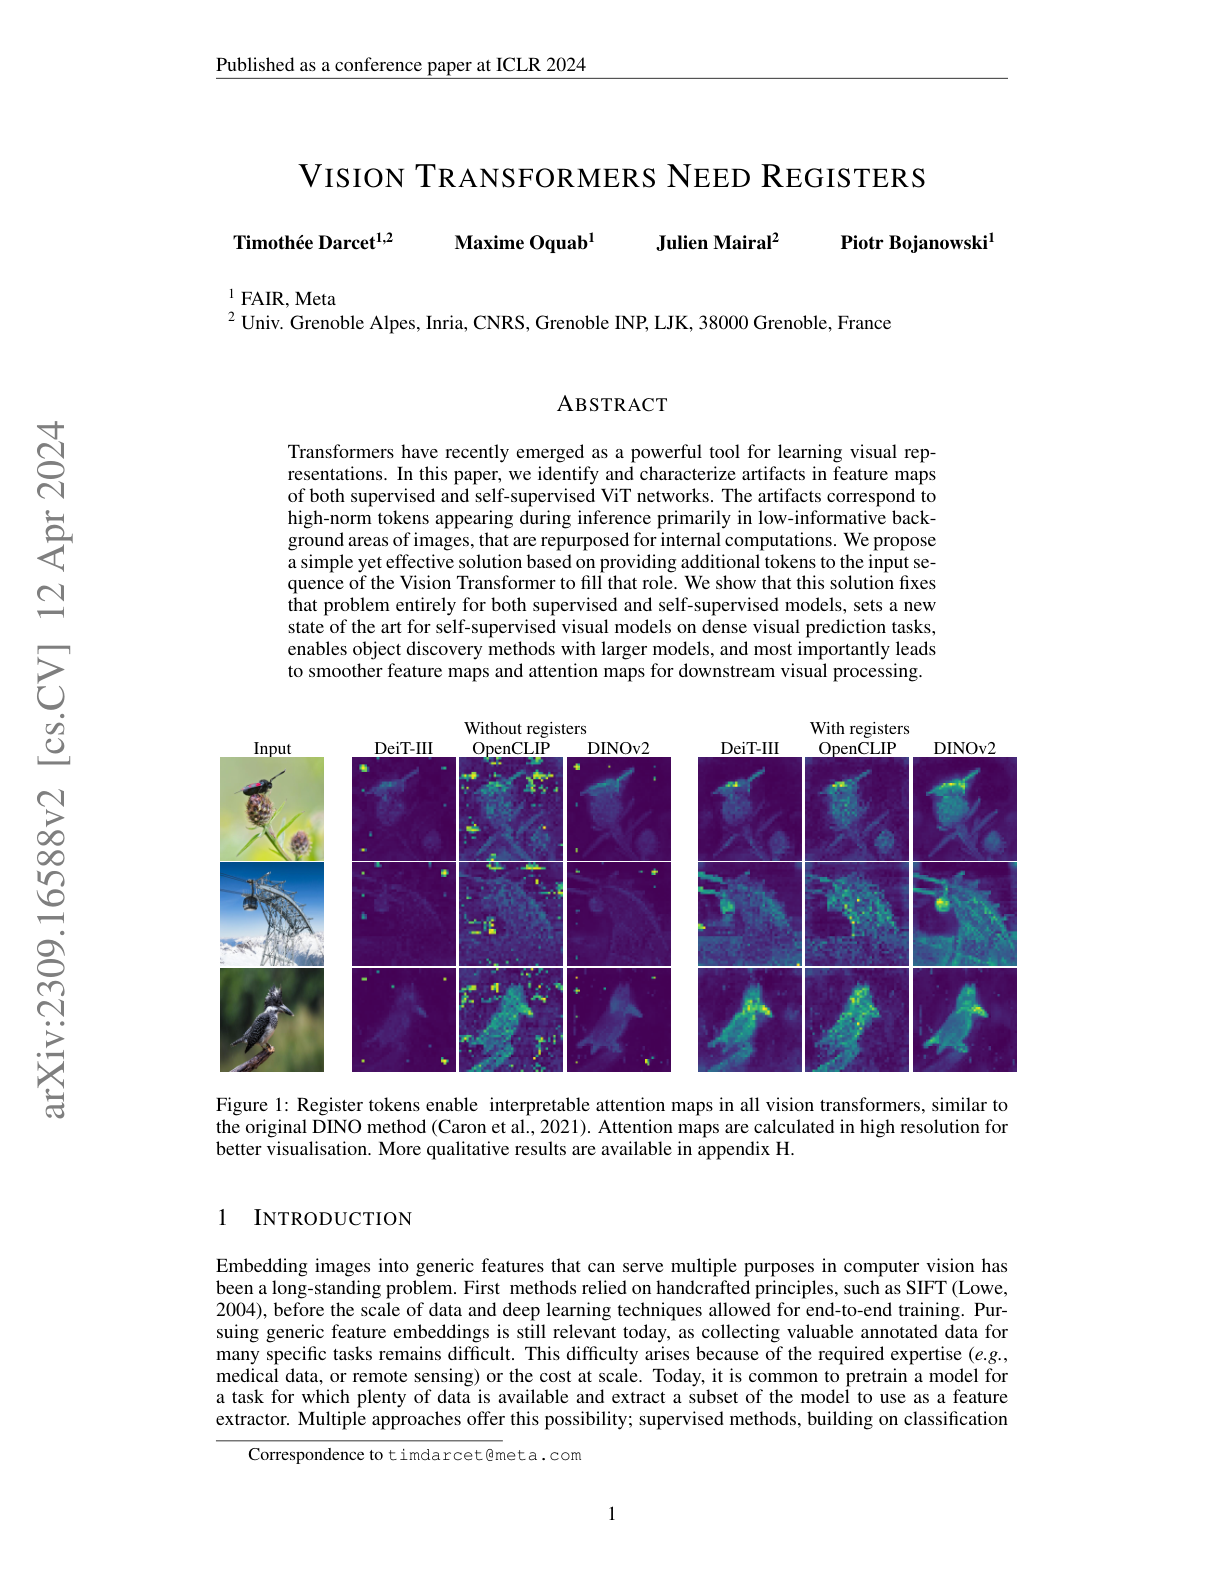
Paper summary
Meta researchers identify artifact tokens in ViT feature maps and propose a trivial fix: add dedicated register tokens.
Ask this paper
01
Artifact identification: Vision transformers repurpose certain input tokens as "internal scratch space", producing high-norm artifacts that contaminate feature maps.
02
Register tokens: Adds a small number of dedicated register tokens to the input sequence, giving the model explicit scratch space instead of co-opting patch tokens.
03
Cleaner features: The fix produces substantially smoother feature and attention maps, with the artifact tokens disappearing.
04
New SoTA on dense tasks: Sets new state-of-the-art results on dense visual prediction tasks (segmentation, depth, object discovery), with real downstream impact.