Efficient Inference of LLMs
First page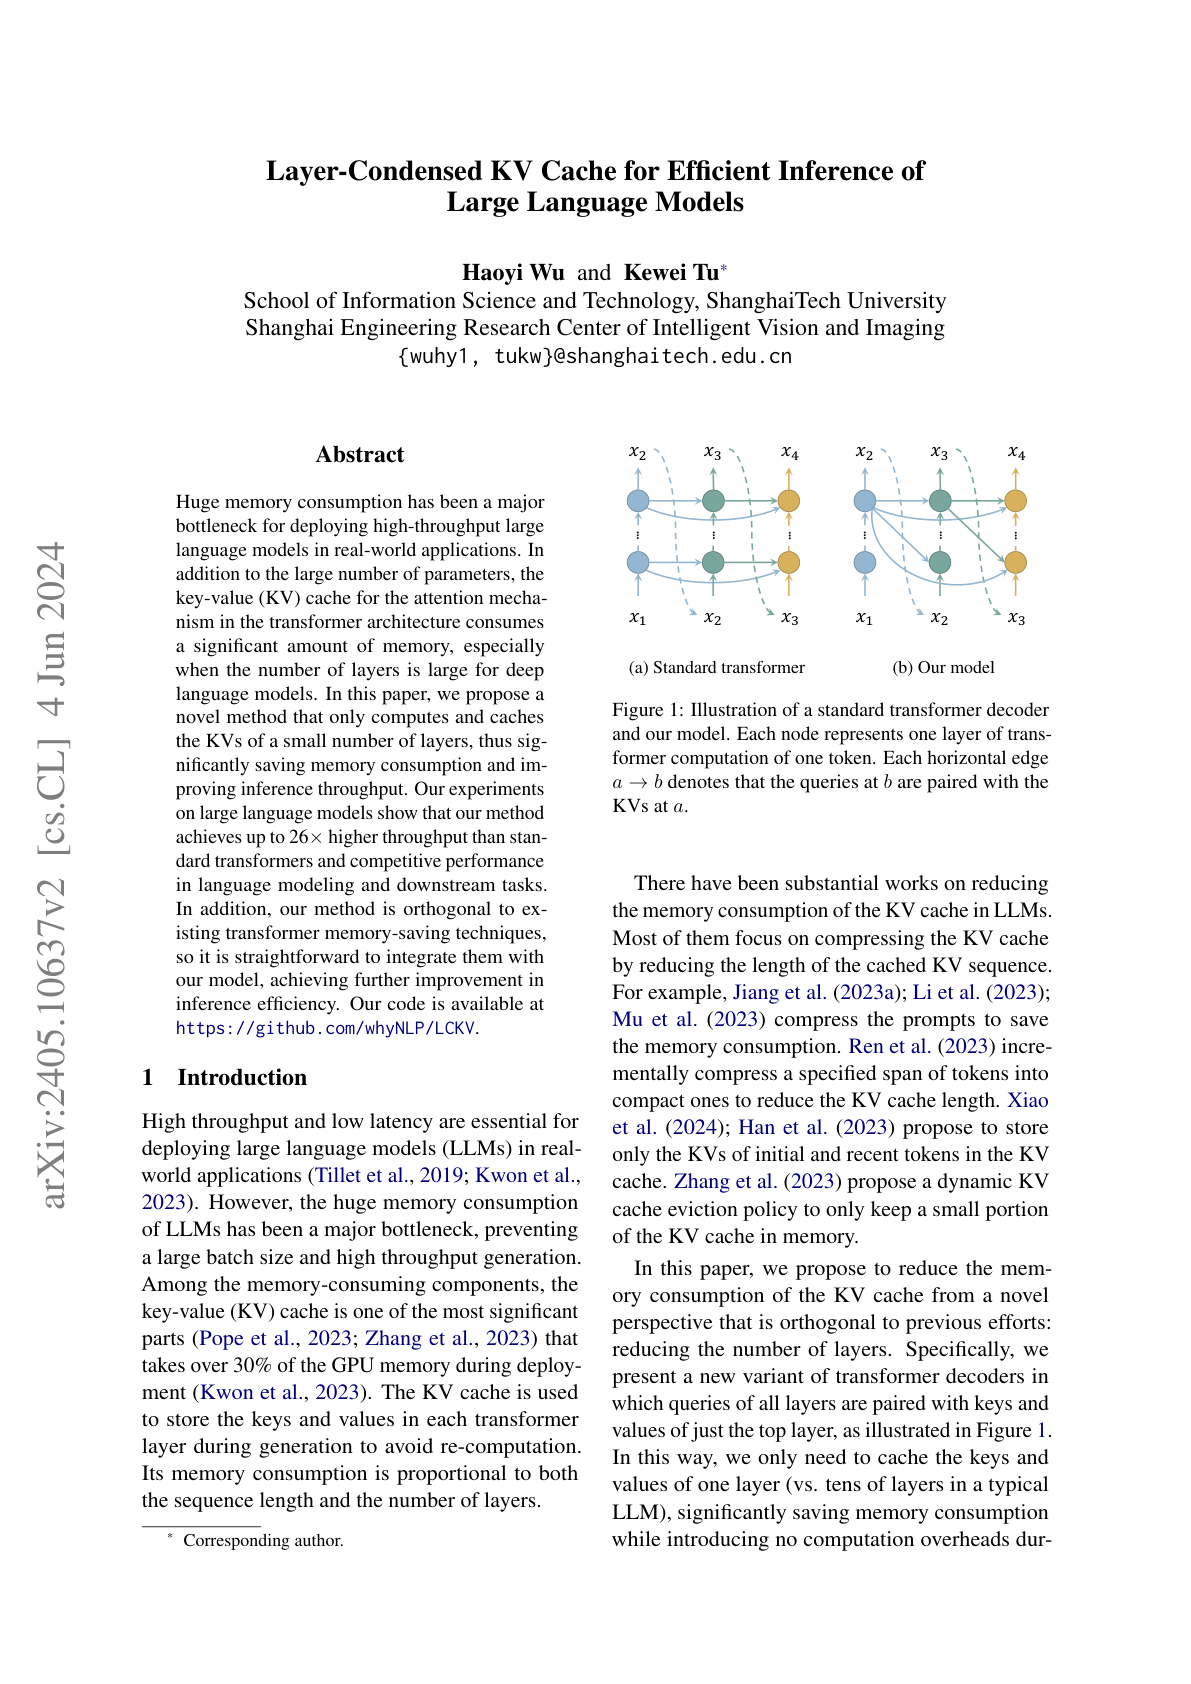
Paper summary
proposes a layer-condensed KV cache to achieve efficient inference in LLMs; only computes and caches the key-values (KVs) of a small number of layers which leads to saving memory consumption and improved inference throughput; can achieve up to 26x higher throughput than baseline transformers while maintaining satisfactory performance.