End-to-End Policy Optimization for GUI Agents
First page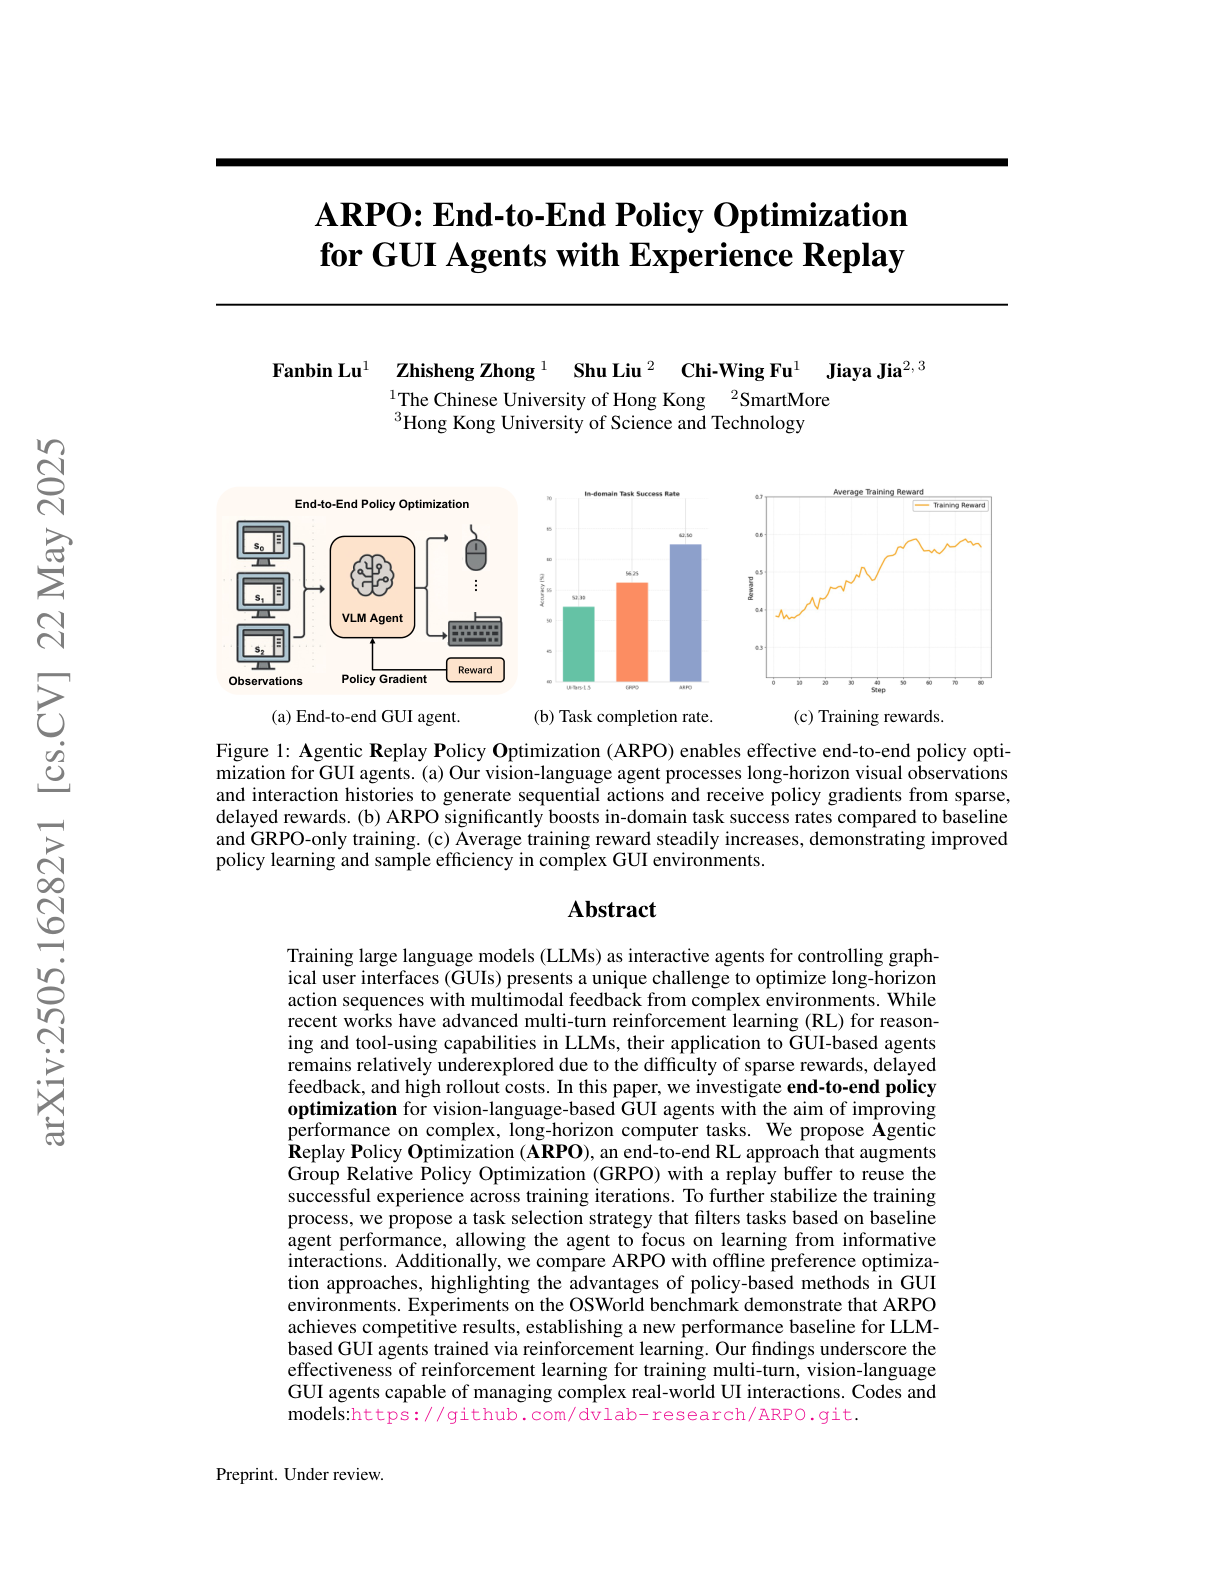
Paper summary
ARPO introduces an end-to-end reinforcement learning method for training GUI agents using Group Relative Policy Optimization (GRPO) with experience replay. It significantly improves in-domain performance on the OSWorld benchmark, outperforming baselines by up to 6.7%, while offering modest gains on out-of-domain tasks and enabling self-corrective behaviors through structured reward feedback.