Fugatto
First page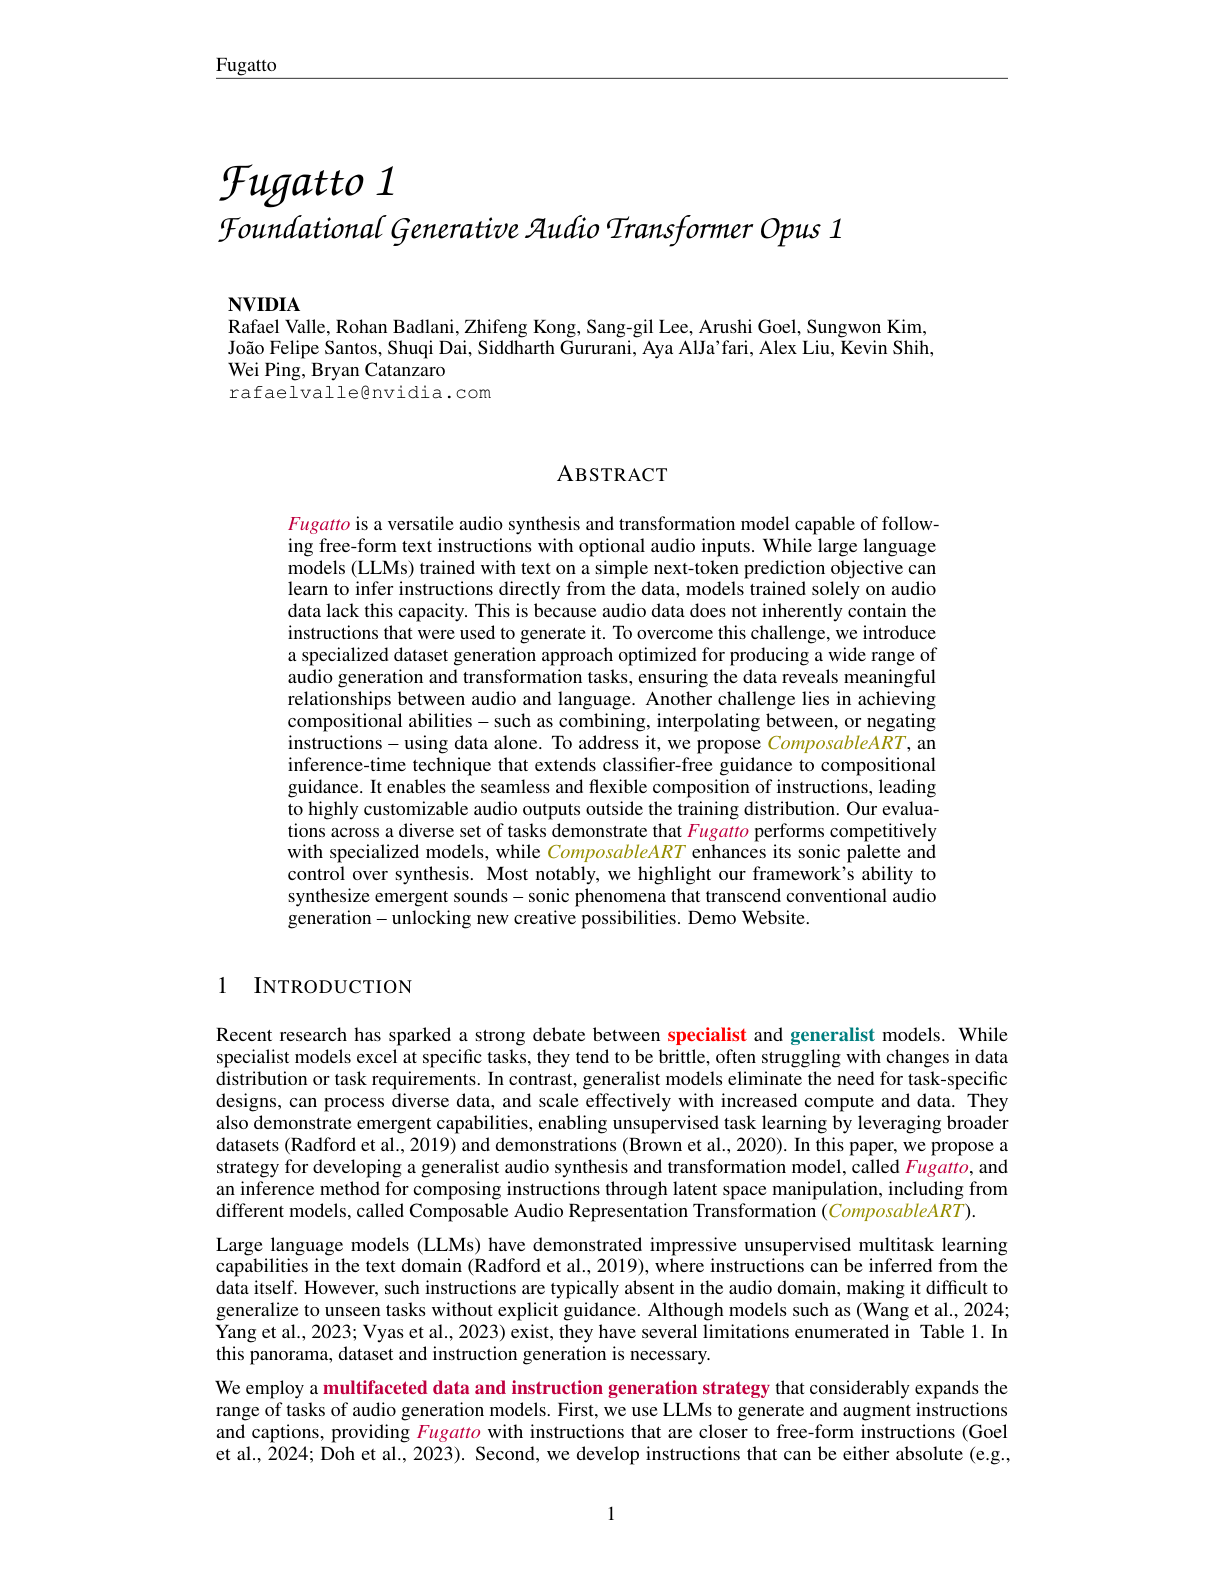
Paper summary
a new generative AI sound model (presented by NVIDIA) that can create and transform any combination of music, voices, and sounds using text and audio inputs, trained on 2.5B parameters and capable of novel audio generation like making trumpets bark or saxophones meow.