How Language Models Use Long Contexts (Lost-in-the-Middle)
First page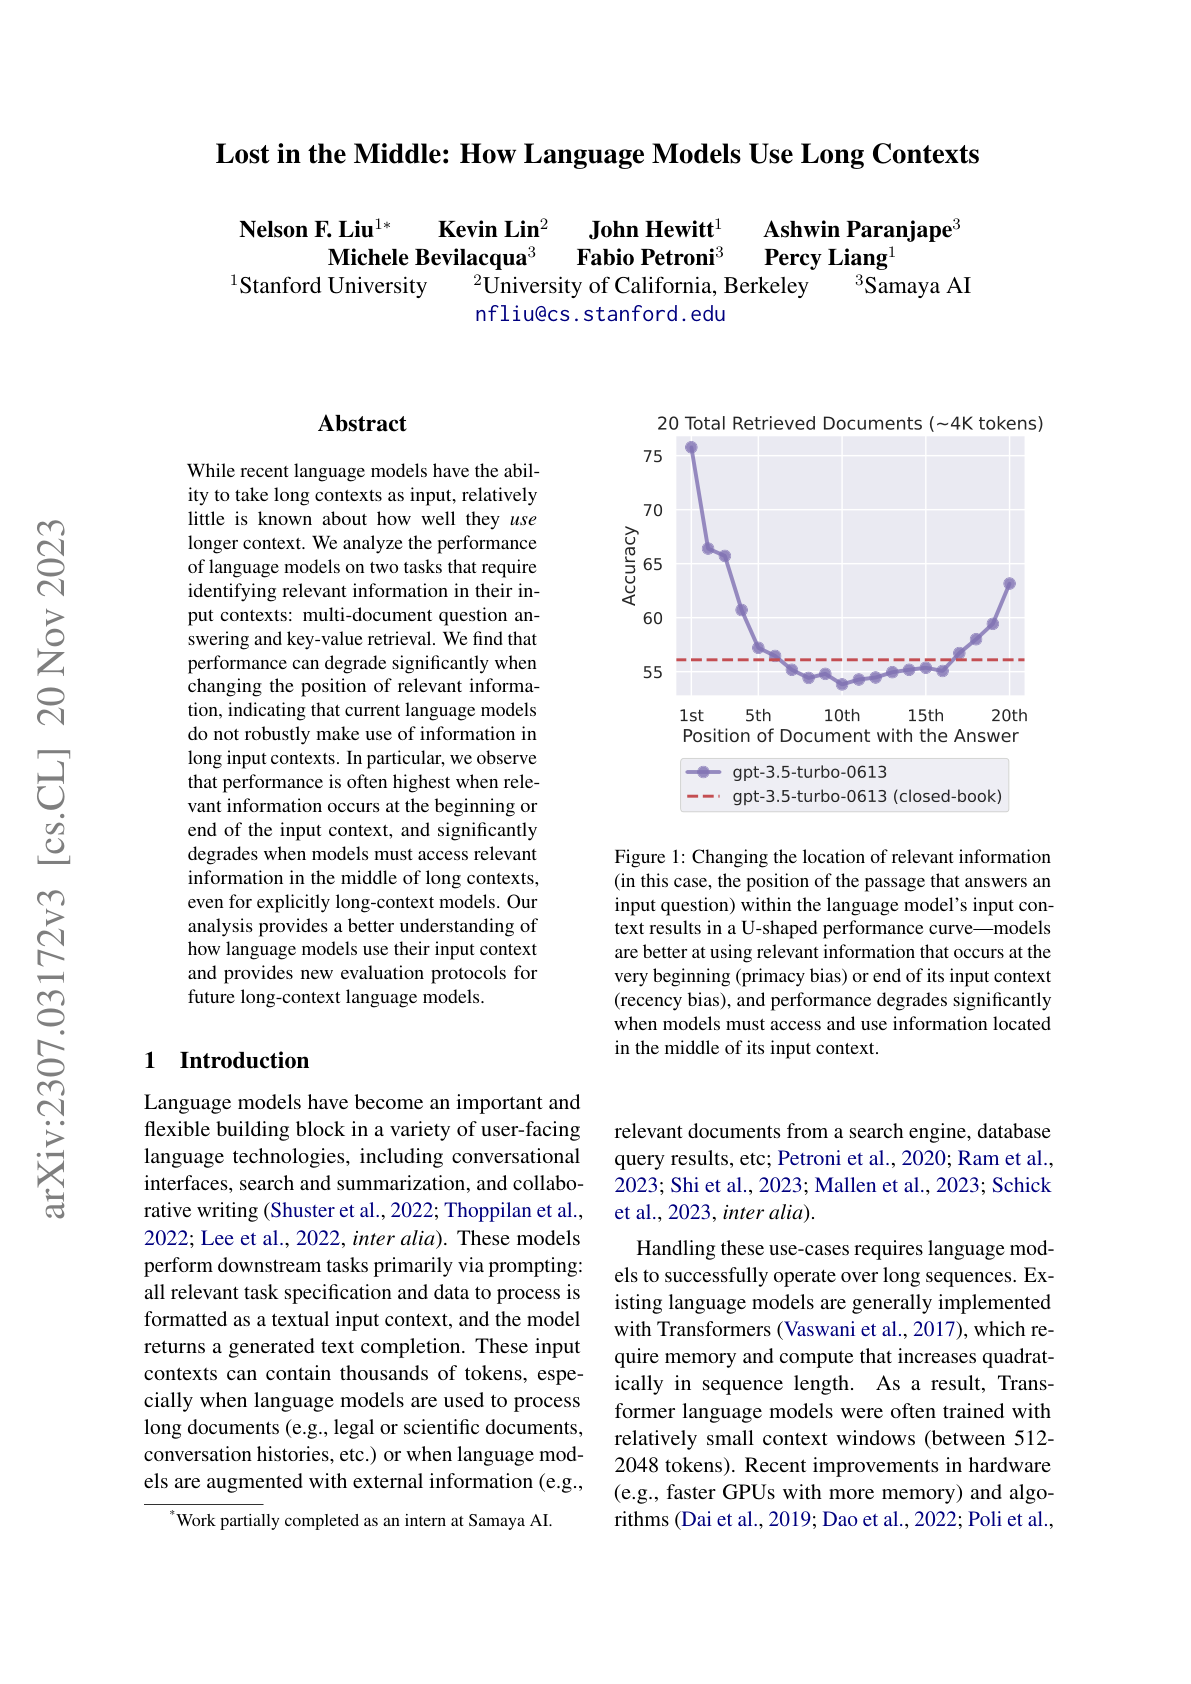
Paper summary
Shows LLM performance drops when relevant information is in the middle of a long context.
Ask this paper
01
U-shaped performance curve: LMs perform best when relevant info is at the start or end of context, with substantial degradation for middle positions.
02
Cross-model phenomenon: Confirmed across GPT-3.5, GPT-4, Claude, and open-weight models - indicating a fundamental attention pattern rather than a bug.
03
QA and retrieval benchmarks: Demonstrated on multi-document QA and key-value retrieval tasks with varying context positions.
04
Foundational finding: Coined the phrase "lost in the middle" - one of the most widely-cited 2023 findings that shaped subsequent long-context benchmark and model design.