Multimodal Generation with Frozen LLMs
First page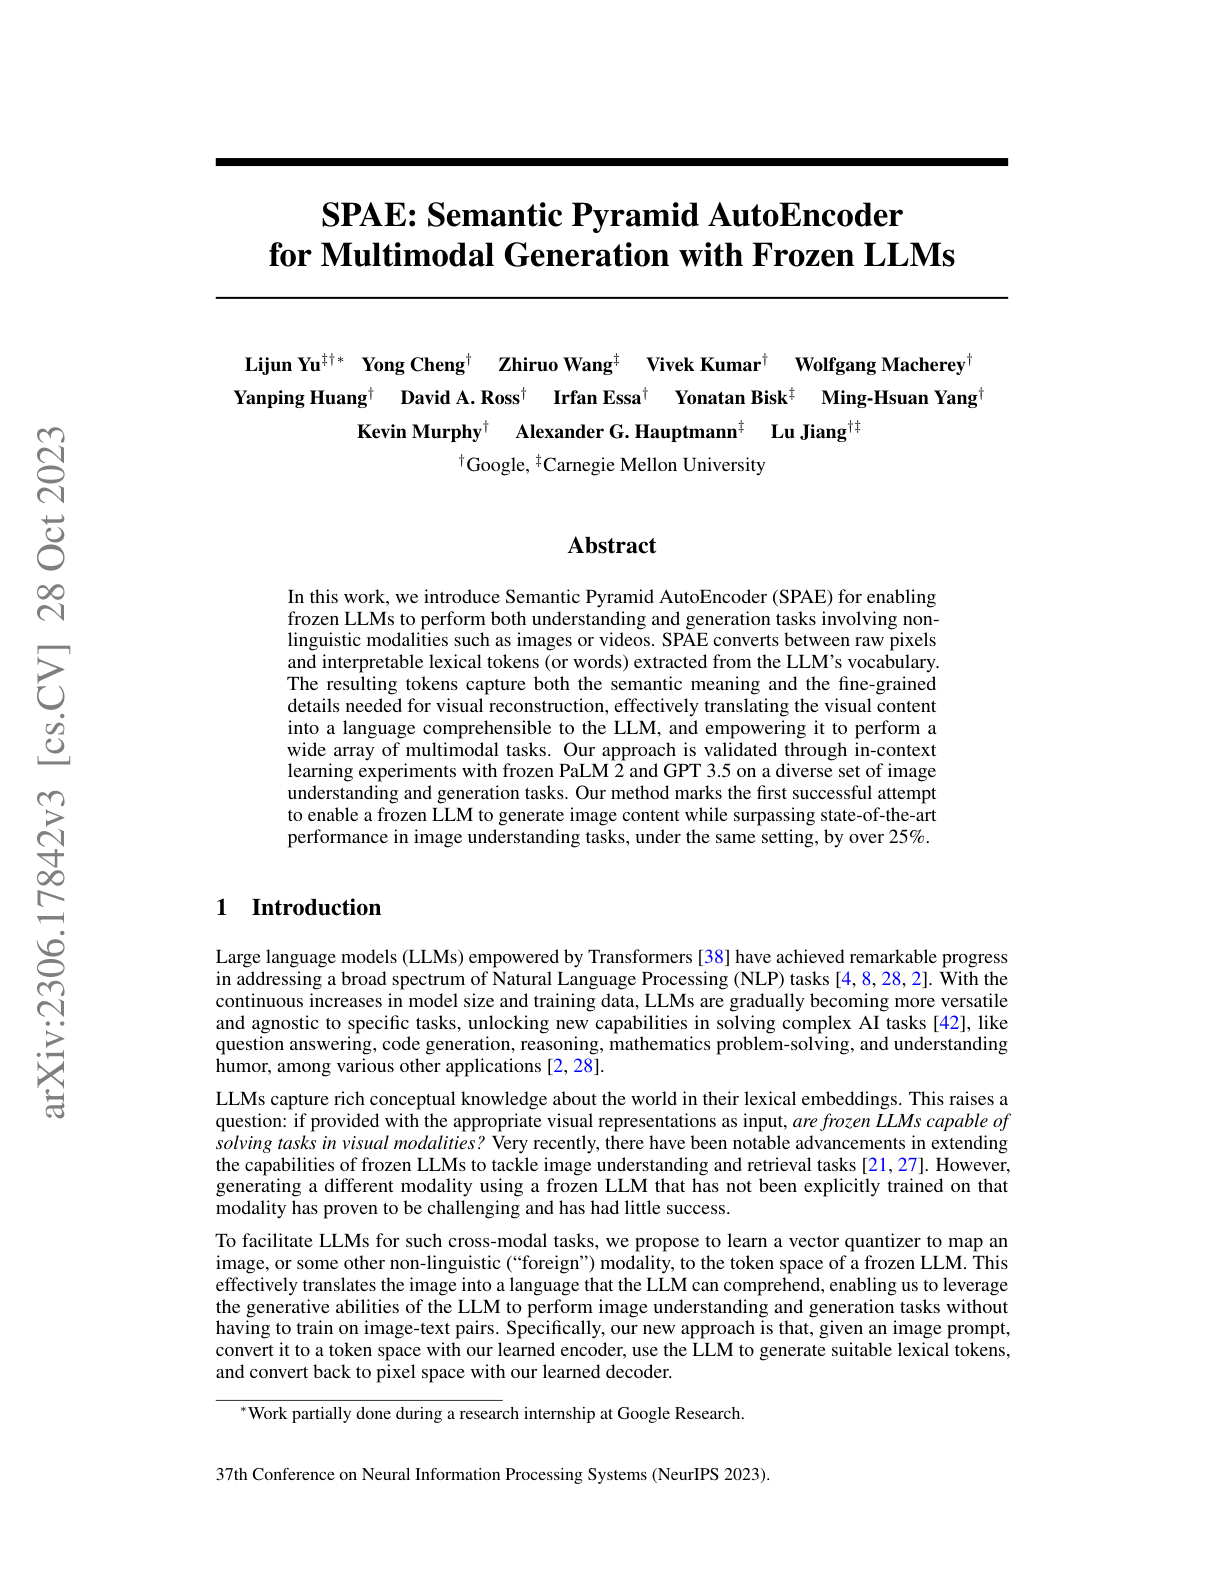
Paper summary
Maps images to LLM token space enabling models like PaLM and GPT-4 to handle visual tasks without parameter updates.
Ask this paper
01
Frozen LLM design: Keeps the underlying LLM completely frozen - only a lightweight image-to-token projection layer is trained.
02
Parameter-efficient multimodal: Enables multimodal capabilities without fine-tuning large LLMs, drastically reducing compute cost.
03
In-context visual tasks: Uses in-context learning to tackle VQA, image captioning, and visual reasoning with zero LLM modification.
04
Plug-in VLM pattern: An early example of the "frozen LLM + visual adapter" design that became dominant in open-source VLMs through 2024.