HtmlRAG
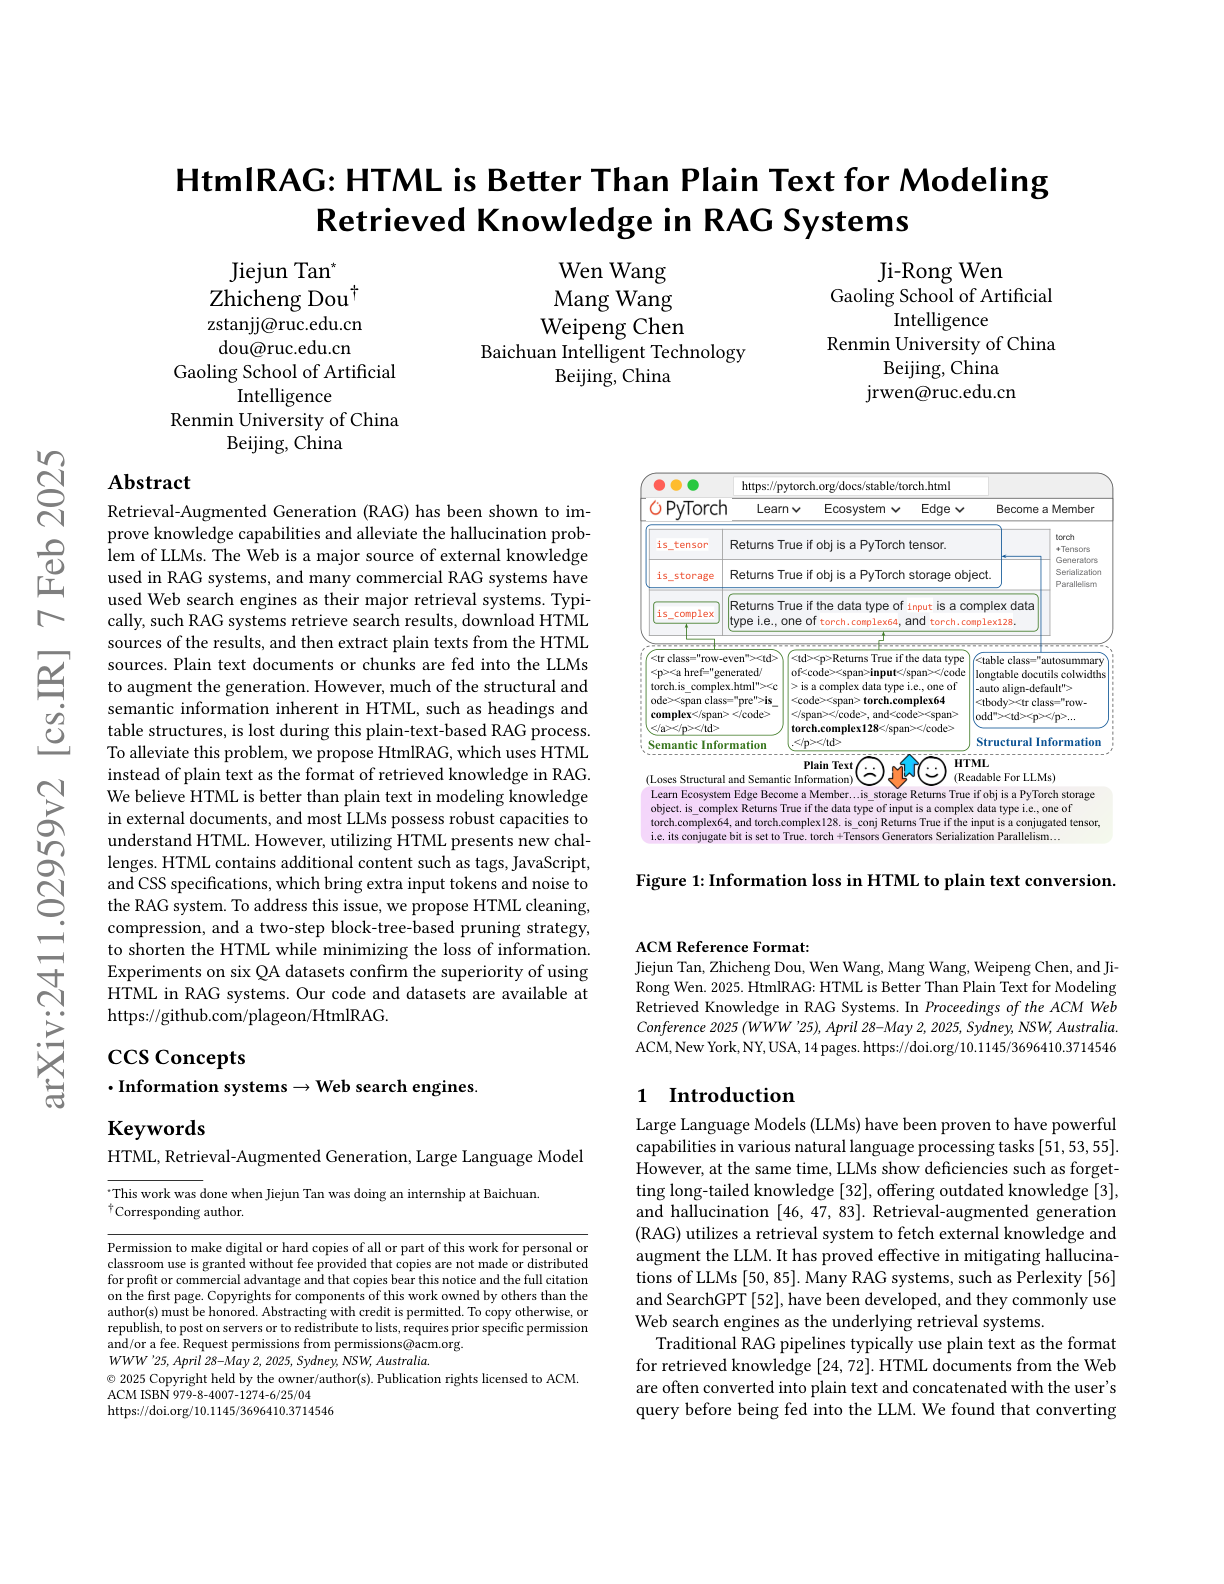
a novel approach that proposes using HTML instead of plain text as the format for building RAG systems; the key finding is that preserving HTML structure provides richer semantic and structural information compared to plain text conversion, which typically loses important formatting like headings, tables, and semantic tags; to address the challenge of HTML documents being too long for LLM context windows, the authors develop a two-step pruning method: first cleaning unnecessary HTML elements (reducing length by 94%), then using a block-tree-based pruning approach that combines embedding-based and generative pruning to further reduce the content while maintaining important information; experiments across six different QA datasets demonstrate that HtmlRAG outperforms existing plain-text based methods, validating the advantages of preserving HTML structure in RAG systems.