Imagine while Reasoning in Space
First page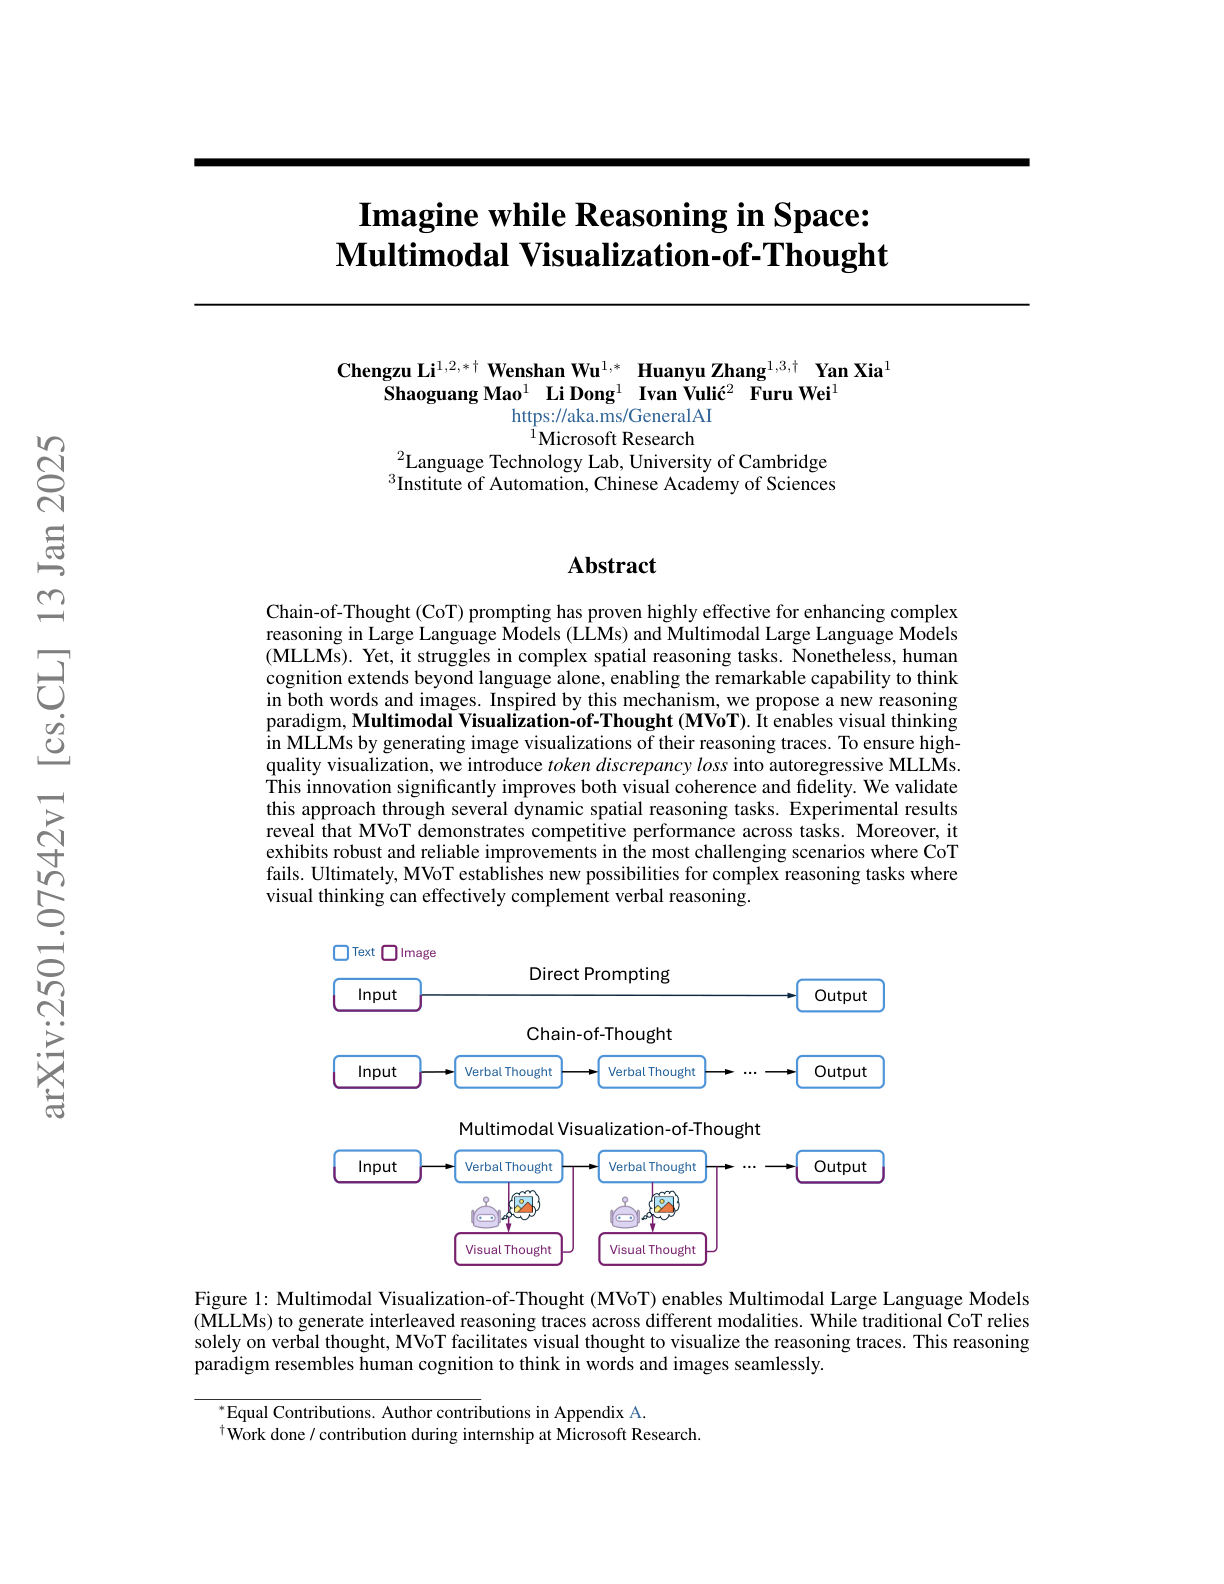
Paper summary
introduces MVoT (Multimodal Visualization-of-Thought), a new reasoning framework that enables AI models to "think" in both text and images; MVoT enhances the traditional Chain-of-Thought prompting by allowing models to generate visual representations of their reasoning steps alongside text explanations; the framework is implemented in Chameleon-7B, a multimodal language model, and introduces a "token discrepancy loss" to improve the quality of generated visualizations; MVoT significantly outperforms traditional approaches, especially in complex scenarios; MVoT achieves over 90% accuracy on maze and printer installation tasks.