InseRF
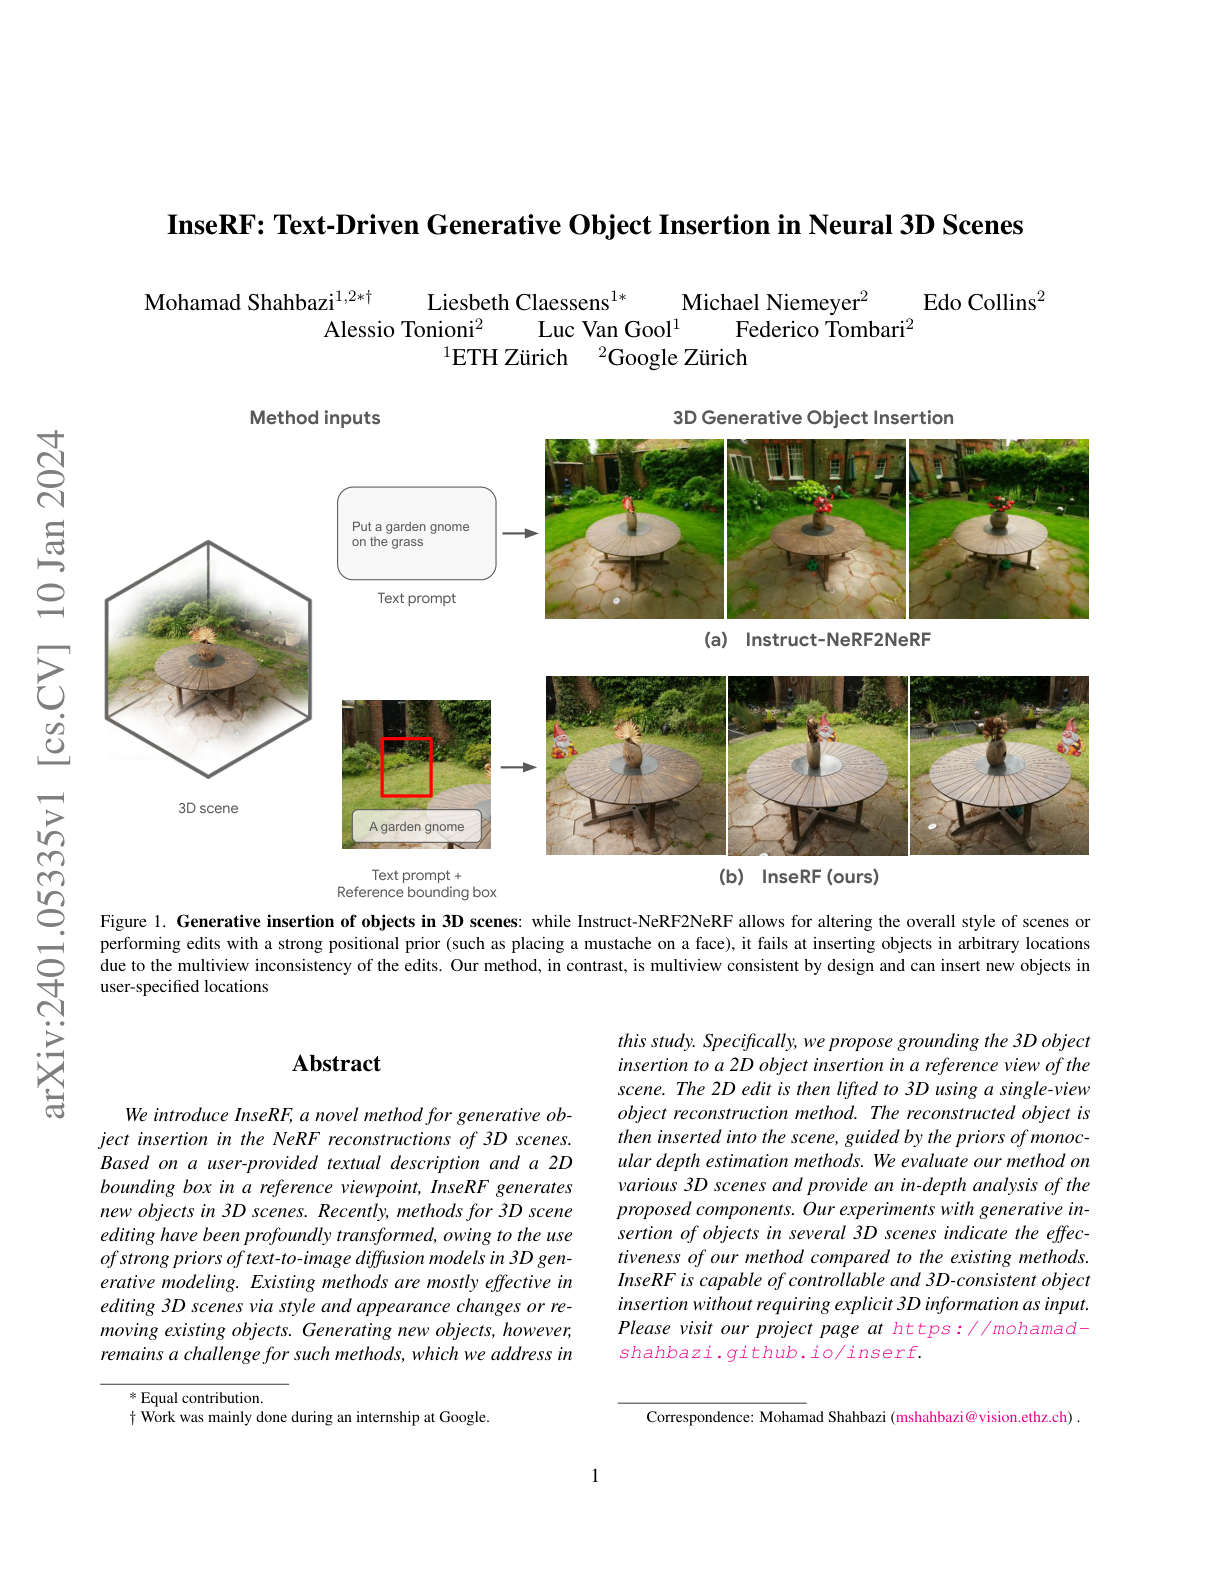
InseRF inserts brand-new 3D objects into Neural Radiance Field scenes from just a text prompt plus a 2D bounding box, without requiring any explicit 3D input.
Ask this paper
Text-driven 3D insertion: Users specify what to insert in natural language and where to place it with a 2D box in a single reference view; InseRF figures out the 3D placement.
No explicit 3D signals: Unlike prior NeRF-editing methods that require depth maps or explicit geometry, InseRF grounds insertion from 2D signals alone.
3D-consistent: Inserted objects remain consistent across viewpoints and lighting conditions, avoiding the flickering and multi-face artifacts common in naive diffusion-into-NeRF pipelines.
Practical implication: Brings "add a red vase on this table" editing to NeRF content, a step toward natural-language 3D content creation without manual modeling.