Learning at Test Time
First page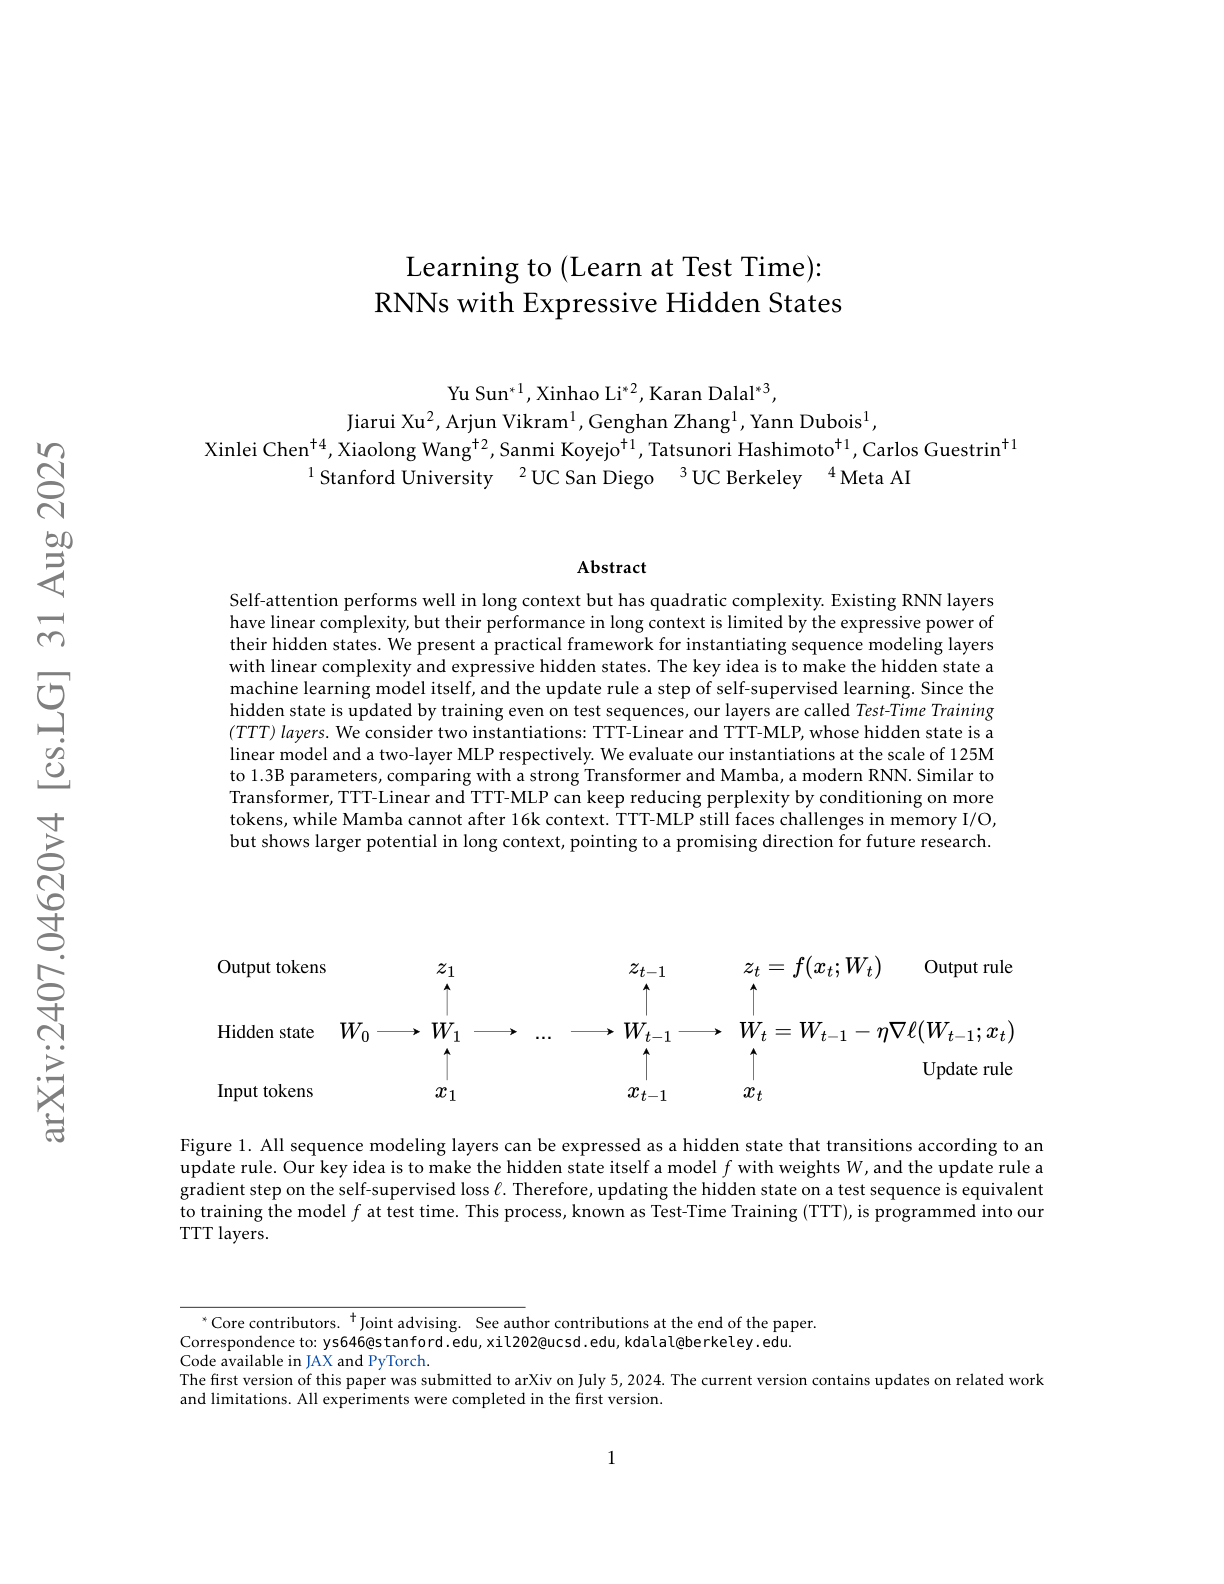
Paper summary
proposes new sequence modeling layers with linear complexity and an expressive hidden state; defines a hidden state as an ML model itself capable of updating even on test sequence; by a linear model and a two-layer MLP based hidden state is found to match or exceed baseline models like Transformers, Mamba, and modern RNNs; the linear model is faster than Transformer at 8k context and matches Mamba in wall-clock time.