LIMBO: Lifelong Inference-Time Memory and Budget Optimization for LLM Agents
Siddharth Sharma and colleagues at UC San Diego and West Virginia University introduce LIMBO, an online method that decides for each incoming task how much past experience a lifelong agent should replay into its prompt and how much inference budget to spend.
Ask this paper
Problem: Replayed trajectories compete with retrieval, reasoning, tool use and verification for the same prompt and compute budget, but existing methods use a fixed replay policy.
Method: LIMBO treats memory as a controllable inference-time resource and learns the allocation online in one pass, without model weights, teacher supervision or offline retraining.
Results: On LifelongAgentBench with three backbones, it nearly matches the strongest memory-augmented baselines at up to about 83% lower inference cost, about 53% on average.
Abstract
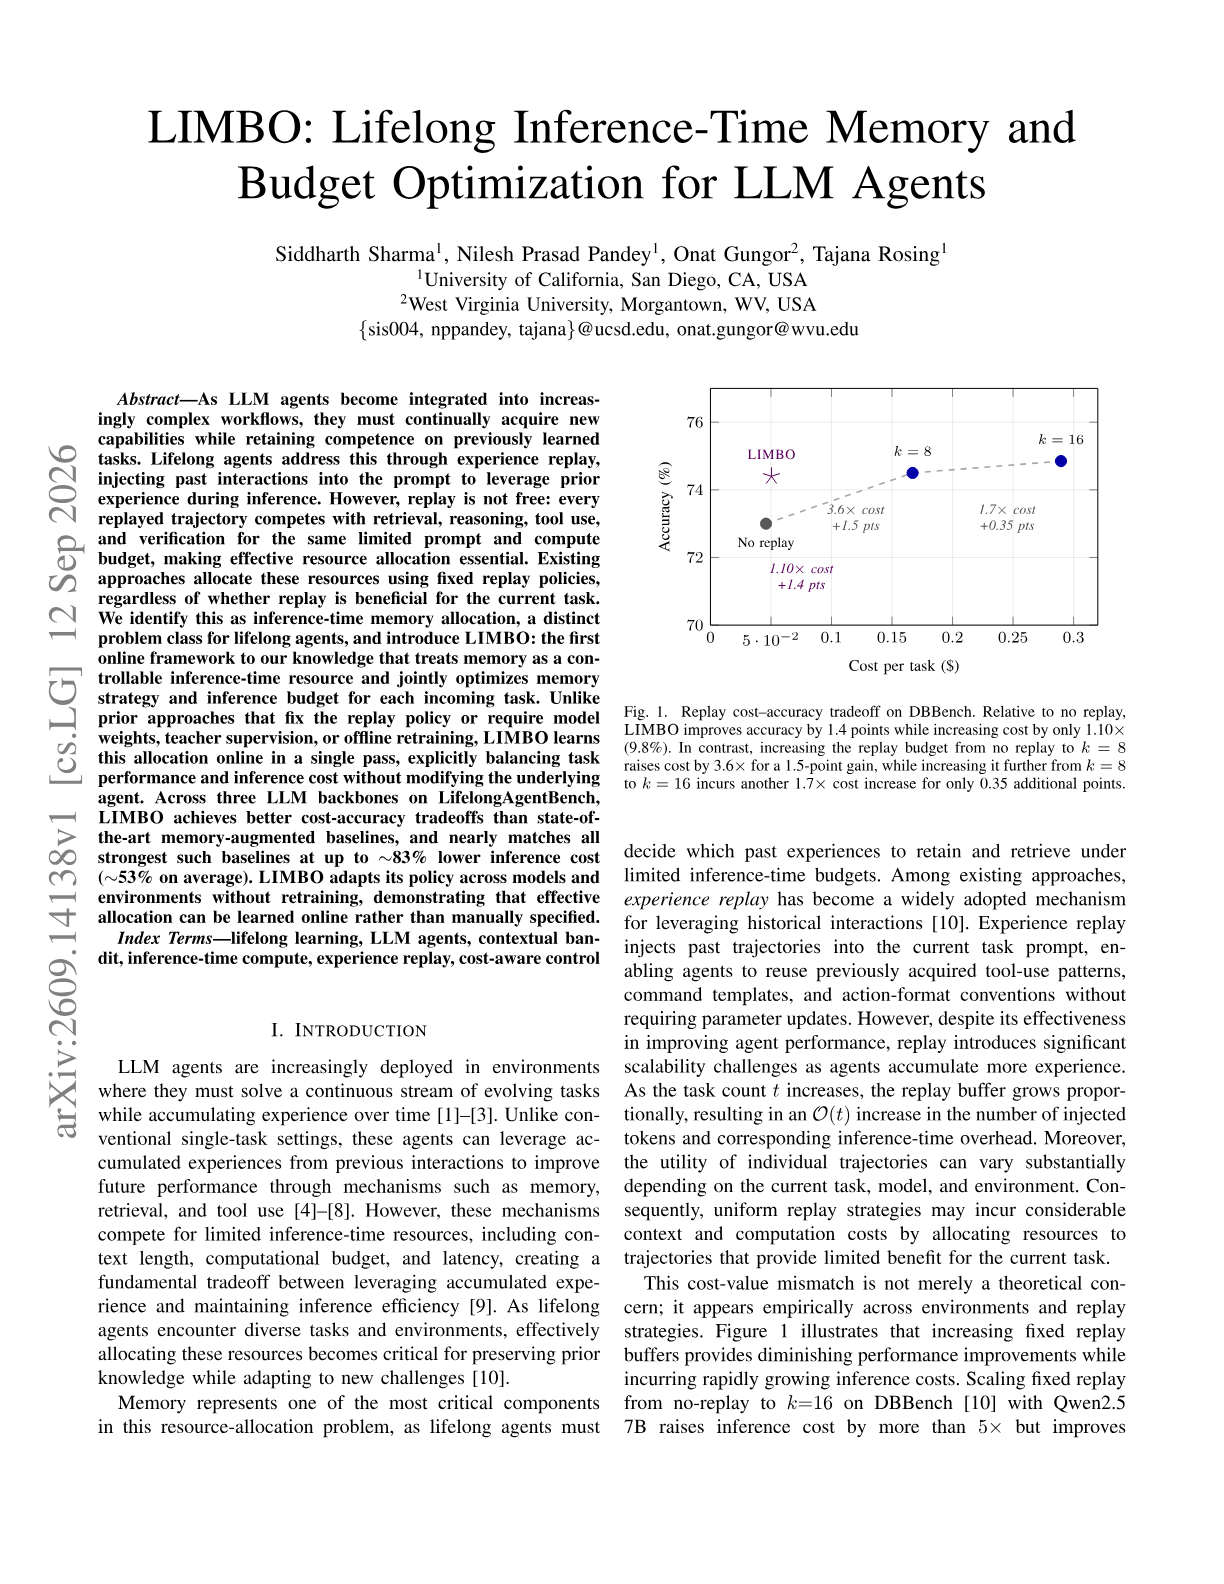
As LLM agents become integrated into increasingly complex workflows, they must continually acquire new capabilities while retaining competence on previously learned tasks. Lifelong agents address this through experience replay, injecting past interactions into the prompt to leverage prior experience during inference. However, replay is not free: every replayed trajectory competes with retrieval, reasoning, tool use, and verification for the same limited prompt and compute budget, making effective resource allocation essential. Existing approaches allocate these resources using fixed replay policies, regardless of whether replay is beneficial for the current task. We identify this as inference-time memory allocation, a distinct problem class for lifelong agents, and introduce LIMBO: the first online framework to our knowledge that treats memory as a controllable inference-time resource and jointly optimizes memory strategy and inference budget for each incoming task. Unlike prior approaches that fix the replay policy or require model weights, teacher supervision, or offline retraining, LIMBO learns this allocation online in a single pass, explicitly balancing task performance and inference cost without modifying the underlying agent. Across three LLM backbones on LifelongAgentBench, LIMBO achieves better cost-accuracy tradeoffs than state-of-the-art memory-augmented baselines and nearly matches all strongest such baselines at up to ~83% lower inference cost (~53% on average). LIMBO adapts its policy across models and environments without retraining, demonstrating that effective allocation can be learned online rather than manually specified.