Long-context LLMs Struggle with Long In-Context Learning
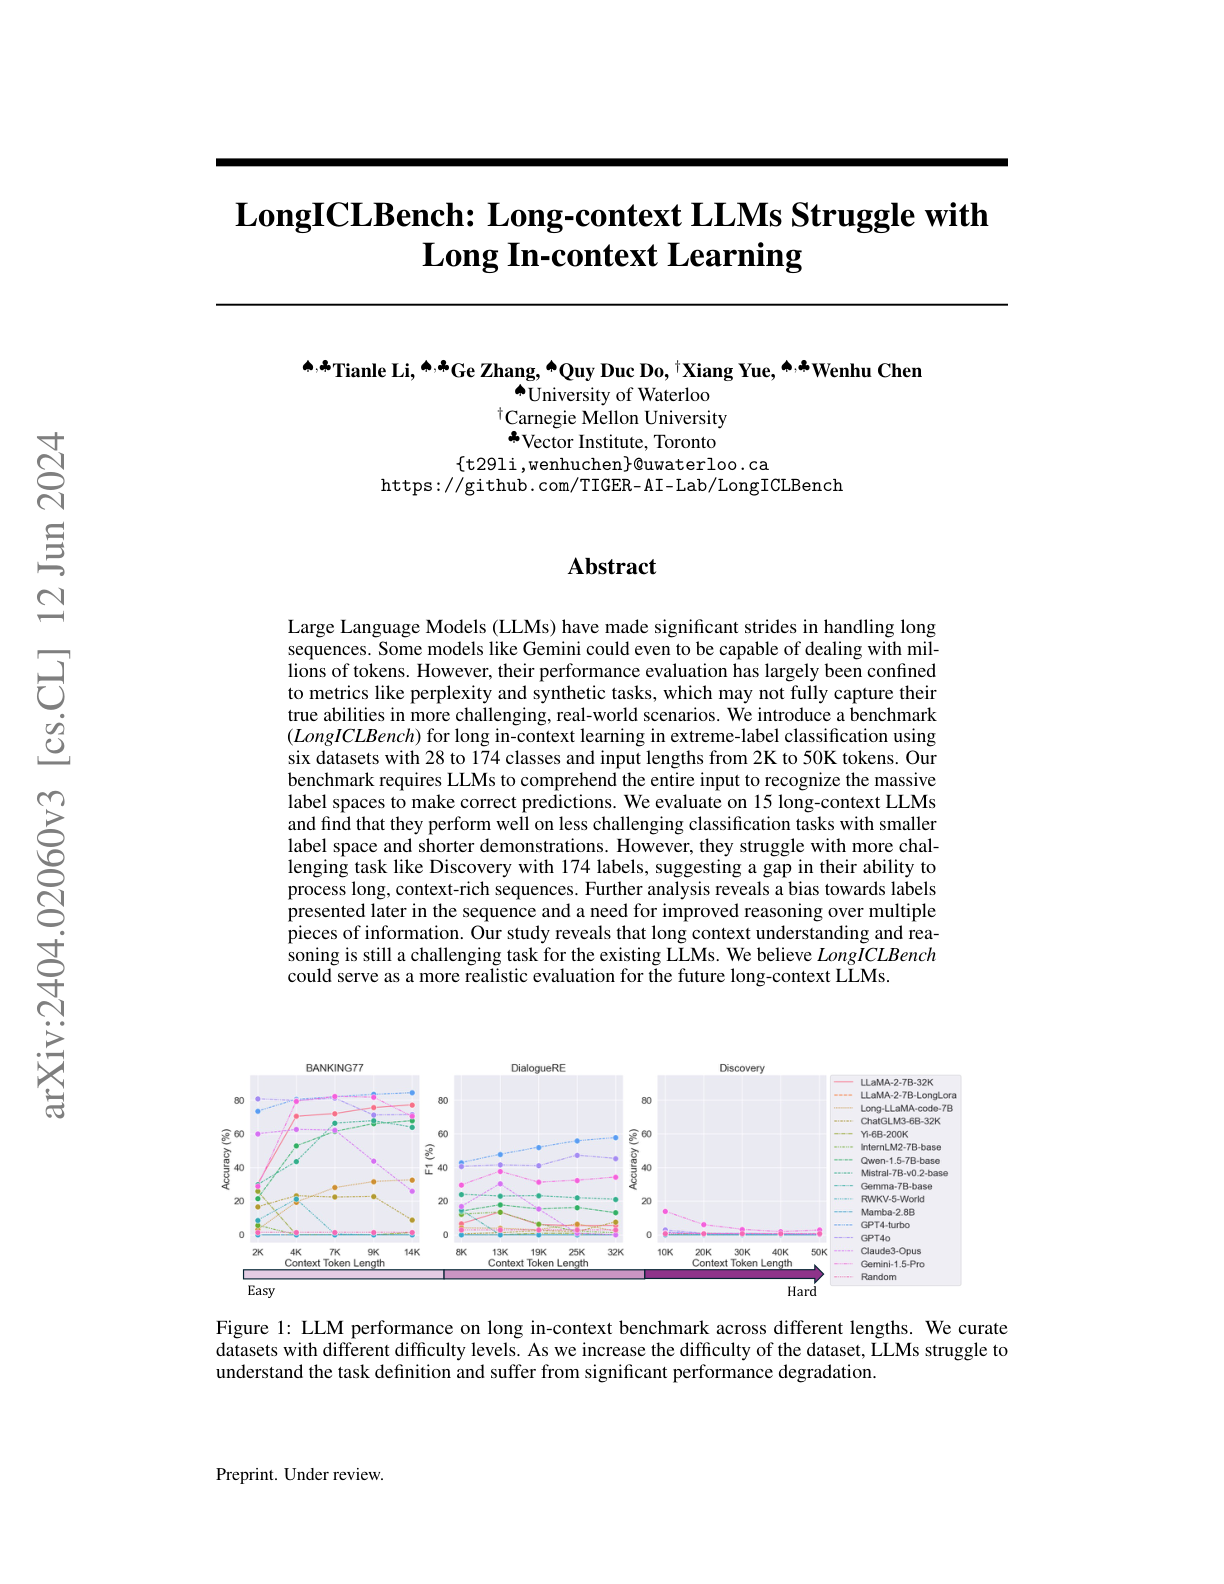
LongICLBench stress-tests 13 long-context LLMs on extreme-label classification with up to 174 classes and 50K-token prompts, exposing sharp quality cliffs beyond 20K tokens.
Ask this paper
Benchmark design: Tasks cover 28-174 label classes packed into 2K-50K token contexts, requiring models to integrate many demonstrations rather than retrieve a single fact.
Short-to-mid context OK: Most models perform adequately under ~20K tokens, suggesting that advertised long-context windows can at least hold instructions and examples.
Sharp degradation past 20K: On the hardest task (Discovery, 174 labels) every open model collapses, and all but GPT-4 dip dramatically as context grows beyond 20K tokens.
Position bias: Models over-predict labels that appear later in the prompt, revealing that long-context ICL fails both on reasoning across examples and on treating positions symmetrically.