SWE-Agent
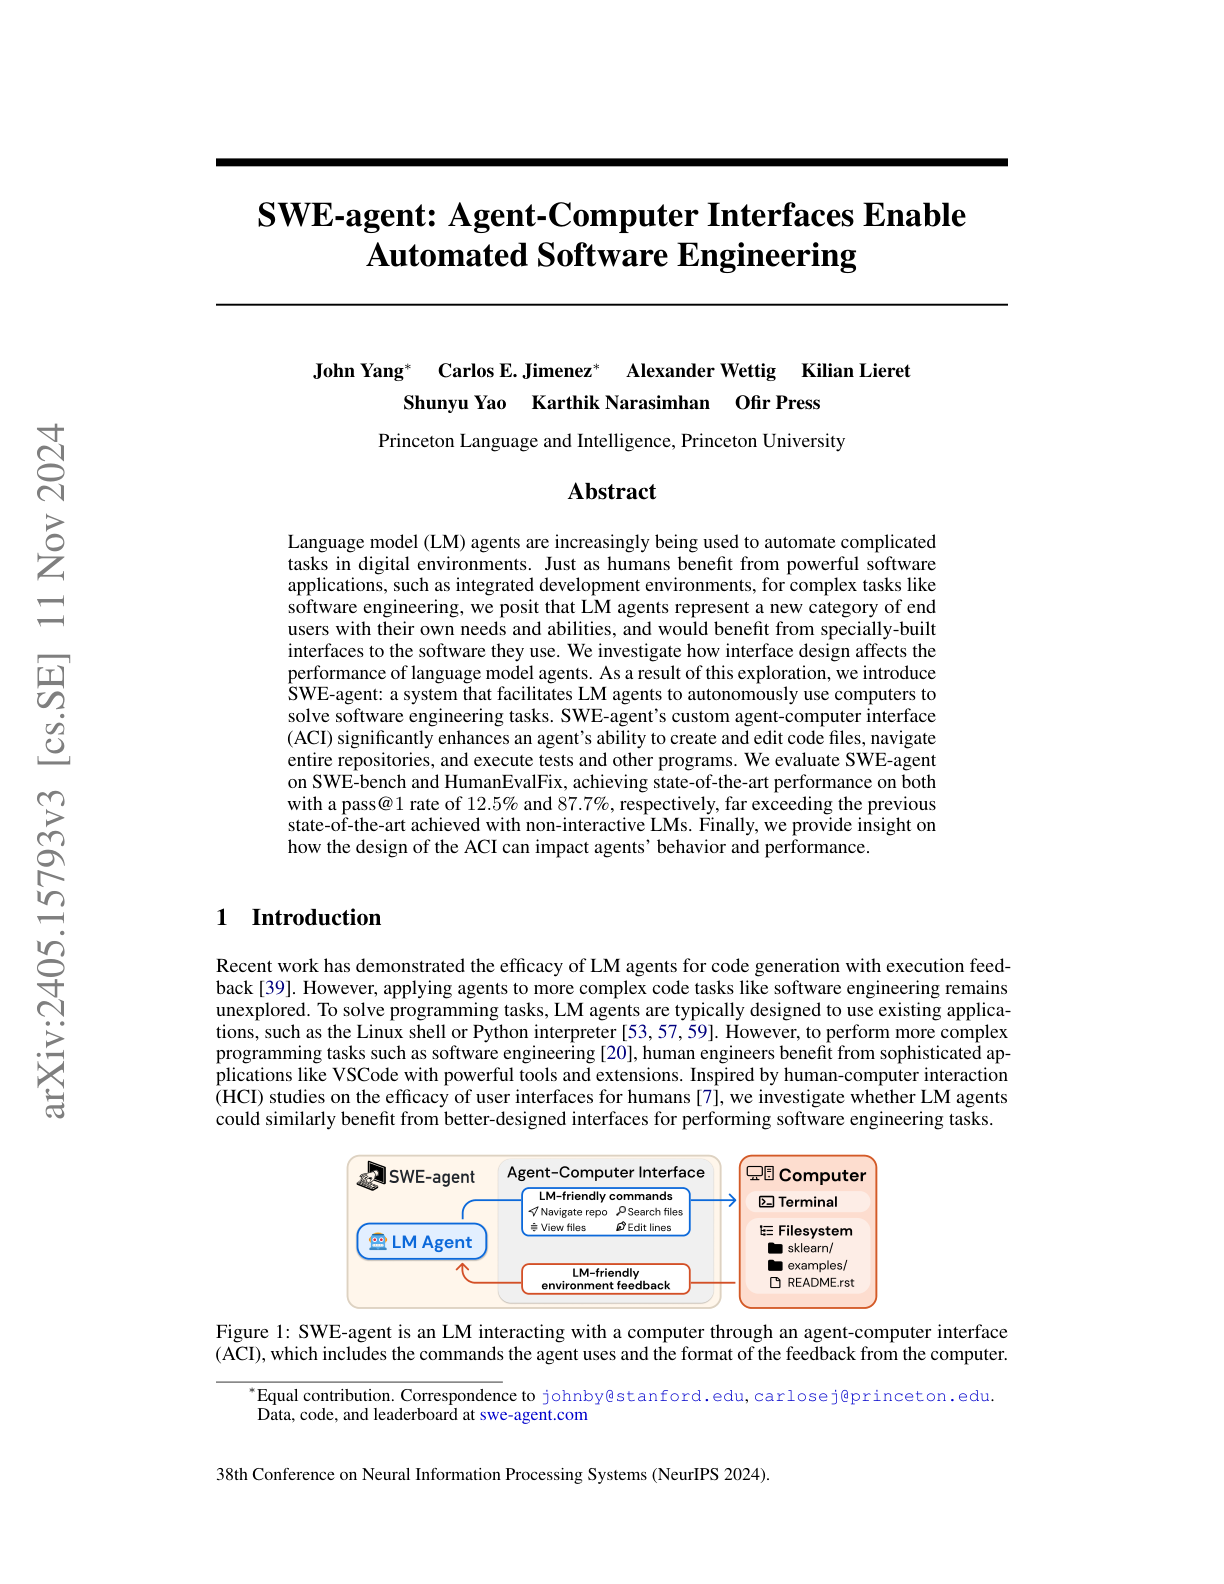
Princeton's SWE-agent pairs a language model with a custom agent-computer interface (ACI) that exposes file navigation, editing, and test execution as discrete tools, letting the agent autonomously resolve real GitHub issues.
Ask this paper
Agent-computer interface: The ACI replaces raw shell access with carefully designed commands (scrolling viewers, structured editors, test runners) that make it easier for an LLM to plan multi-step code changes.
SWE-bench results: SWE-agent resolves 12.29% of SWE-bench issues end-to-end on the full test set, matching Devin's reported accuracy while being fully open-source.
HumanEvalFix: On HumanEvalFix the same agent reaches an 87.7% pass rate, showing the ACI generalizes beyond large-repo bug fixing to smaller self-contained tasks.
Interface-over-model lesson: The gains come primarily from interface design rather than model changes, reinforcing that agent capability depends heavily on how tools are exposed to the LLM.