LongLoRA
First page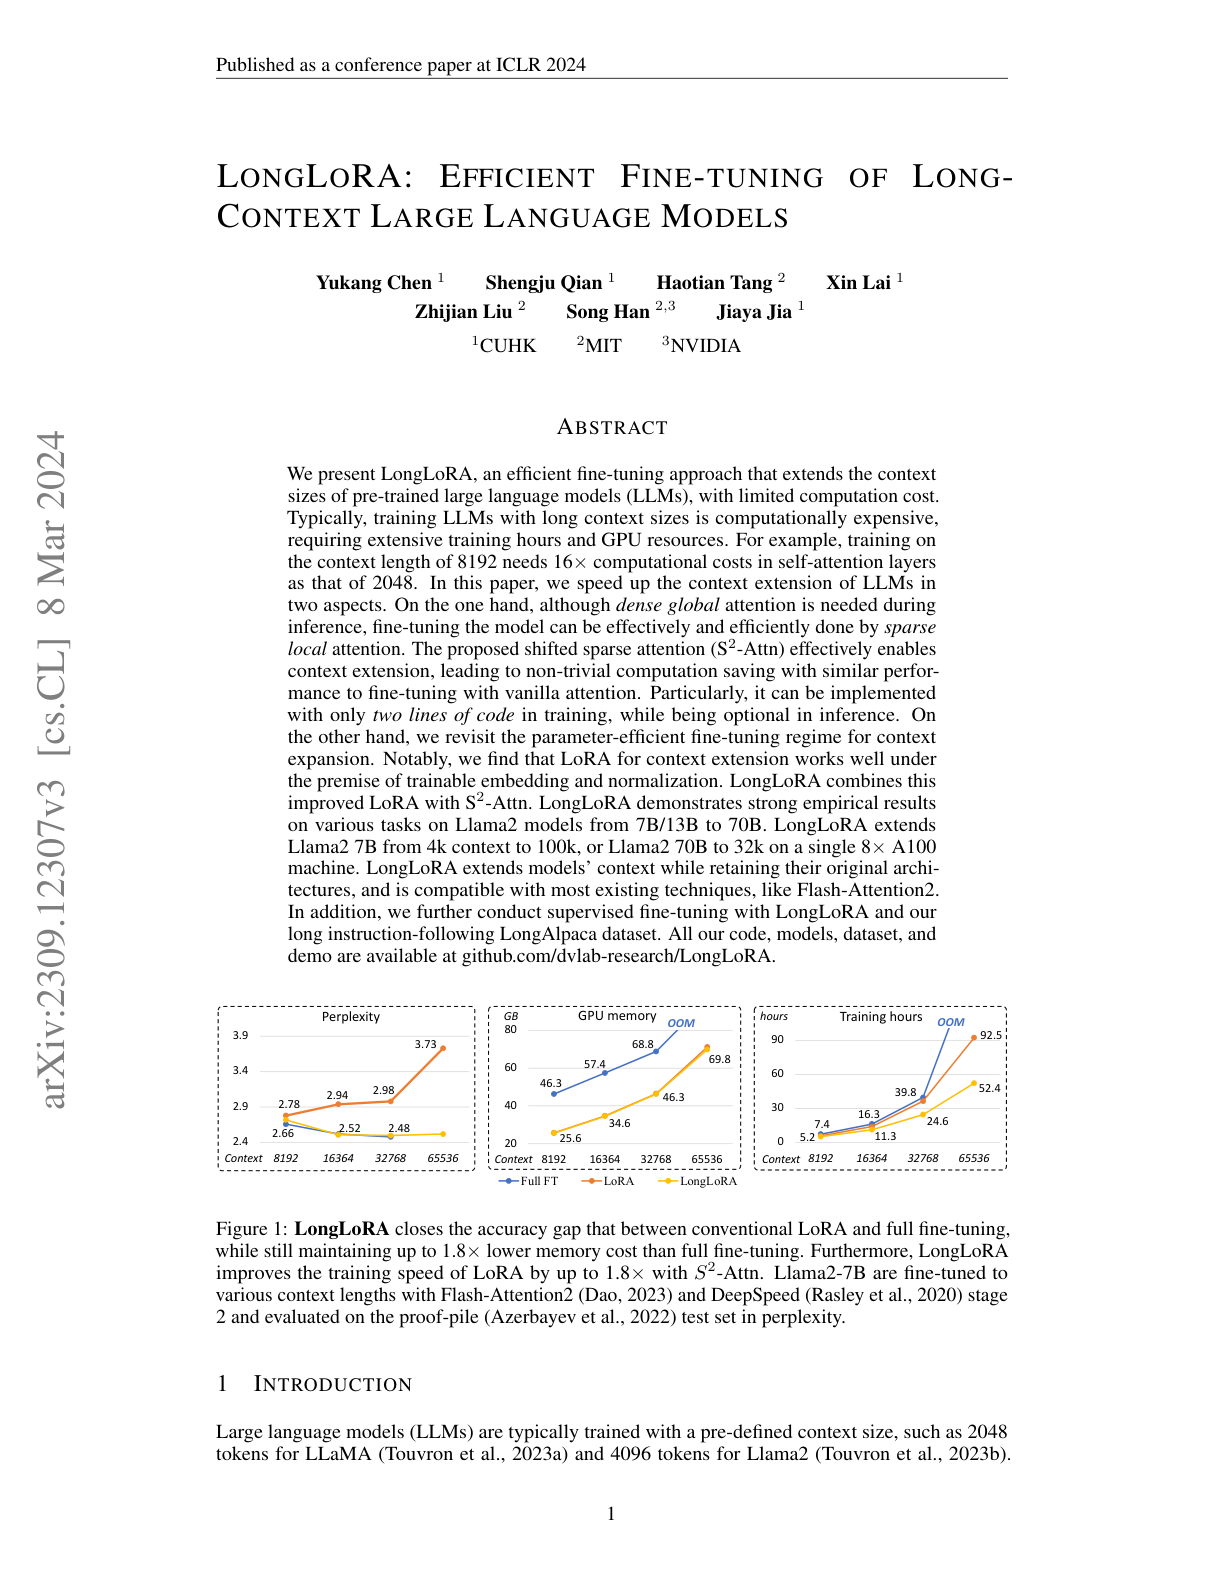
Paper summary
An efficient LoRA-based fine-tuning recipe for extending LLM context windows without expensive full fine-tuning.
Ask this paper
01
Shift short attention: Uses "shift short attention" during training, a pattern-shifted sparse approximation that mimics full attention while cutting cost.
02
LoRA-compatible: Works with standard LoRA, making it compatible with the existing parameter-efficient fine-tuning ecosystem.
03
Lower GPU cost: Dramatically reduces GPU memory and training time compared to full fine-tuning for context extension.
04
No accuracy compromise: Achieves comparable accuracy to full fine-tuning at extended context lengths, despite using a much cheaper approximation.