Min-K% Prob (Detecting Pretraining Data)
First page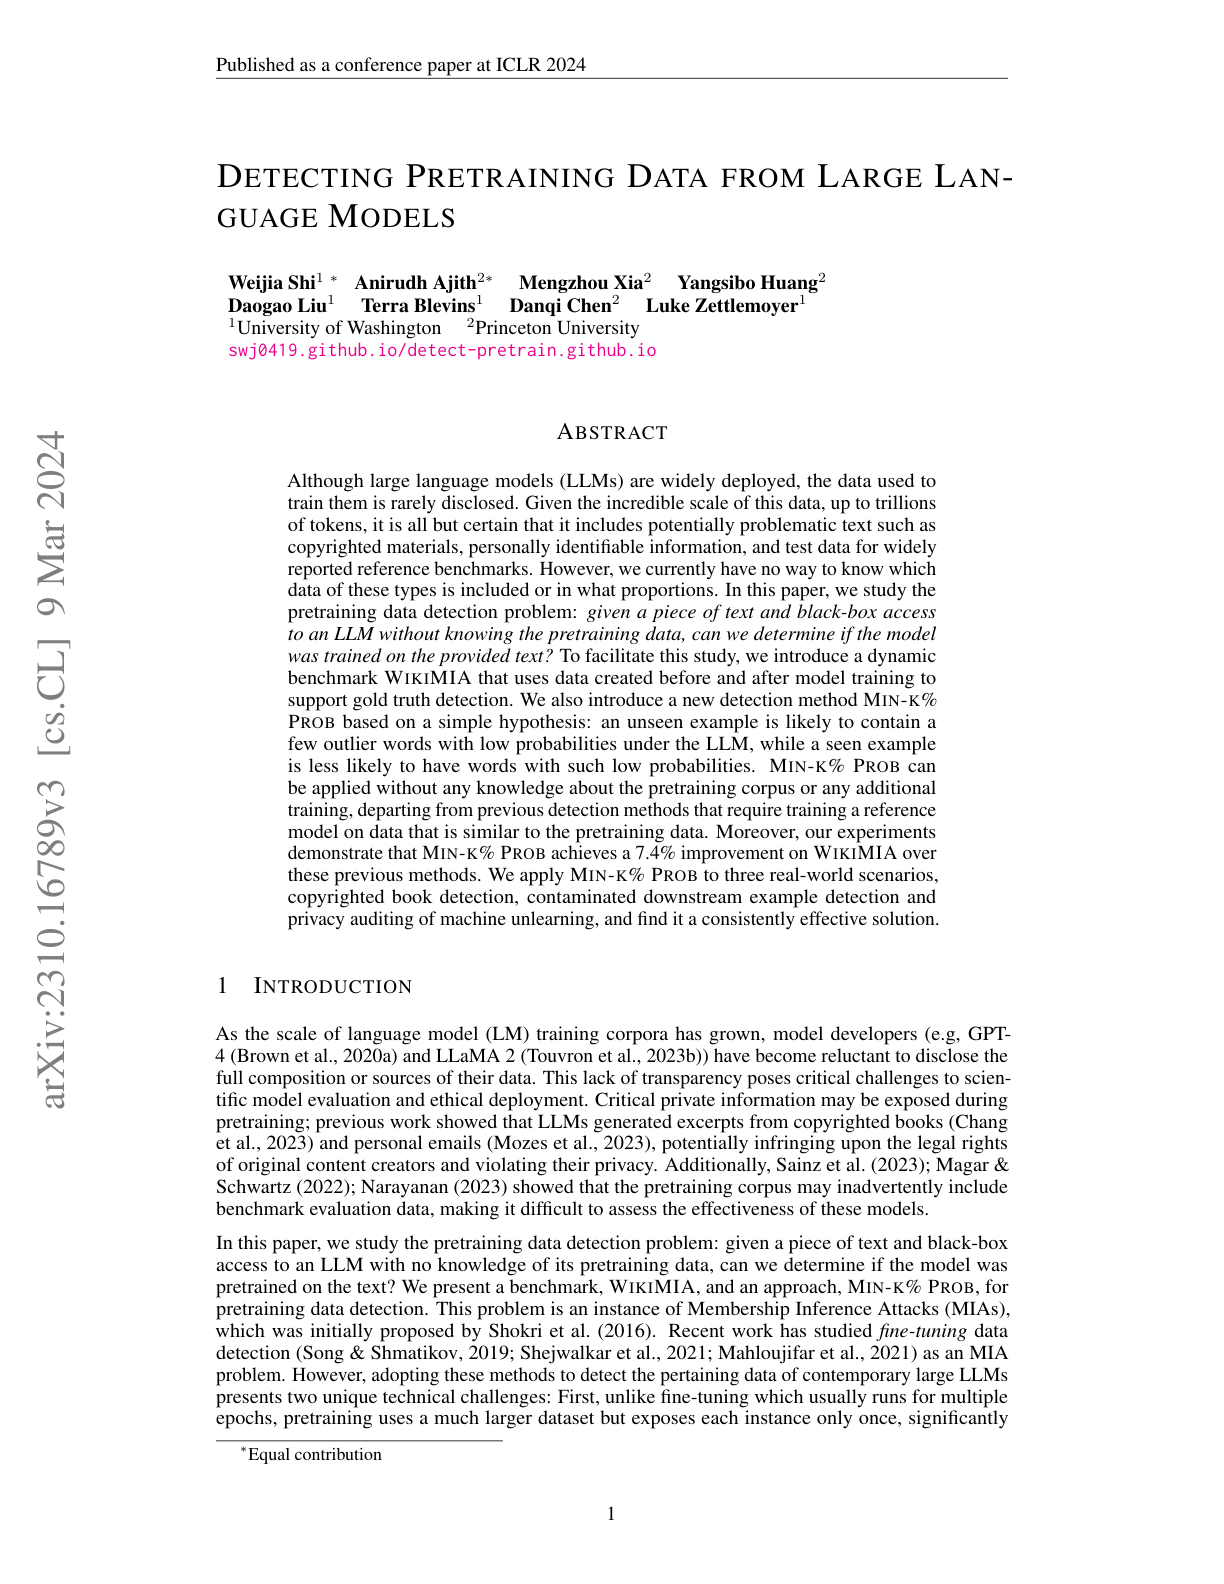
Paper summary
Proposes Min-K% Prob as an effective detection method for determining whether specific text was in an LLM's pretraining data.
Ask this paper
01
Method: Computes the average log-probability of the K% least-likely tokens in a text; memorized text has higher log-probabilities on these tokens than unseen text.
02
Black-box detection: Works on API-accessible models without needing gradients or internal activations, making it broadly applicable.
03
Multiple use cases: Usable for benchmark-contamination detection, privacy auditing of machine unlearning, and copyrighted-text detection in pretraining corpora.
04
Policy implications: Provides a technical tool for the copyright and privacy debates, letting third parties measurably test specific-text inclusion in training data.