Zephyr
First page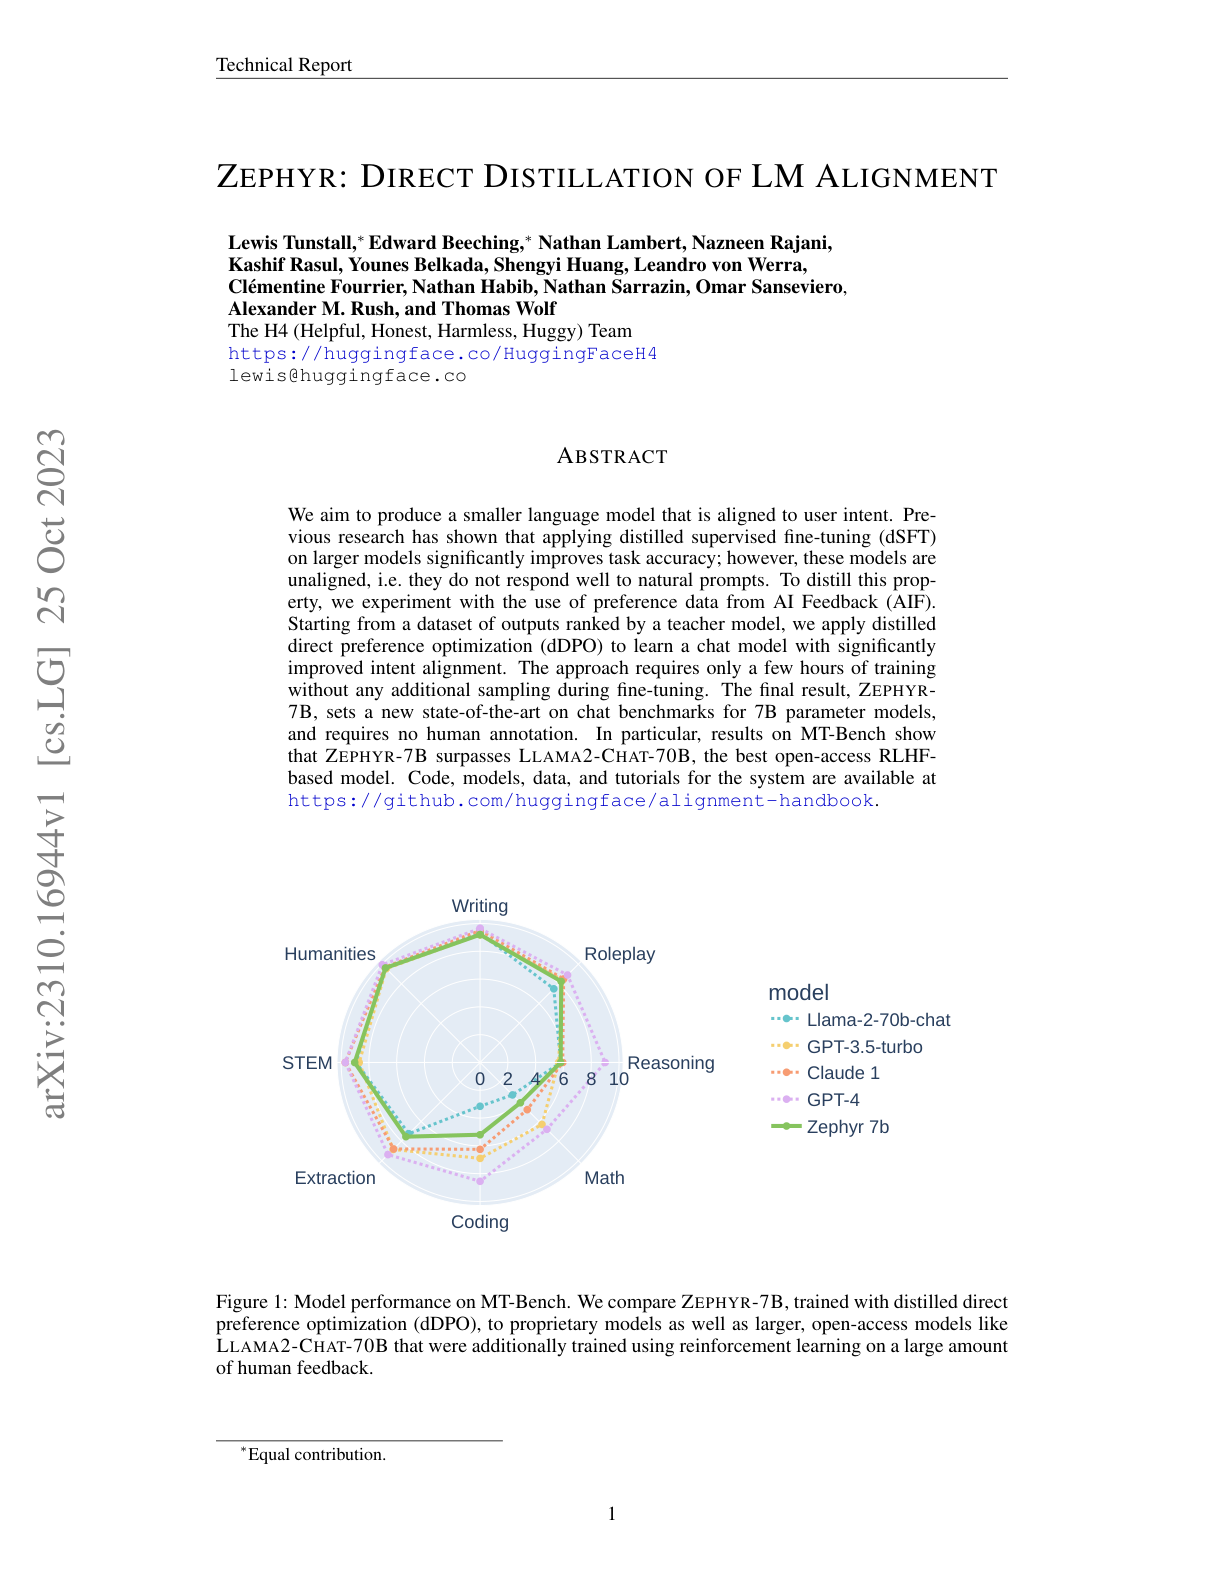
Paper summary
Hugging Face's Zephyr-7B is a 7B parameter LLM whose chat performance rivals much larger chat models aligned with human feedback.
Ask this paper
01
Distilled SFT: Uses distilled supervised fine-tuning on UltraChat-generated instruction data as the task-accuracy foundation.
02
Distilled DPO: Aligns with AI feedback data via Direct Preference Optimization, rather than the expensive human-feedback RLHF pipeline.
03
ChatGPT-level at 7B: Achieves competitive performance with ChatGPT on AlpacaEval and matches 70B chat models aligned with human feedback on several benchmarks.
04
Recipe popularization: Open-sources the distilled-DPO recipe, which became a widely adopted template for small, strong open chat models.