Mini-Gemini
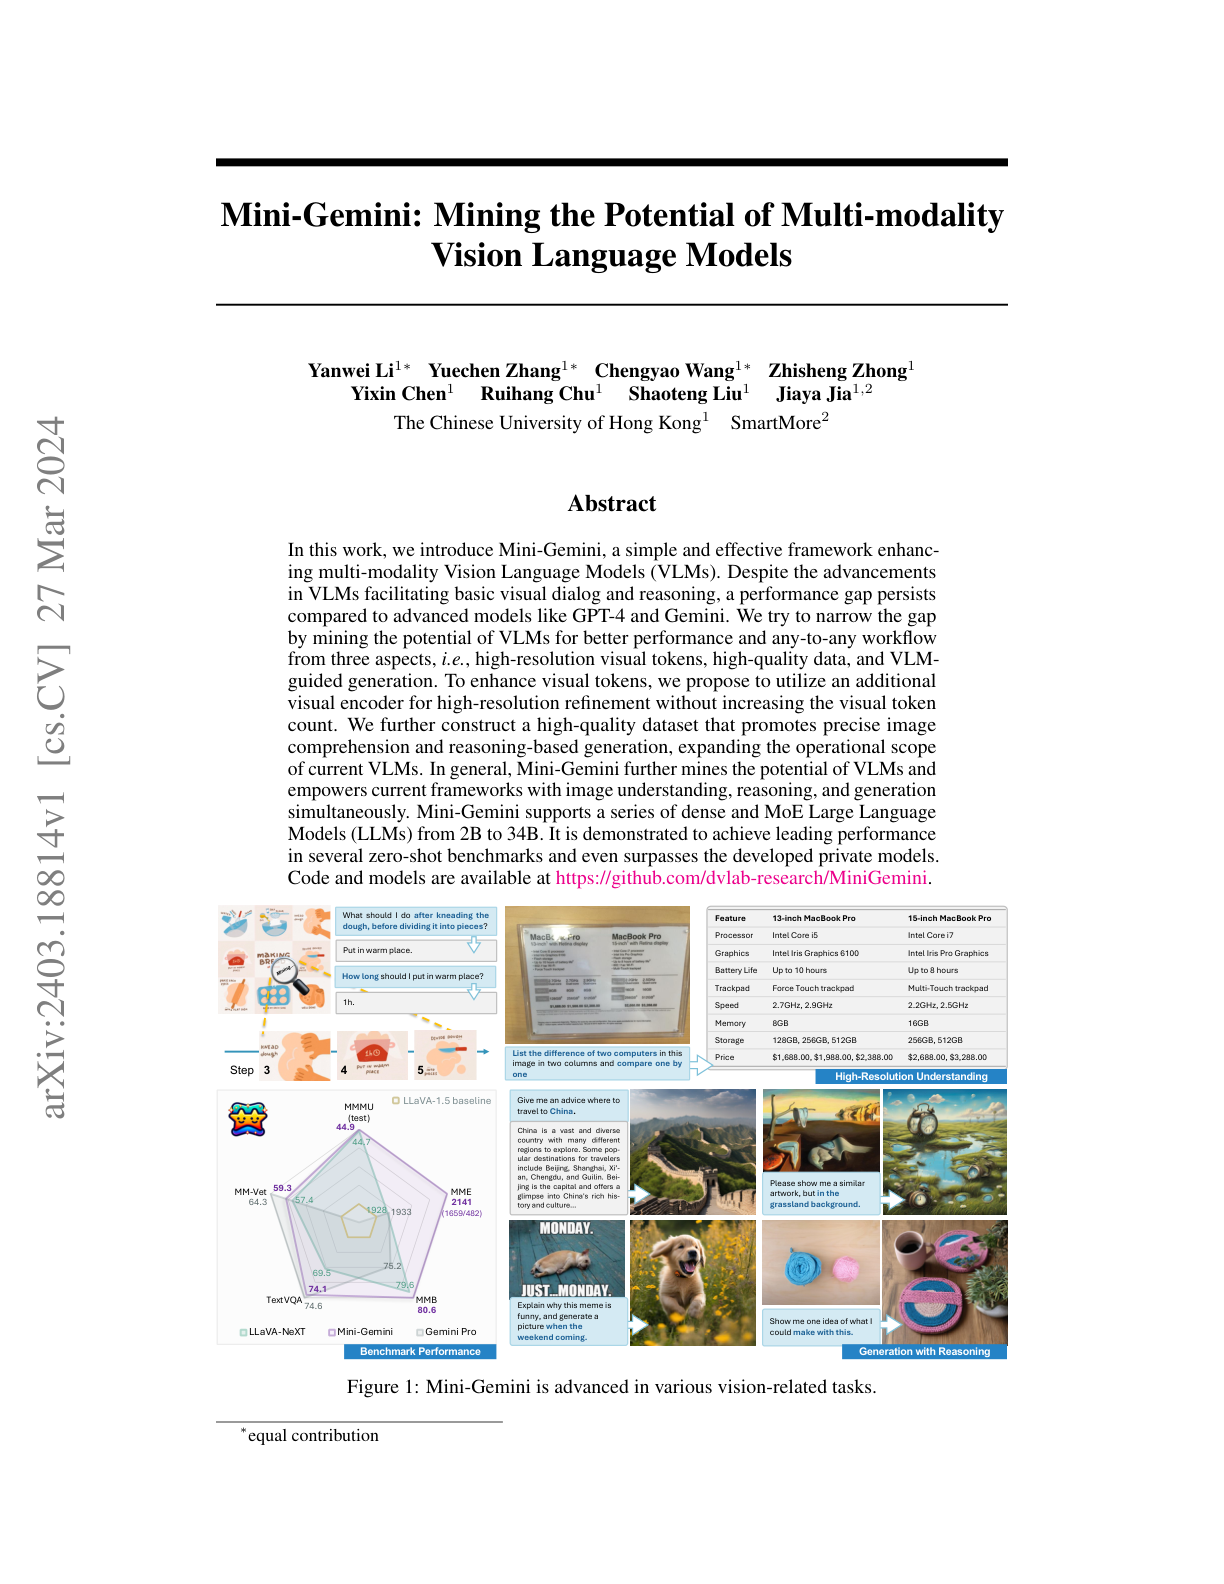
Mini-Gemini enhances vision-language models by adding a second high-resolution visual encoder that refines details without increasing the number of visual tokens consumed by the LLM.
Ask this paper
Dual-encoder design: A primary low-res encoder produces the visual tokens fed to the LLM while a high-res encoder provides patch-level features used to refine those tokens via attention.
Token count stays constant: Because refinement happens in feature space rather than by adding tokens, inference cost stays comparable to the base VLM even as visual fidelity improves.
Works across scales: The framework supports LLM backbones from 2B to 34B parameters and pairs image understanding with VLM-guided image generation in a single stack.
Benchmark leadership: Achieves leading zero-shot scores across several vision-language benchmarks, with the authors reporting results competitive with or surpassing GPT-4 and Gemini on comparable tasks.