MultiModal-GPT
First page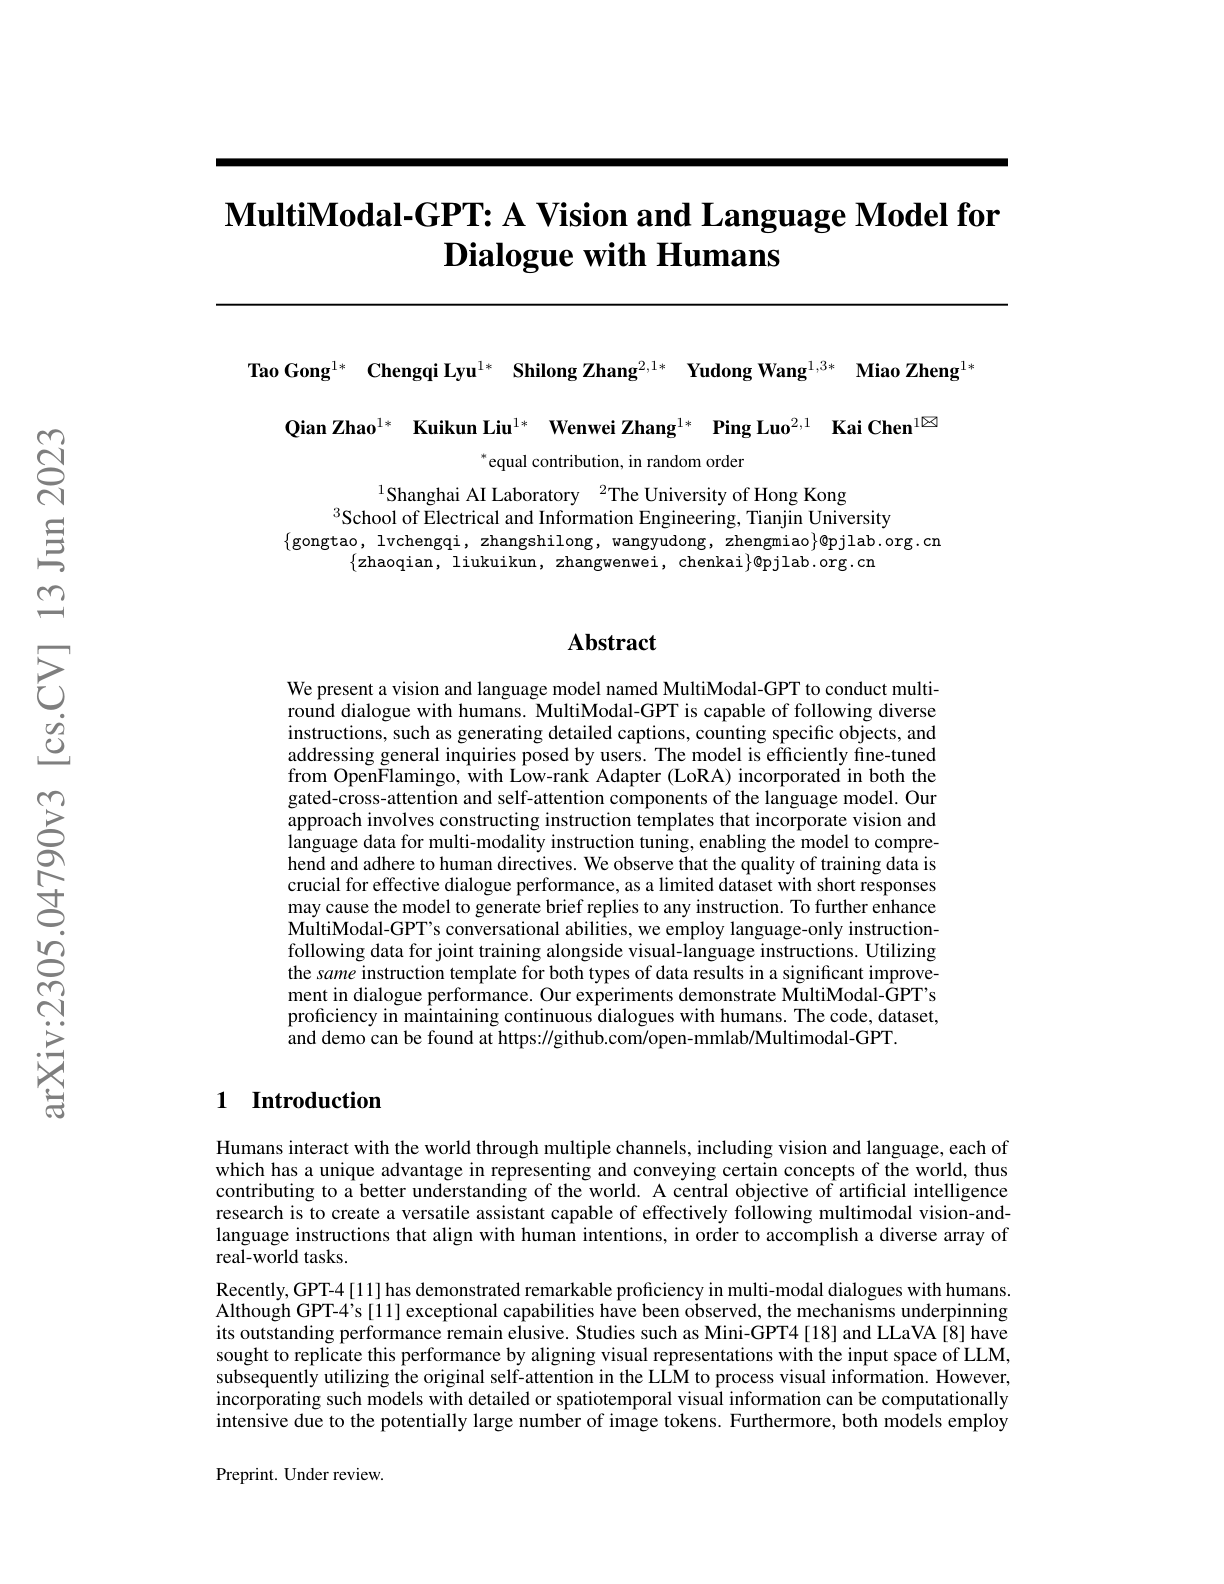
Paper summary
A vision-language model for multi-round dialogue fine-tuned from OpenFlamingo.
Ask this paper
01
LoRA-based extension: Adds LoRA to OpenFlamingo's cross-attention and self-attention for efficient fine-tuning.
02
Multi-round dialog: Specifically designed for multi-turn visual dialog, going beyond single-turn VQA.
03
Open visual chatbot: An early fully-open visual chatbot that users could run locally.
04
VLM dialog research: Informed the trajectory toward modern visual chatbots (LLaVA, Qwen-VL) that dominated open VLM research.