OLMo 2
First page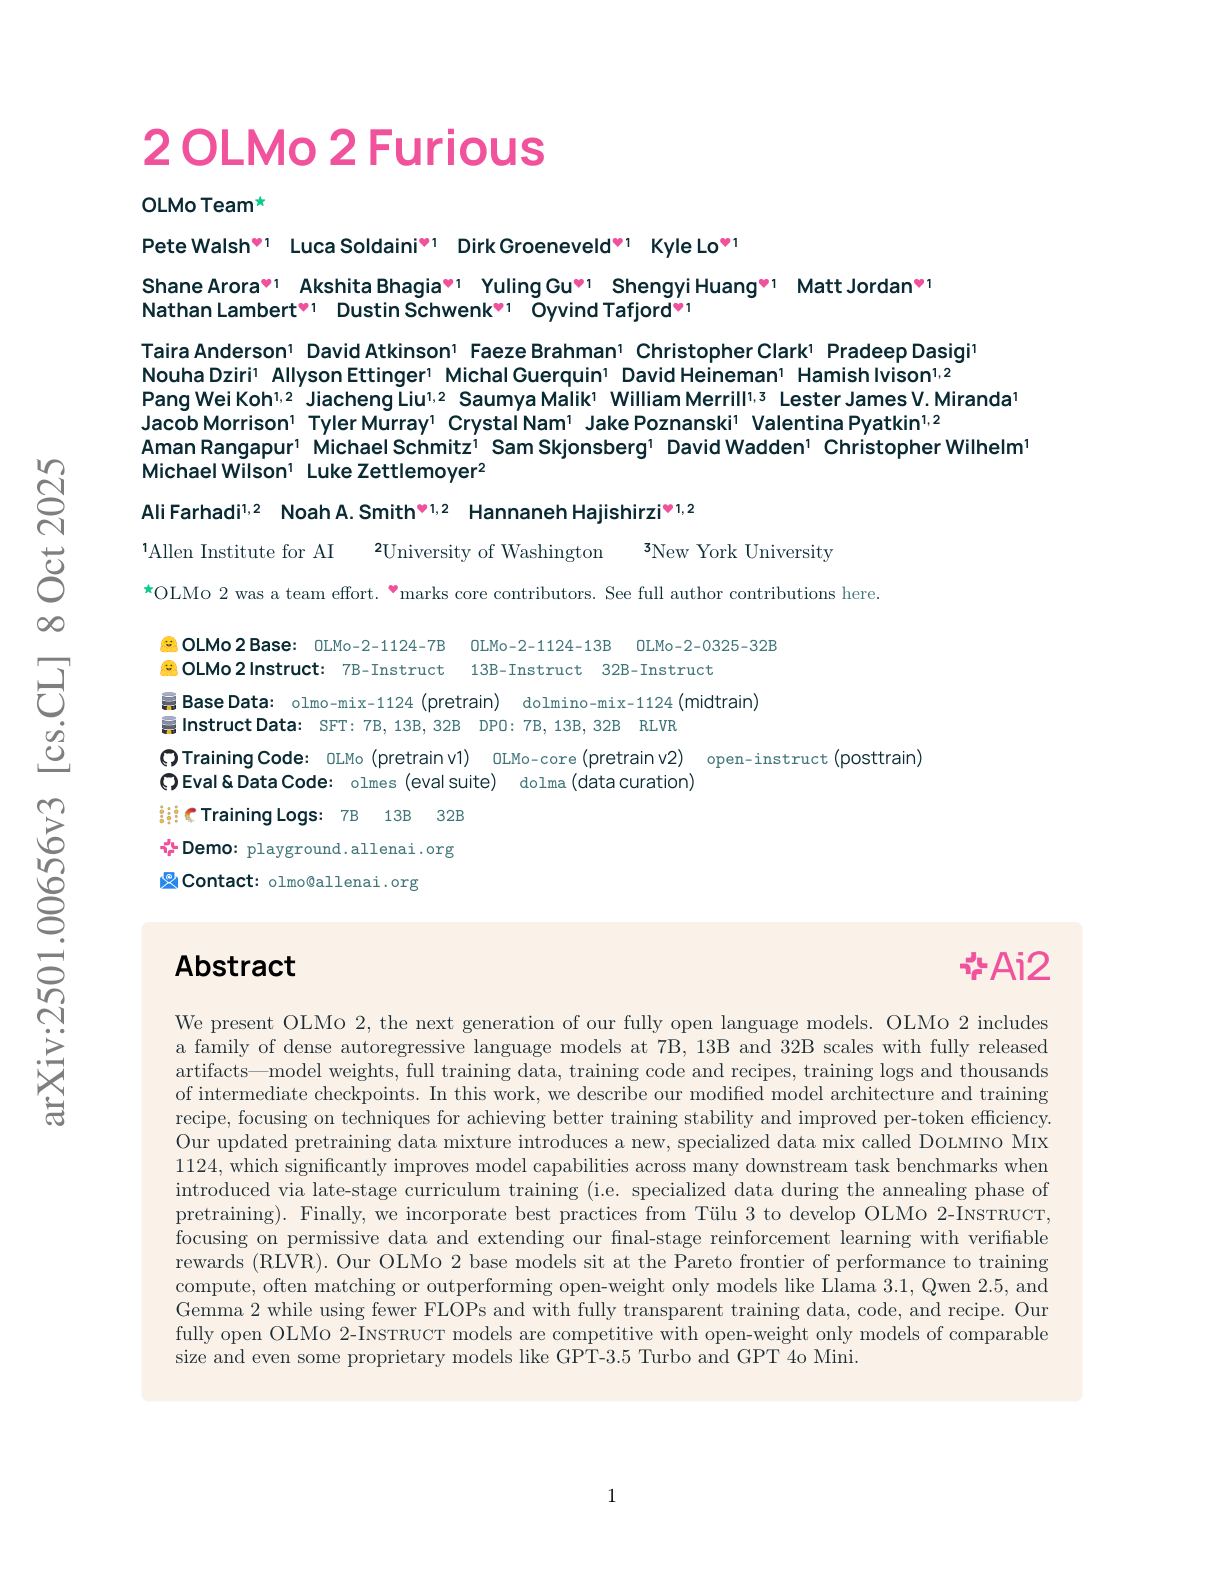
Paper summary
introduces an enhanced architecture, training methods, and a specialized data mixture called Dolmino Mix 1124; the fully transparent model, released at 7B and 13B parameter scales with complete training data and code, matches or outperforms similar open-weight models like Llama 3.1 and Qwen 2.5 while using fewer computational resources, and its instruction-tuned version (OLMo 2-Instruct) remains competitive with comparable models.