On the Overthinking of LLMs
First page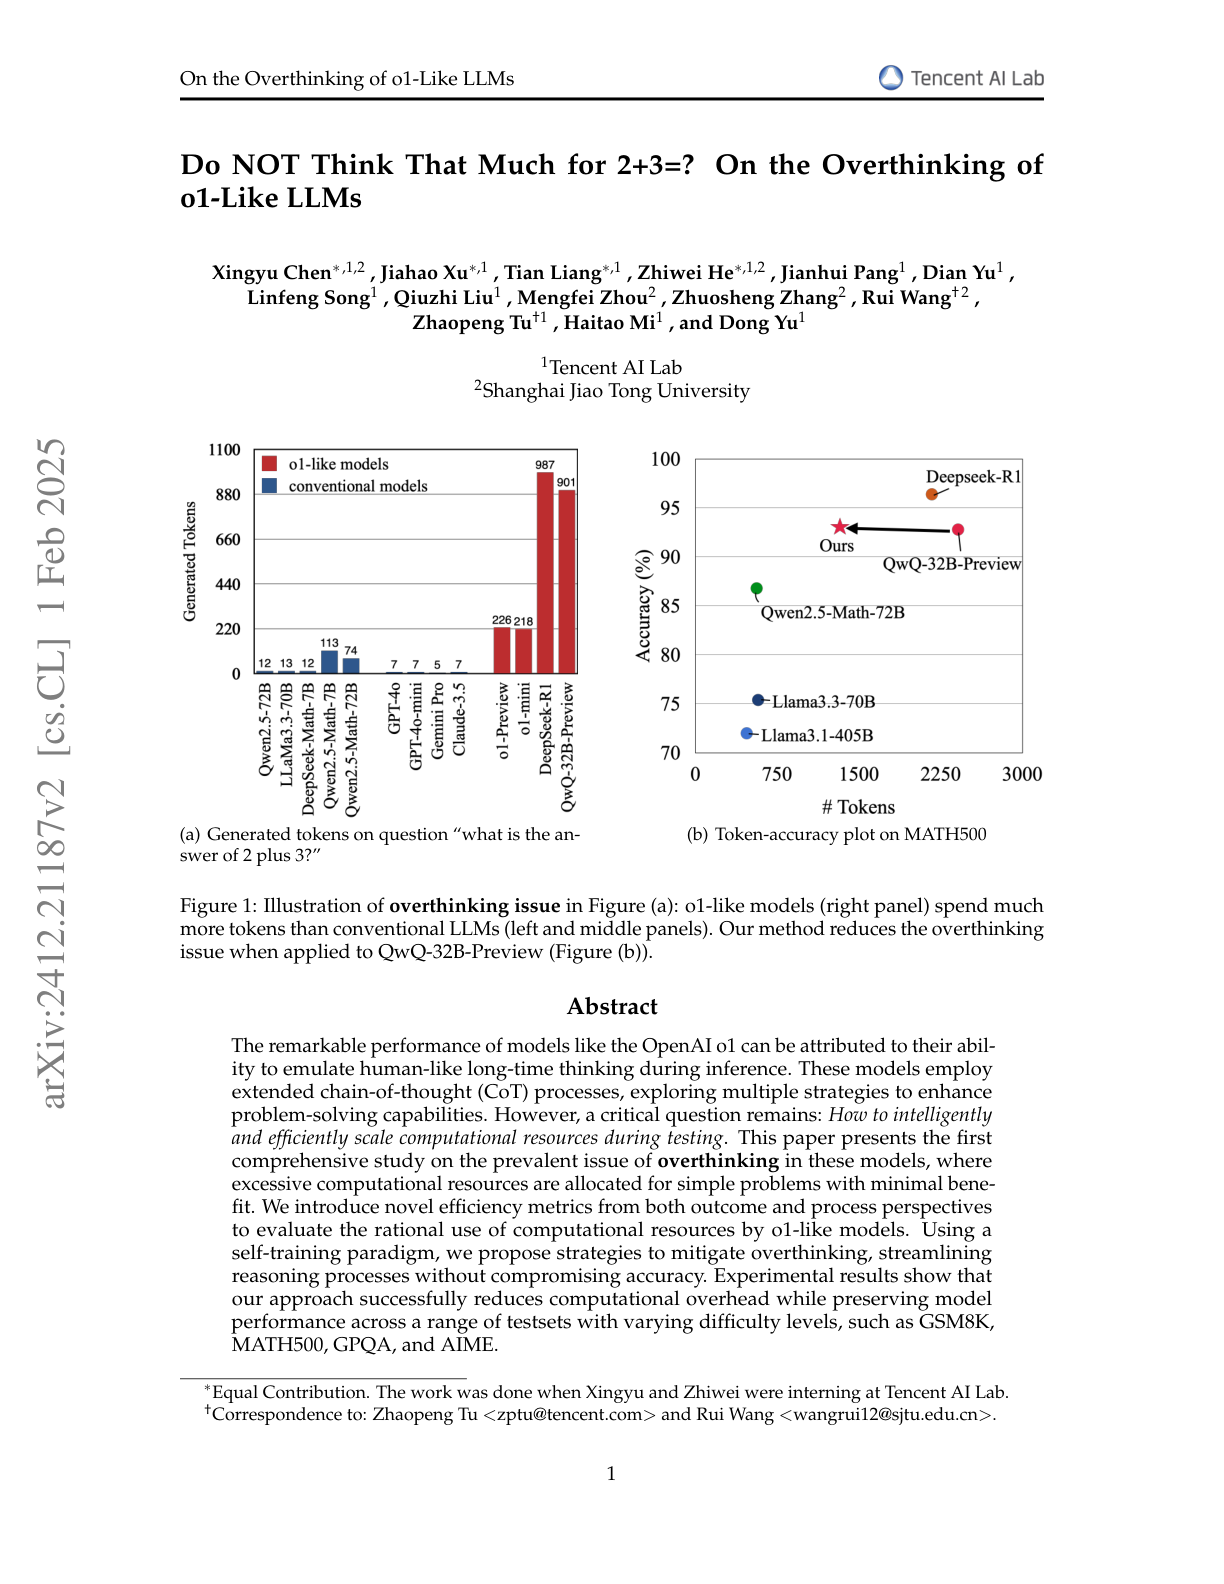
Paper summary
proposes a self-training strategy to mitigate overthinking in o1-like LLMs; it can reduce token output by 48.6% while maintaining accuracy on the widely-used MATH500 test set as applied to QwQ-32B-Preview.