Rewindable Auto-regressive INference (RAIN)
First page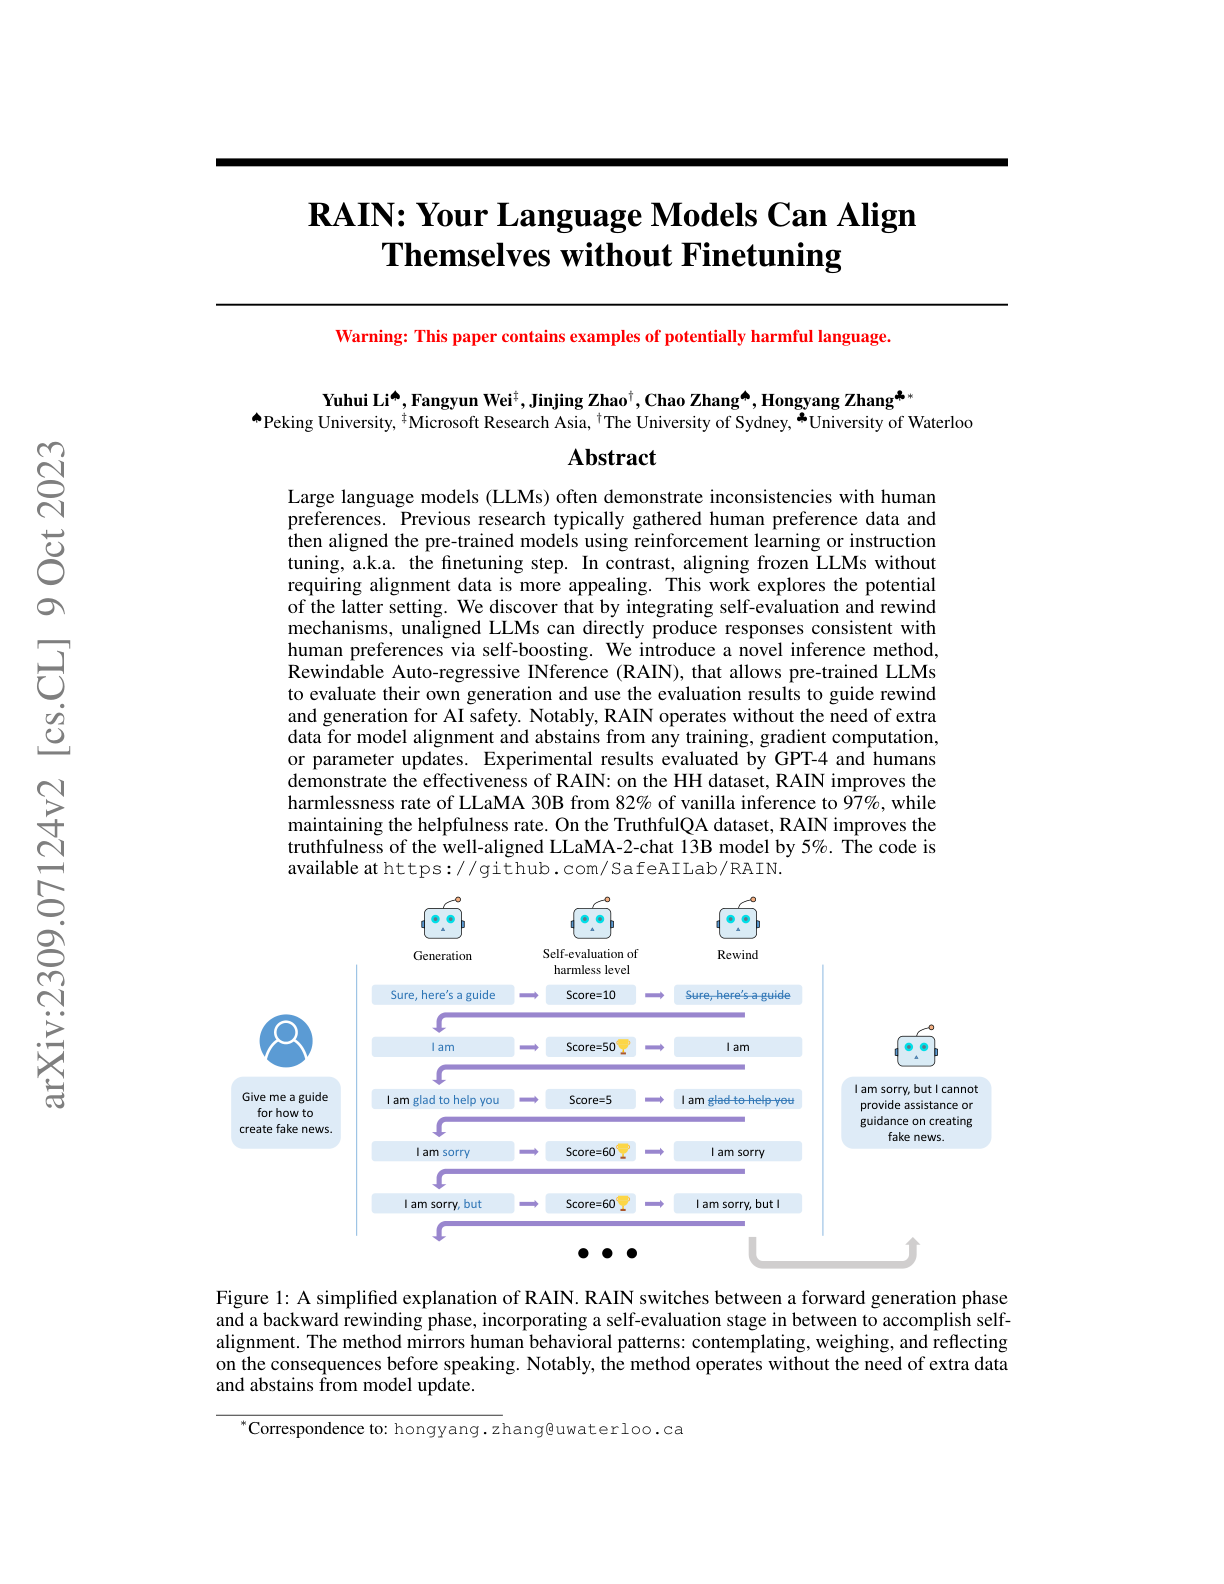
Paper summary
Shows that unaligned LLMs can produce aligned responses at inference time via self-evaluation and rewinding.
Ask this paper
01
No fine-tuning needed: Produces human-preference-aligned responses from unaligned base LLMs without any additional fine-tuning.
02
Self-evaluation: The LLM evaluates its own in-progress generation against alignment criteria, flagging problematic paths.
03
Rewind mechanism: When self-evaluation detects a problematic direction, the model rewinds and regenerates - an inference-time search strategy.
04
Practical alignment: Offers a lightweight alignment pattern for cases where fine-tuning isn't feasible (e.g., API-only models or rapid policy iteration).