RLAIF (Scaling RLHF with AI Feedback)
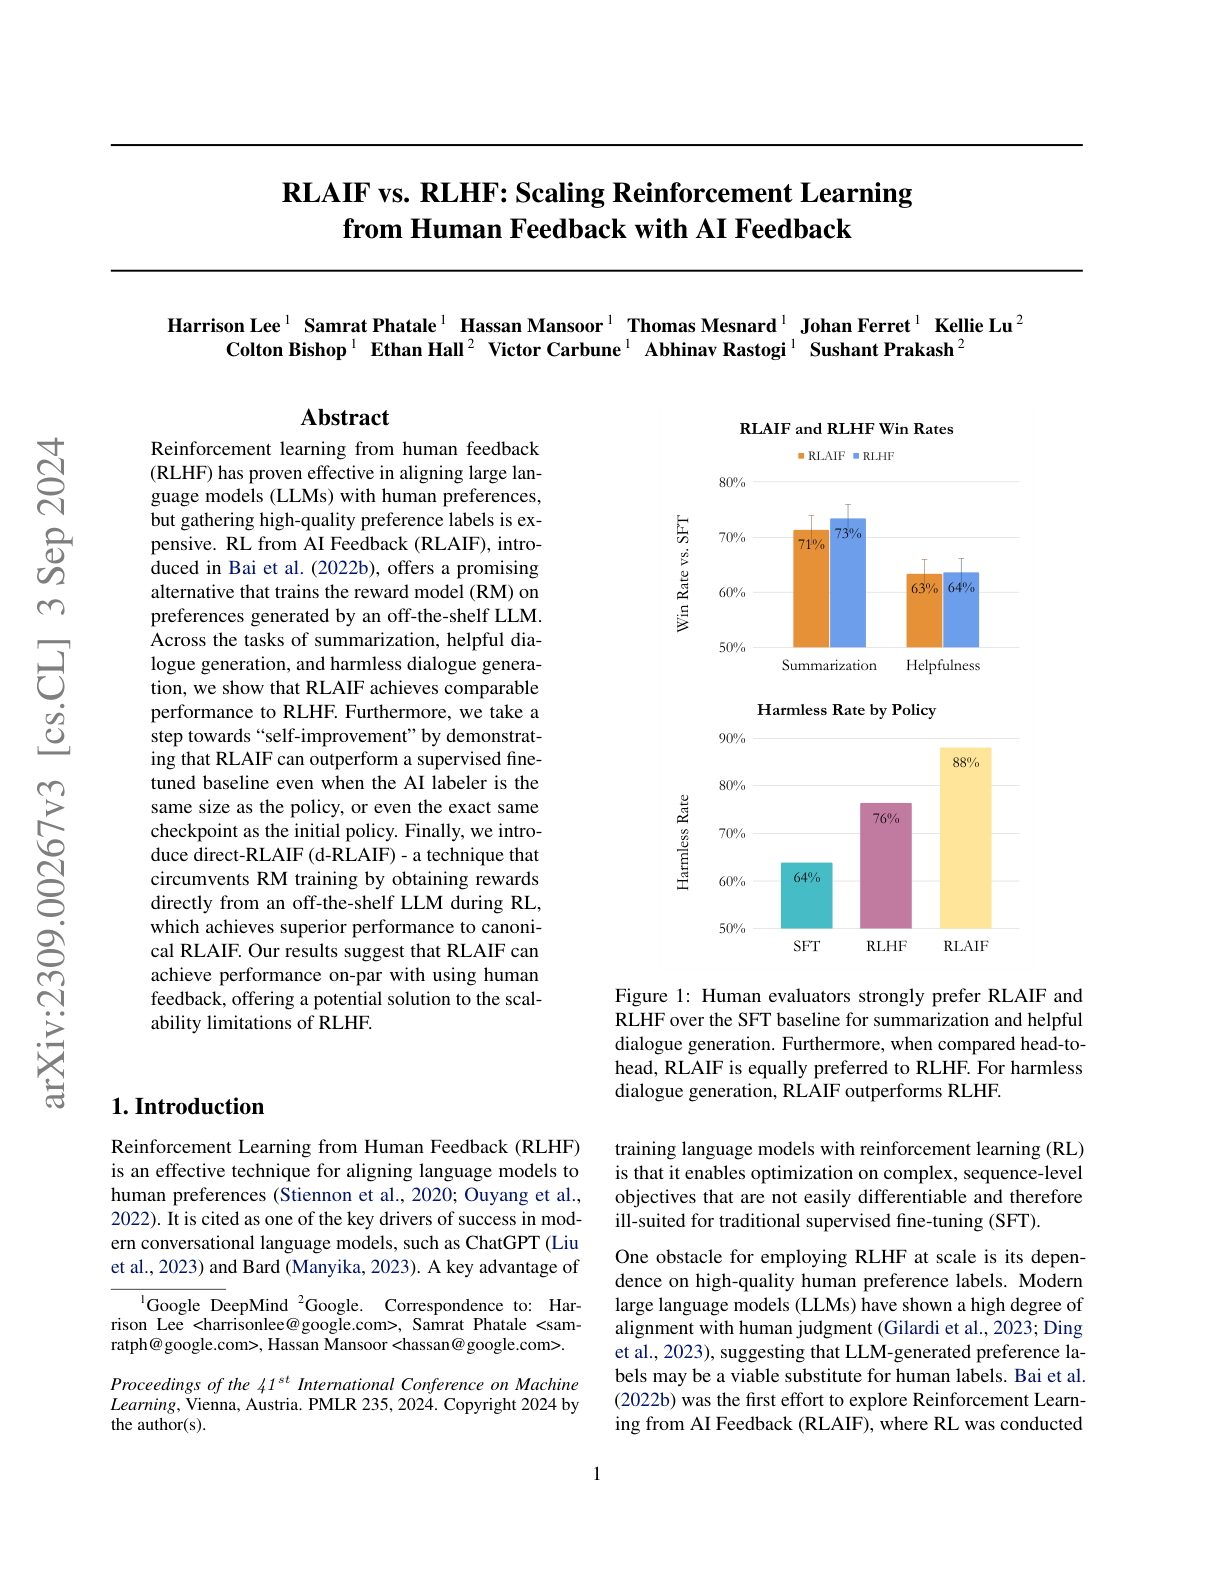
Google compares RLHF with RLAIF (Reinforcement Learning from AI Feedback) to test whether AI preferences can replace human preferences.
Ask this paper
Head-to-head comparison: Directly compares the efficacy of human vs. AI feedback for preference-based alignment, using the same policy optimization pipeline.
~70% preference: On summarization, human evaluators prefer both RLAIF and RLHF outputs over the baseline SFT model in roughly 70% of cases - statistical parity.
Scaling studies: Reports optimal settings for AI-feedback generation, including prompt design, chain-of-thought, and label-combining strategies.
Cost-reduction implication: Suggests RLAIF can substitute for RLHF for many alignment use cases, dramatically reducing the human-labeling cost of alignment.