Scaling Transformer to 1 Billion Tokens (LongNet)
First page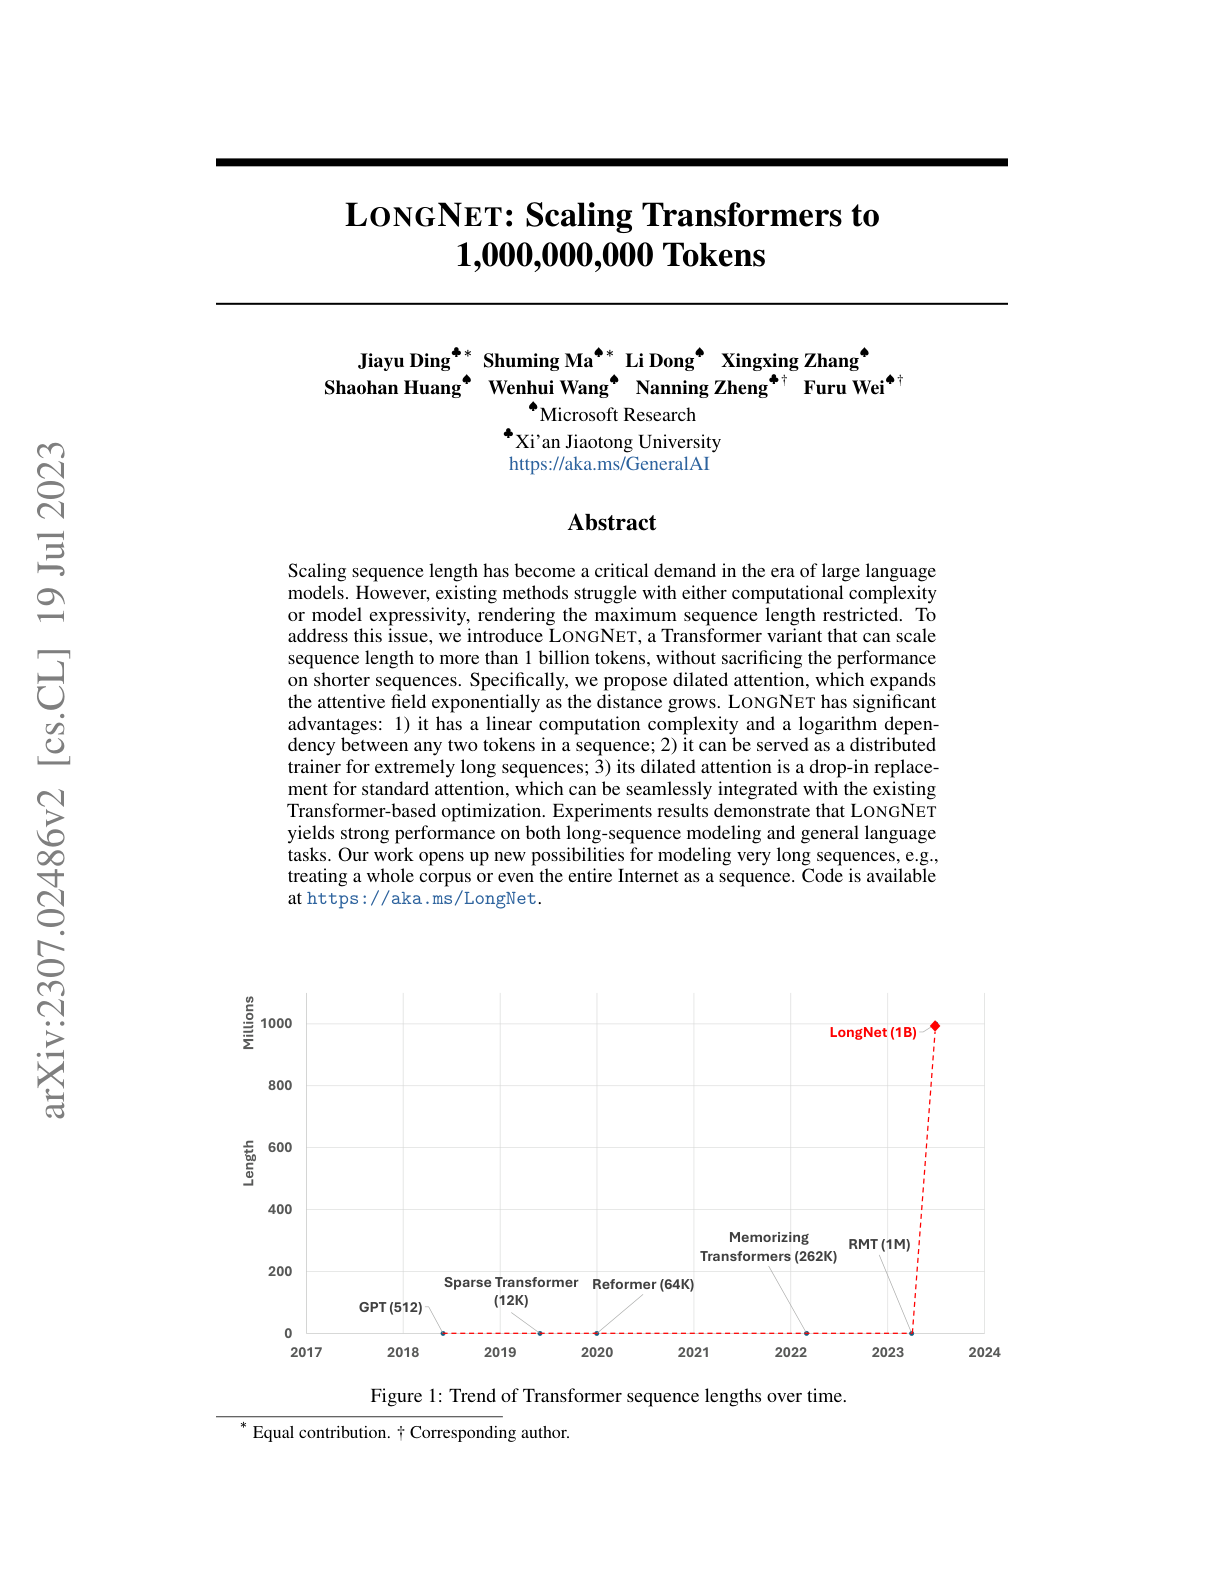
Paper summary
Microsoft's Transformer variant scaling sequence length past 1B tokens.
Ask this paper
01
Dilated attention: Introduces dilated attention that exponentially grows the attention field, enabling linear complexity in sequence length.
02
No short-sequence loss: Achieves extreme long-context scaling with no degradation on shorter sequences.
03
1B token demo: Demonstrates viability at the 1-billion token context scale - an order of magnitude beyond anything previously attempted.
04
Long-context frontier: Pushed the frontier of what's theoretically possible for ultra-long-context Transformers, even though production models stayed in the hundreds-of-thousands-of-tokens range.