State-Externalizing Harnesses
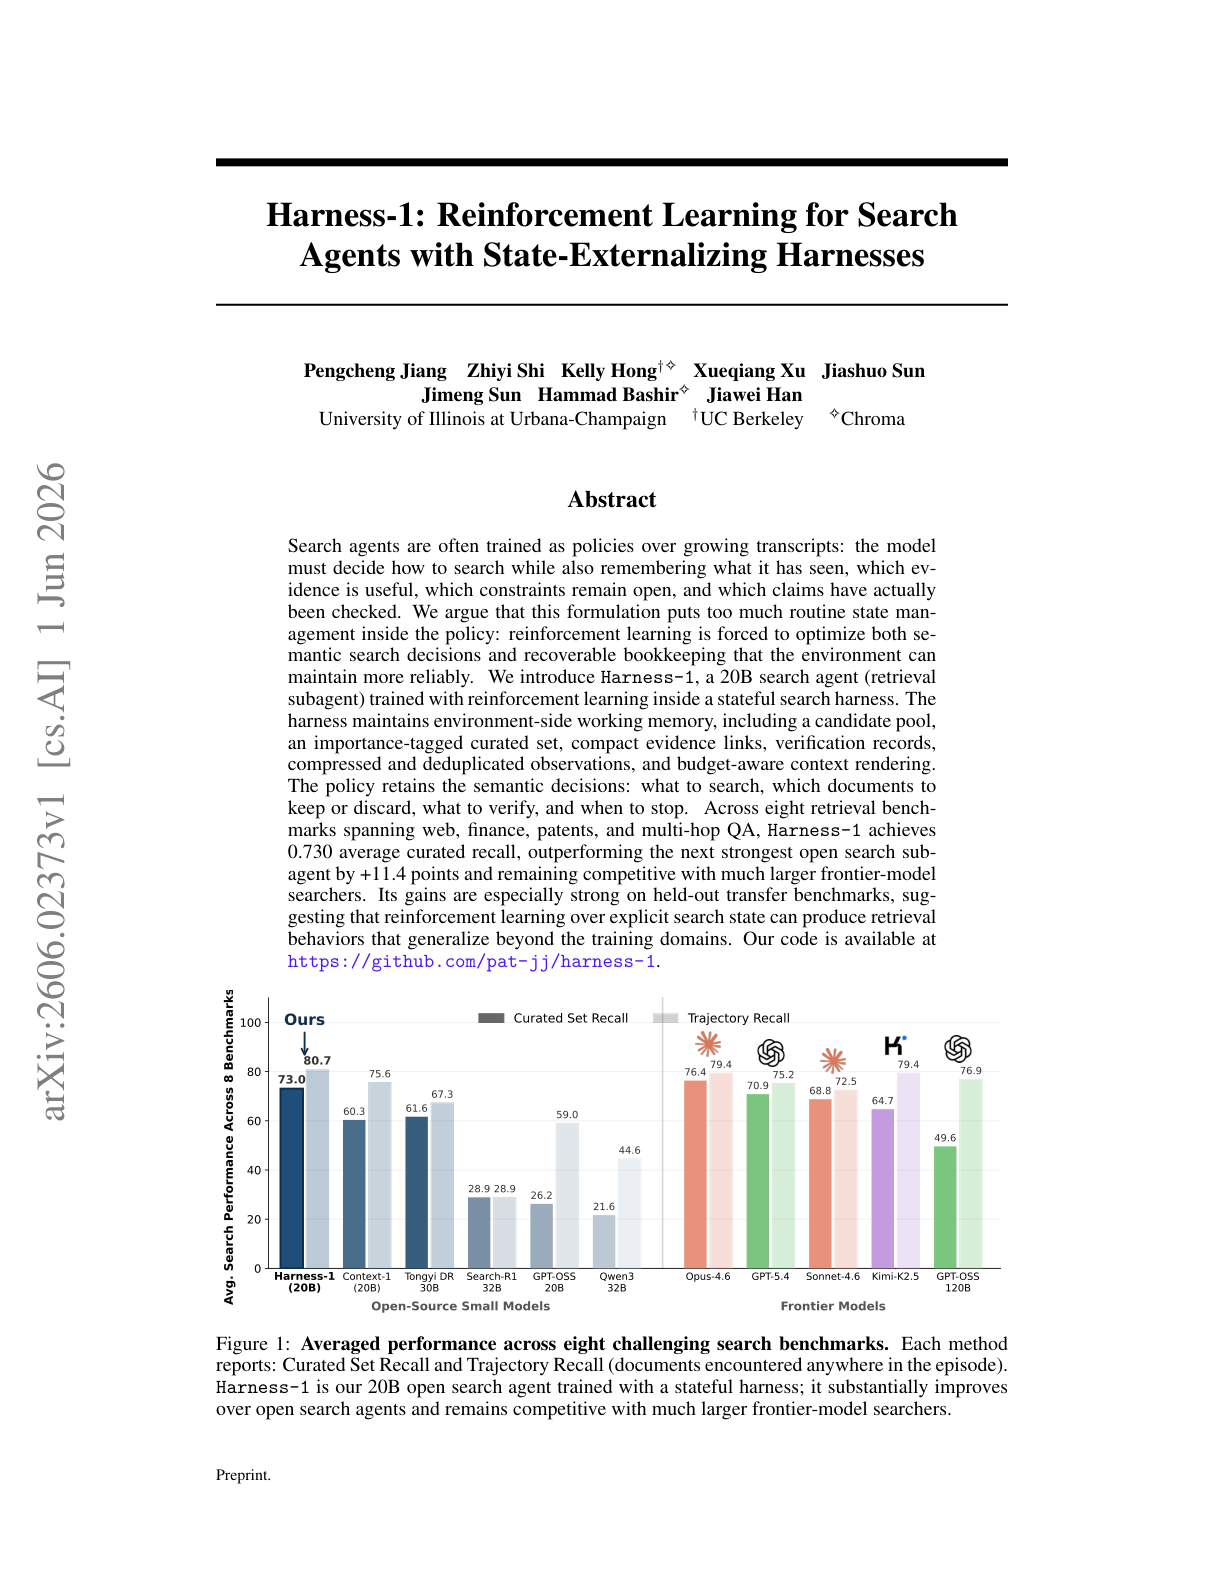
Harness-1 is a 20B search agent trained with reinforcement learning inside a stateful harness that offloads routine bookkeeping to the environment. The argument is that search agents are usually trained as policies over a growing transcript, forcing RL to optimize both genuine search decisions and recoverable state like which evidence is useful or which claims are checked. Harness-1 moves that state out of the policy and into an environment-side working memory of candidate pools, an importance-tagged curated set, compact evidence links, and verification records. The 20B agent reaches an average curated recall of 0.730 across eight retrieval benchmarks, beating open-source baselines by 11.4 points and matching or outperforming much larger frontier searchers, with stronger generalization on unseen domains.