Teaching MLLMs to Think with Images
First page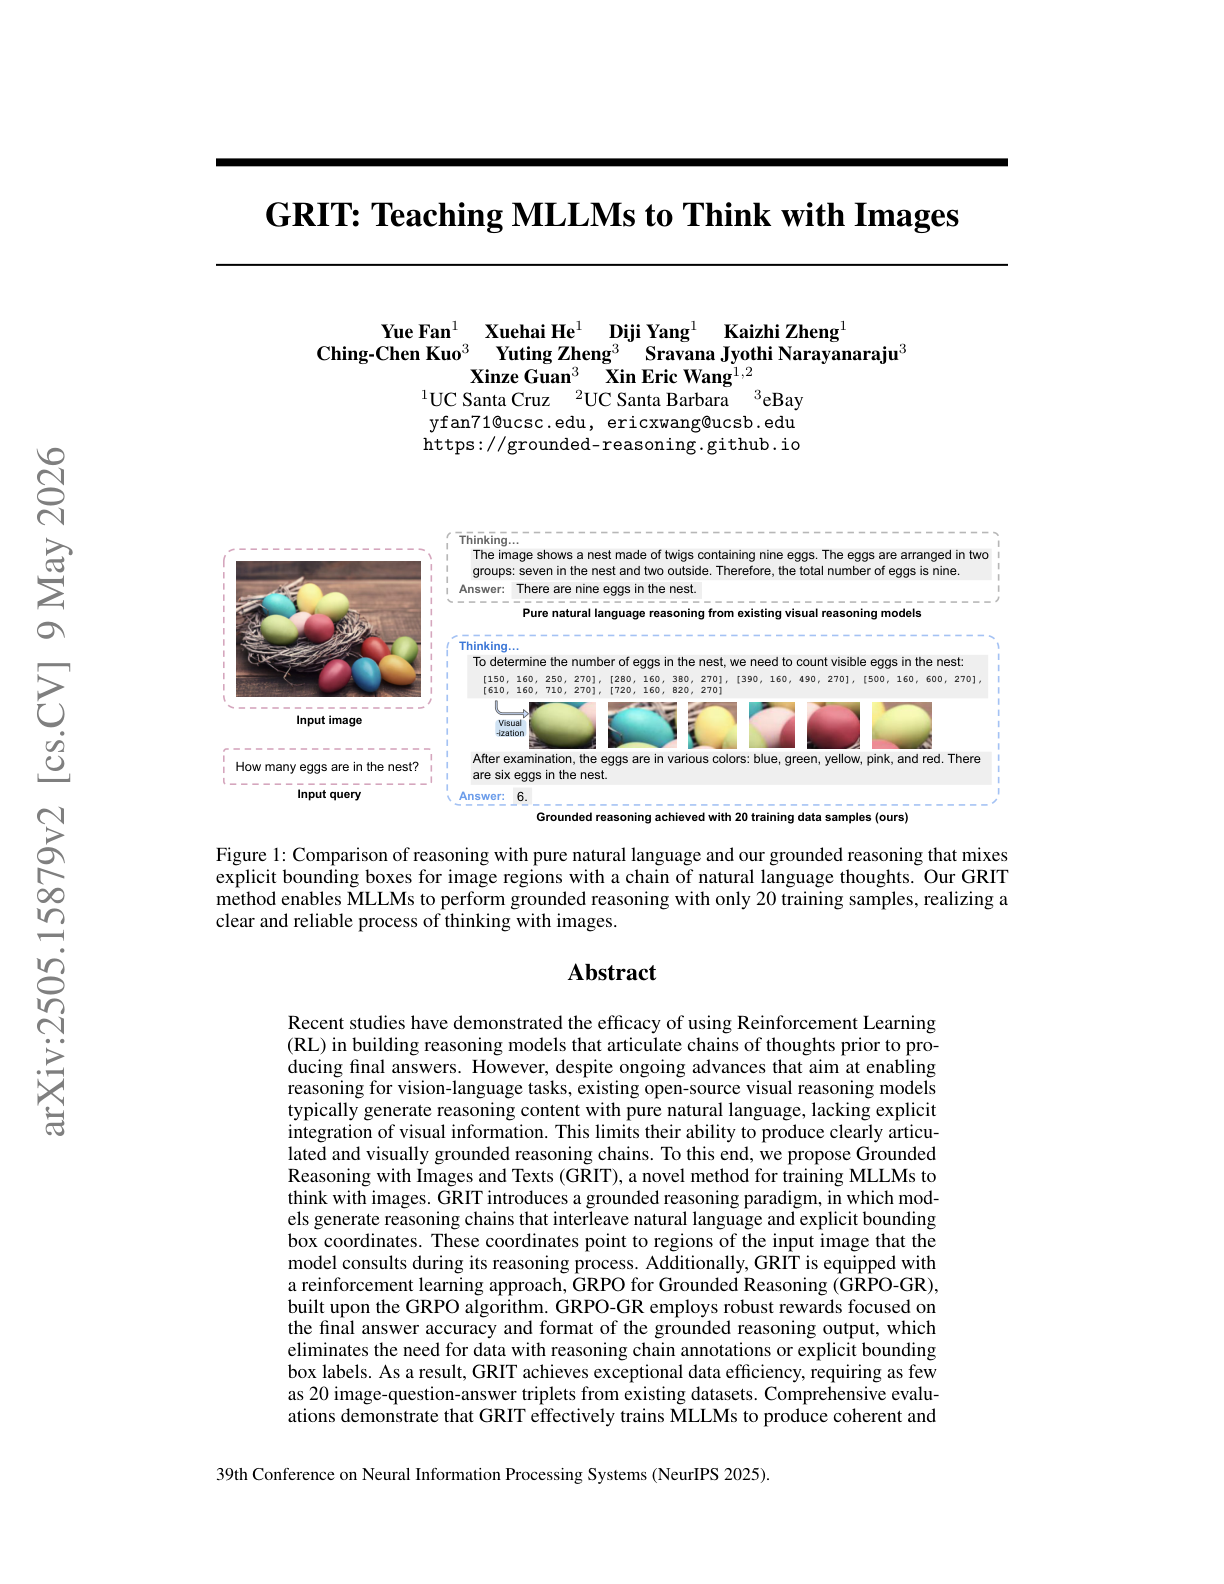
Paper summary
GRIT is a new method that enables MLLMs to perform grounded visual reasoning by interleaving natural language with bounding box references. Using a reinforcement learning approach (GRPO-GR), GRIT achieves strong reasoning and grounding performance with as few as 20 image-question-answer triplets, outperforming baselines in both accuracy and visual coherence.