The Era of Real-World Human Interaction
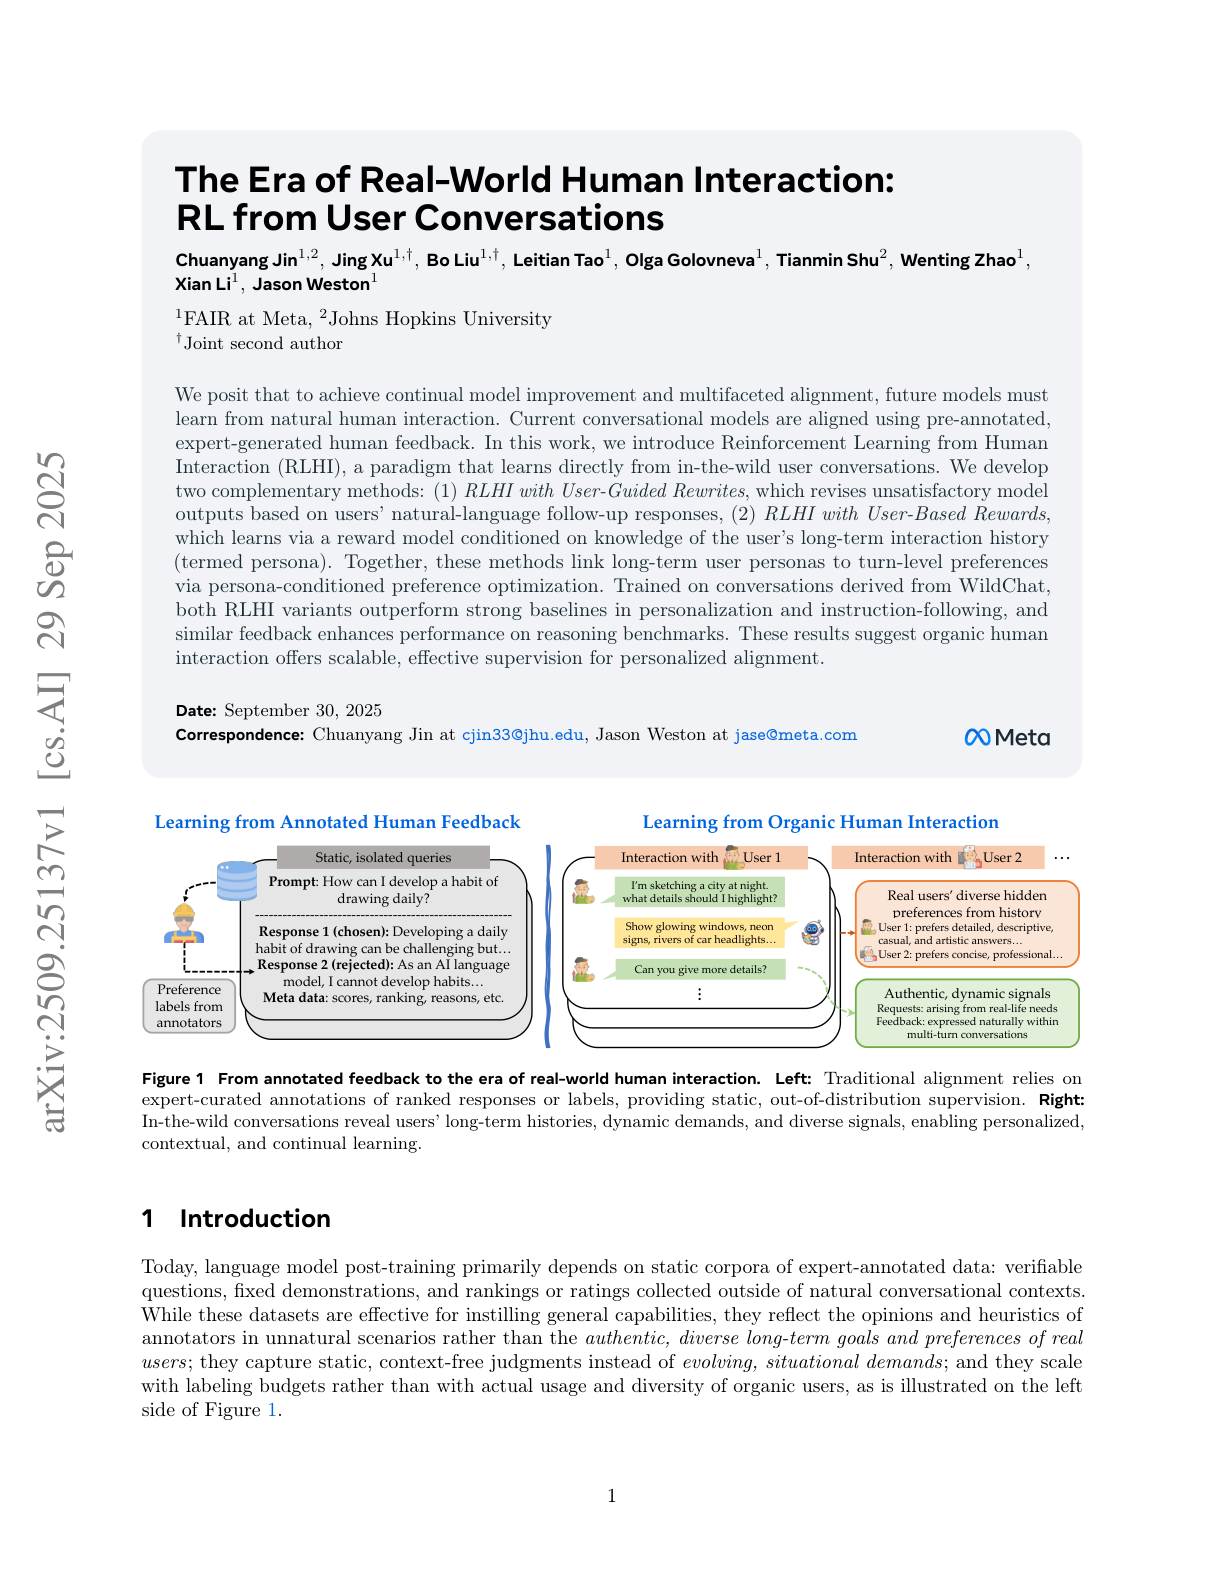
This work presents a post-training recipe that learns directly from real user conversations instead of static annotator labels. RLHI combines user-guided rewrites (using follow-ups as corrections) with persona-based rewards (ranking sampled candidates via a persona-conditioned reward model). Trained on WildChat conversations, it shows strong improvements in personalization, instruction following, and even transfers to reasoning tasks.
Ask this paper
Personas are distilled from long-term user histories and prepended at inference; training uses persona-conditioned DPO on rewrites and reward-ranked pairs.
Real chats contain rich correction signals, especially in later turns, providing dense supervision.
On WildChat-based evaluation, rewrites improve personalization and preference, while persona-based rewards lead in instruction following.
Benchmarks show strong results: 77.9% win rate on AlpacaEval 2.0, competitive on Arena-Hard, and reasoning accuracy rising from 26.5 to 31.8 across math/science datasets.
Key ablations: RL > SFT for interaction data, strong quality filters are essential, and user diversity matters more than depth per user.
Next steps include online continual learning, safer reward modeling, and privacy-preserving personalization.