Training Agents Inside of Scalable World Models
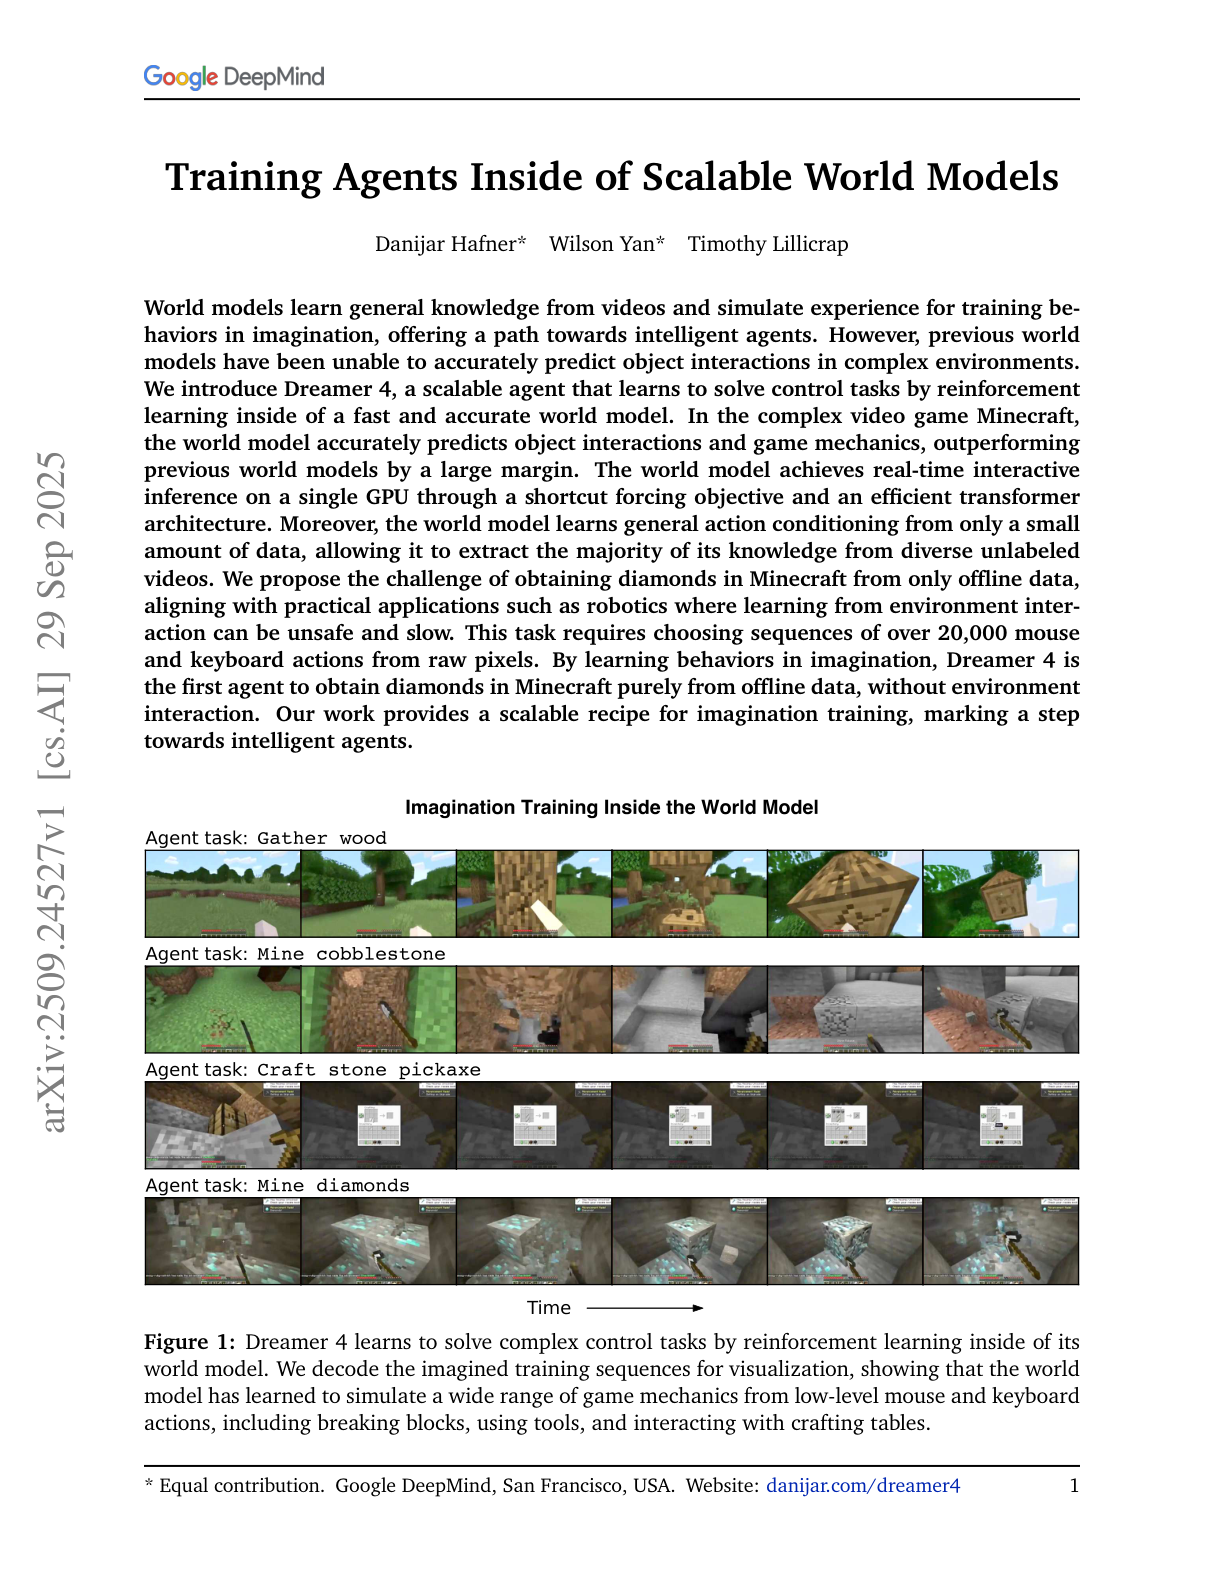
A scalable imagination-RL recipe that learns a fast, accurate Minecraft simulator and trains a controllable agent entirely offline. The world model supports real-time interactive rollouts on a single GPU and enables the first purely offline “get diamonds” result from raw pixels and low-level mouse and keyboard.
Ask this paper
Core recipe, built for speed and stability: Causal tokenizer + block-causal dynamics transformer. Shortcut forcing trains the model to take large denoising steps (K=4) while predicting in x-space with a ramped loss, which cuts accumulation errors and preserves quality at low step counts. Space-only and time-only attention layers, temporal layers once every 4, GQA, and alternating long/short batches keep KV cache small and inference fast.
Real-time, longer-context world model that handles mechanics, not just visuals: Interactive inference at 20+ FPS with a 9.6 s context at 640×360, substantially longer than prior Minecraft models. In human-in-the-loop play tests across 16 tasks, Dreamer 4 succeeds on 14, correctly placing/breaking blocks, switching tools, riding boats, using furnaces, and entering portals, whereas Oasis/Lucid miss many object-interaction tasks.
Offline Diamond Challenge, no environment interaction: Trained only on the 2.5K-hour VPT contractor dataset, the agent is conditioned on task tokens and improved via imagination RL (PMPO with a behavioral prior). It reaches iron pickaxe 29 percent and obtains diamonds 0.7 percent within 60-minute episodes, outperforming strong offline baselines like VPT (finetuned) and a Gemma-3 VLA while using about 100× less data than YouTube-pretrained VPT pipelines.
Action grounding from little paired data generalizes OOD: With 2,541 hours of video but only 100 hours with actions, the model reaches roughly 85 percent PSNR and 100 percent SSIM of the full-action model on action-conditioned prediction. Action conditioning trained only on the Overworld transfers to Nether/End scenes seen without actions, achieving about 76 percent PSNR and 80 percent SSIM of the all-actions model.
Agent finetuning and imagination RL that stay consistent with the model: Task tokens are interleaved with latents, actions, and registers. Heads predict policy, reward, and value with multi-token prediction. Imagination rollouts sample from the frozen world model, and PMPO optimizes sign-based advantages with a reverse-KL to a cloned BC policy, improving robustness and sample efficiency without online data.