Artificial Hippocampus Networks
First page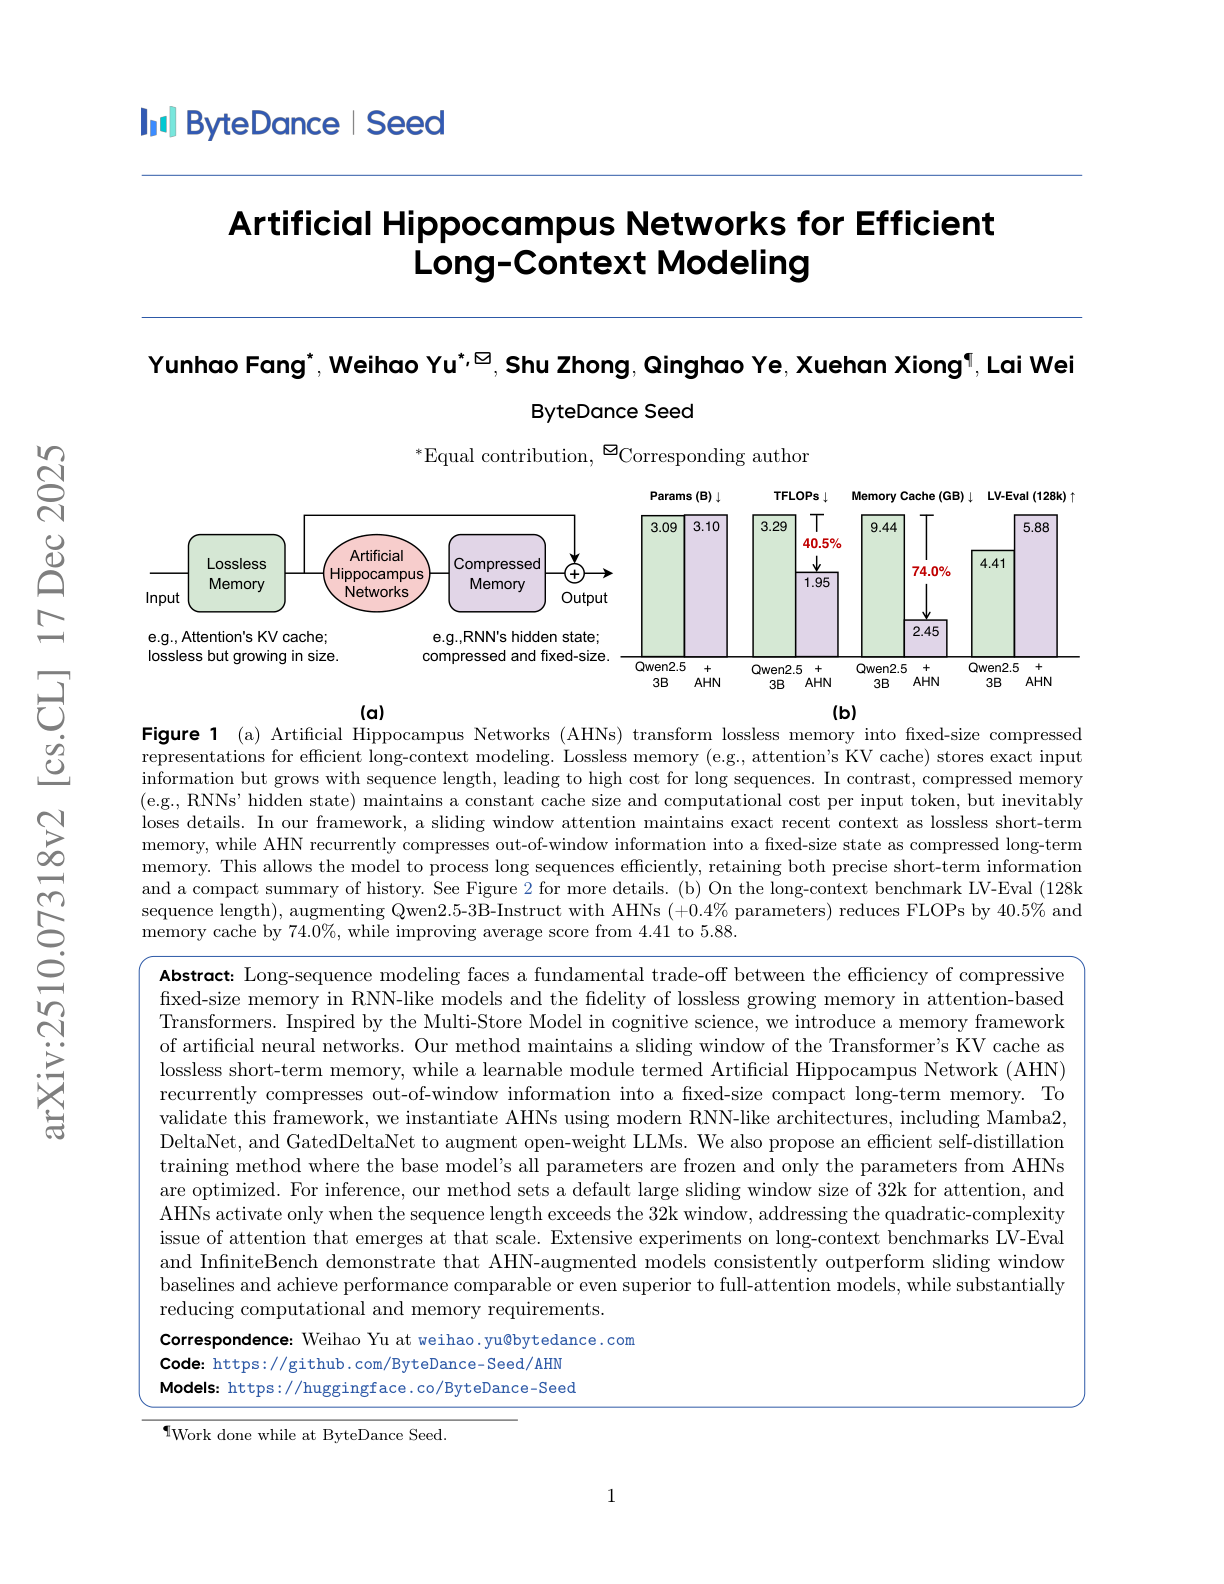
Paper summary
Artificial Hippocampus Networks add a fixed-size recurrent memory to sliding-window Transformers, compressing evicted KV into RNN-like states (Mamba2/DN/GDN) trained via self-distillation for long-context efficiency with constant cache and near-linear compute. On LV-Eval 128k, Qwen2.5-3B + AHN (+0.4% params) cuts FLOPs 40.5% and cache 74% while raising average from 4.41 to 5.88, though exact-recall NIAH tasks still favor full attention.