Avengers-Pro: Beyond GPT-5
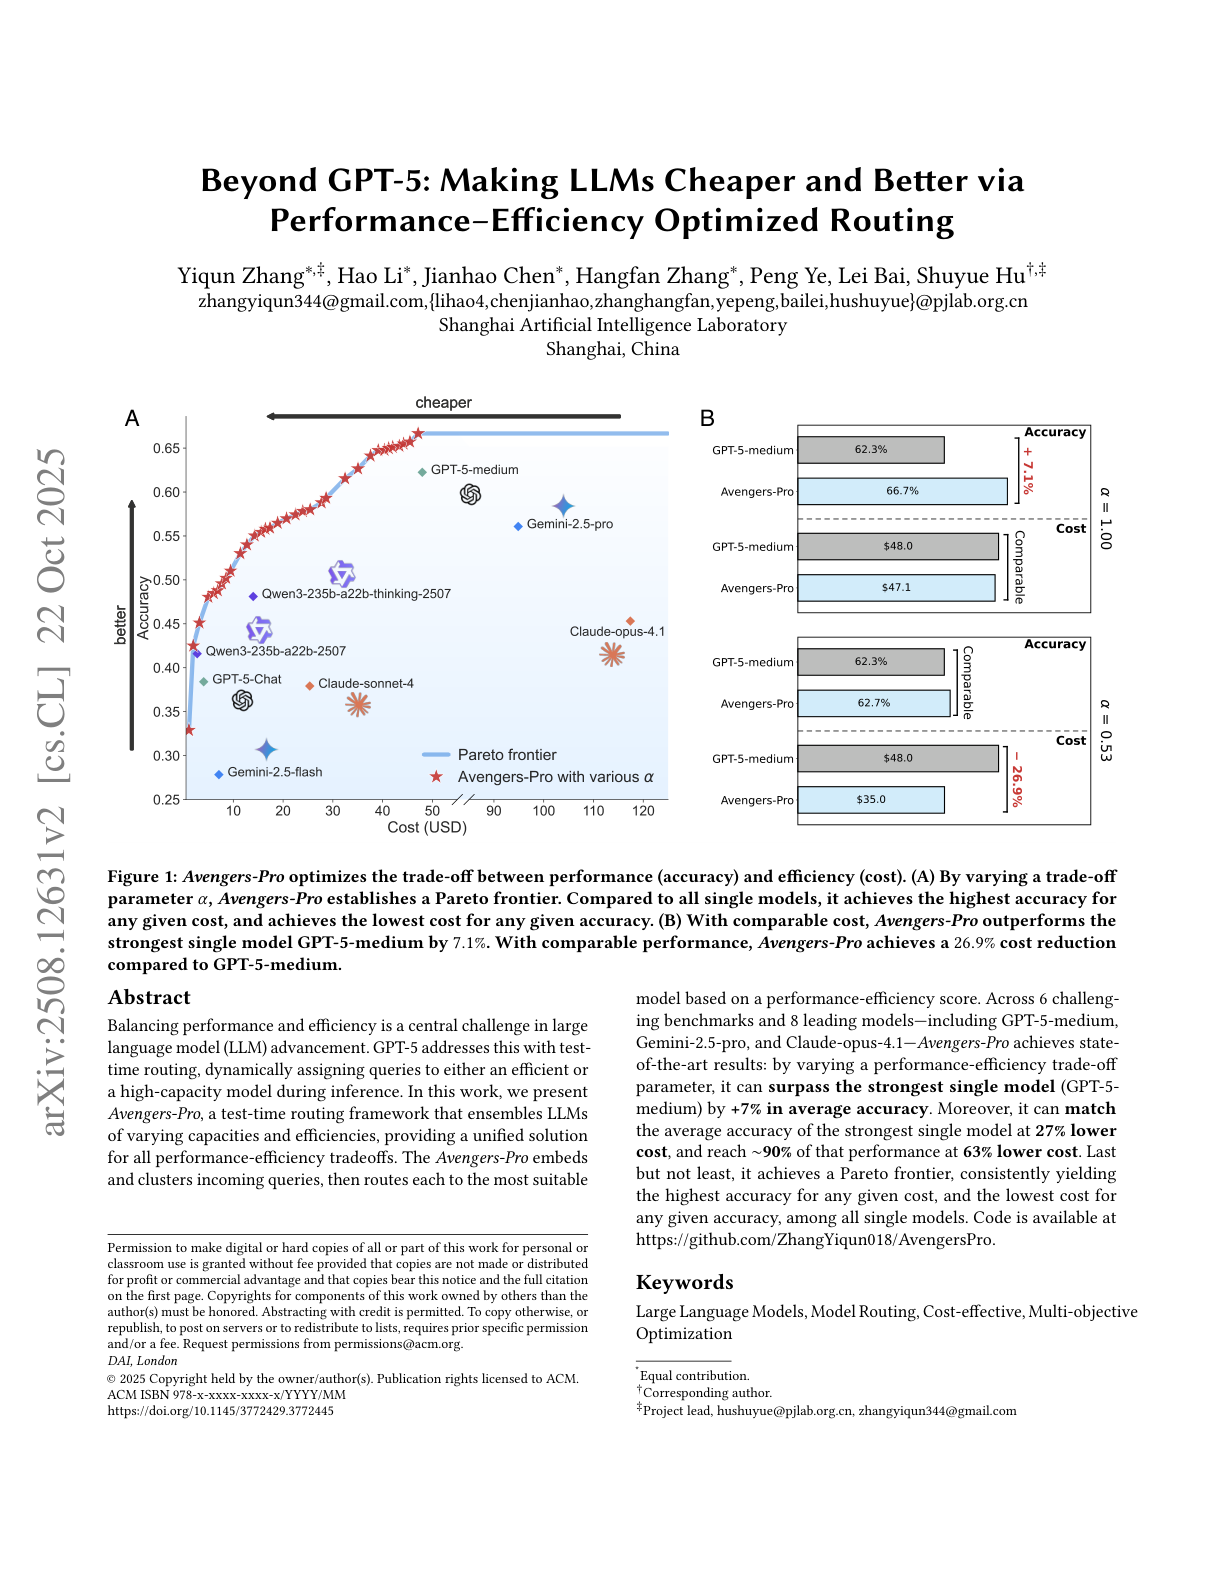
A lightweight test‑time router that embeds each query, maps it to semantic clusters, and selects one LLM from an ensemble to optimize accuracy vs cost. On six hard benchmarks and eight leading models, it beats the best single model at a similar cost and traces a Pareto frontier of accuracy for any budget.
Ask this paper
What it is: Embed → cluster → score. Queries are embedded, assigned to nearest clusters, then routed to the model with the highest performance–efficiency score controlled by a weight α. Only one model answers each query.
Why it matters: With comparable cost, Avengers‑Pro outperforms GPT‑5‑medium by about 7% average accuracy; with comparable accuracy, it reduces cost by about 27%. Hitting ~90% of GPT‑5‑medium’s accuracy costs ~63% less.
Setup: Ensemble of 8 models (GPT‑5‑chat/medium, Claude‑4.1‑opus/Sonnet‑4, Gemini‑2.5‑pro/flash, Qwen3 235B and thinking). Evaluated on GPQA‑Diamond, HLE, ARC‑AGI, SimpleQA, LiveCodeBench, and τ²‑bench. Pricing via OpenRouter informs per‑cluster cost scoring.
Knobs that matter: α tunes performance vs efficiency; accuracy rises fast until ~0.6 while cost stays low until ~0.4, then climbs. Implementation uses k‑means with k=60, Qwen3‑embedding‑8B (4096‑d) and top‑p=4 nearest clusters at inference.
Routing behavior: At low α, the router favors cheaper Qwen3 variants; as α grows, it shifts to GPT‑5‑medium and other stronger but costlier models.