EMO: Emote Portrait Alive
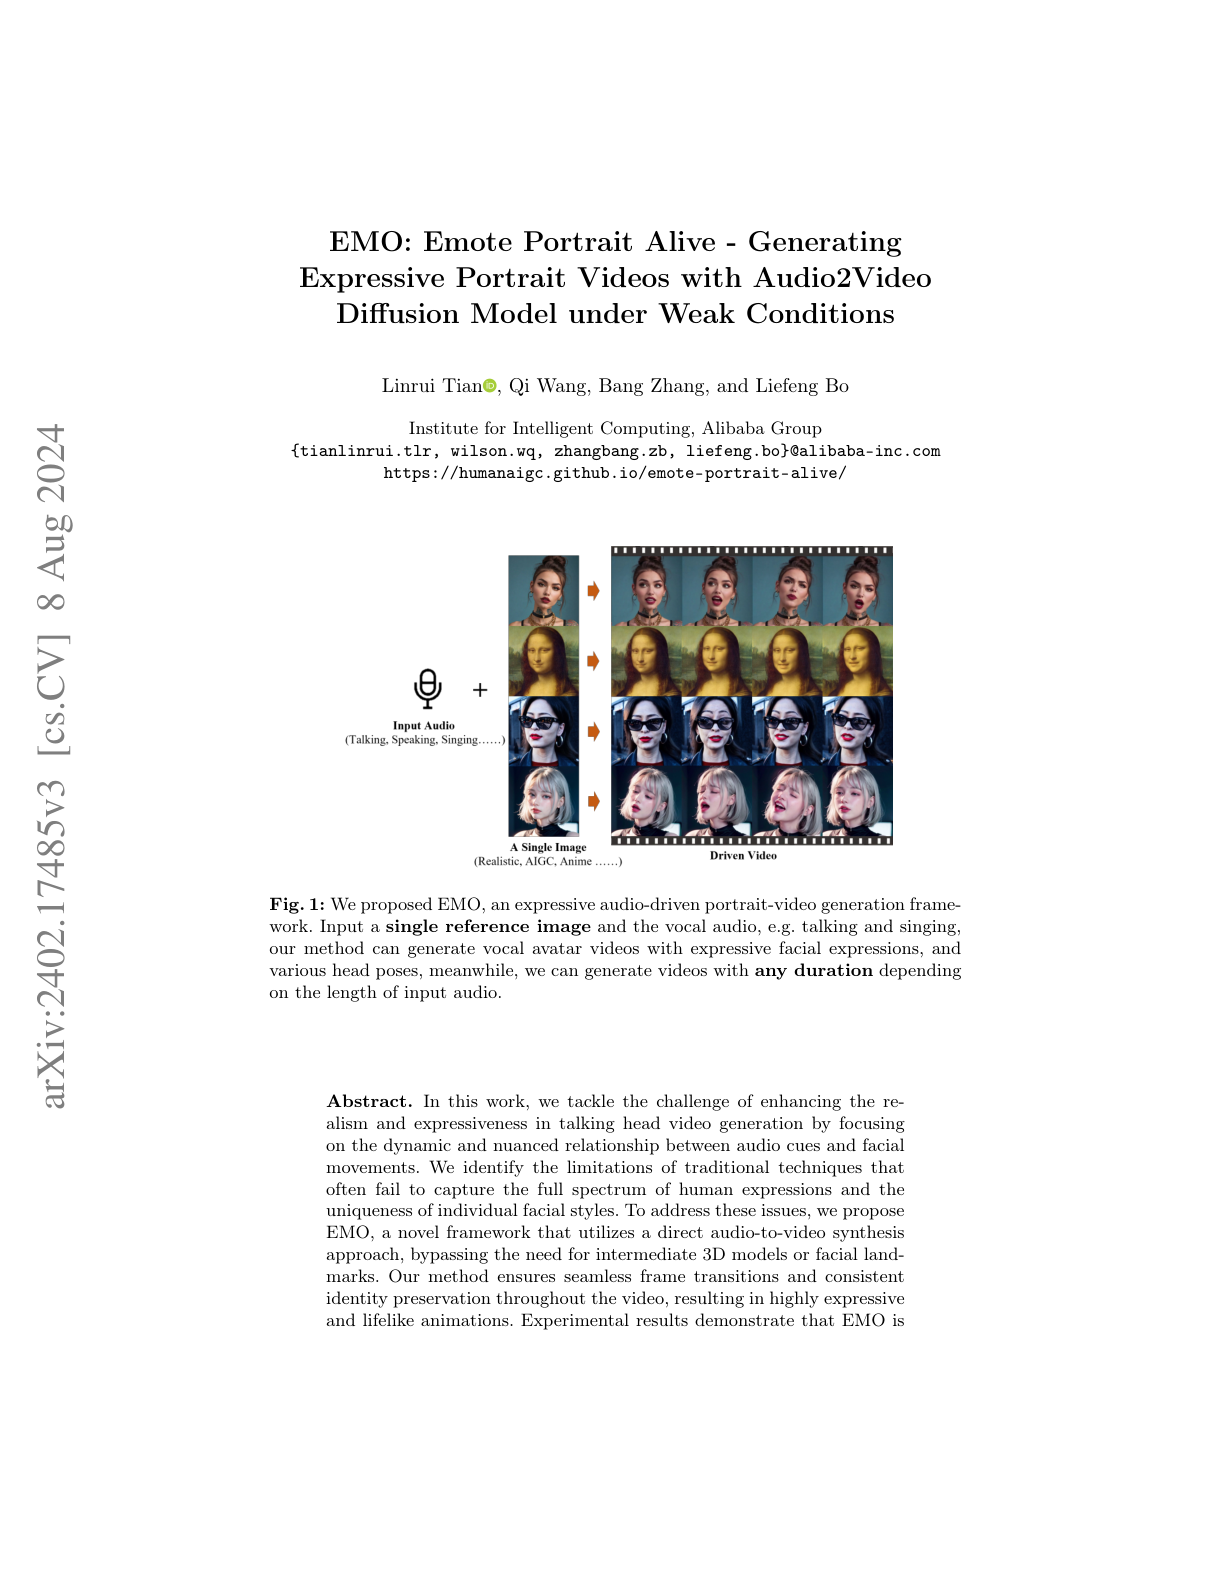
Alibaba's EMO synthesizes expressive talking-head videos directly from audio, bypassing the intermediate 3D models or facial landmarks used by prior approaches.
Ask this paper
Audio2Video diffusion: A single diffusion model maps an audio waveform and a reference portrait directly to a video, letting subtle prosody drive facial motion without a handcrafted intermediate representation.
Speaking and singing: Produces convincing lip-sync and expressive facial motion for both speech and singing across varied styles, handling long-duration audio stably.
Identity preservation: Reports strong identity preservation and seamless frame transitions, outperforming prior methods on expressiveness and realism metrics.
Implications: Shows that eliminating the 3D/landmark intermediate stage - previously thought essential for controllable portraits - can actually improve fidelity and expressiveness for talking-head generation.